<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://toooold.com/feed.xml" rel="self" type="application/atom+xml" /><link href="https://toooold.com/" rel="alternate" type="text/html" /><updated>2026-09-24T18:57:26+00:00</updated><id>https://toooold.com/feed.xml</id><title type="html">Toooold</title><subtitle>to code</subtitle><entry><title type="html">Jev and the Verbalization Tax of JSON</title><link href="https://toooold.com/2026/09/16/jev.html" rel="alternate" type="text/html" title="Jev and the Verbalization Tax of JSON" /><published>2026-09-16T00:00:00+00:00</published><updated>2026-09-16T00:00:00+00:00</updated><id>https://toooold.com/2026/09/16/jev</id><content type="html" xml:base="https://toooold.com/2026/09/16/jev.html"><![CDATA[<p>I became curious about <a href="https://typesafe.ai/blog/introducing-system-one-models-and-jev">Jev</a> because of a JSON inefficiency that appears everywhere in production LLM systems, from threat intelligence to compliance monitoring.</p>

<p>We often send a model thousands of tokens of context so it can return something like:</p>

<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">{</span><span class="w">
  </span><span class="nl">"risk"</span><span class="p">:</span><span class="w"> </span><span class="s2">"high"</span><span class="p">,</span><span class="w">
  </span><span class="nl">"route"</span><span class="p">:</span><span class="w"> </span><span class="s2">"security"</span><span class="p">,</span><span class="w">
  </span><span class="nl">"requires_review"</span><span class="p">:</span><span class="w"> </span><span class="kc">true</span><span class="w">
</span><span class="p">}</span><span class="w">
</span></code></pre></div></div>

<p>The valuable computation is deciding <em>high</em>, <em>security</em>, and <em>true</em>. The rest is a serialization protocol. The model generates braces, keys, quotes, commas, and values token by token, then ordinary software parses those tokens back into typed data.</p>

<p>I think of this as a <strong>verbalization tax</strong>.</p>

<p>Jev is interesting because its core purpose appears to begin one level below language generation: if the consumer is software and the output space is already known, the model can expose decisions directly.</p>

<p><img src="/images/jev.jpg" alt="Chopping the verbalization tax" /></p>

<p>A surprisingly small Qwen experiment captures the first step:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">from</span> <span class="nn">transformers</span> <span class="kn">import</span> <span class="n">AutoTokenizer</span><span class="p">,</span> <span class="n">AutoModelForCausalLM</span>
<span class="kn">import</span> <span class="nn">torch</span>

<span class="n">tok</span> <span class="o">=</span> <span class="n">AutoTokenizer</span><span class="p">.</span><span class="n">from_pretrained</span><span class="p">(</span><span class="s">"Qwen/Qwen3.5-4B"</span><span class="p">)</span>
<span class="n">m</span> <span class="o">=</span> <span class="n">AutoModelForCausalLM</span><span class="p">.</span><span class="n">from_pretrained</span><span class="p">(</span><span class="s">"Qwen/Qwen3.5-4B"</span><span class="p">).</span><span class="nb">eval</span><span class="p">()</span>
<span class="n">x</span> <span class="o">=</span> <span class="n">tok</span><span class="p">(</span><span class="sa">f</span><span class="s">"</span><span class="si">{</span><span class="n">state</span><span class="si">}</span><span class="se">\n</span><span class="si">{</span><span class="n">question</span><span class="si">}</span><span class="se">\n</span><span class="s">A:</span><span class="si">{</span><span class="n">a</span><span class="si">}</span><span class="se">\n</span><span class="s">B:</span><span class="si">{</span><span class="n">b</span><span class="si">}</span><span class="se">\n</span><span class="s">C:</span><span class="si">{</span><span class="n">c</span><span class="si">}</span><span class="se">\n</span><span class="s">Answer:"</span><span class="p">,</span> <span class="n">return_tensors</span><span class="o">=</span><span class="s">"pt"</span><span class="p">)</span>
<span class="n">z</span> <span class="o">=</span> <span class="n">m</span><span class="p">(</span><span class="o">**</span><span class="n">x</span><span class="p">).</span><span class="n">logits</span><span class="p">[</span><span class="mi">0</span><span class="p">,</span> <span class="o">-</span><span class="mi">1</span><span class="p">]</span>
<span class="n">ids</span> <span class="o">=</span> <span class="n">torch</span><span class="p">.</span><span class="n">tensor</span><span class="p">([</span><span class="n">tok</span><span class="p">.</span><span class="n">encode</span><span class="p">(</span><span class="n">c</span><span class="p">,</span> <span class="n">add_special_tokens</span><span class="o">=</span><span class="bp">False</span><span class="p">)[</span><span class="mi">0</span><span class="p">]</span> <span class="k">for</span> <span class="n">c</span> <span class="ow">in</span> <span class="s">"ABC"</span><span class="p">])</span>
<span class="n">p</span> <span class="o">=</span> <span class="n">torch</span><span class="p">.</span><span class="n">softmax</span><span class="p">(</span><span class="n">z</span><span class="p">[</span><span class="n">ids</span><span class="p">],</span> <span class="n">dim</span><span class="o">=</span><span class="mi">0</span><span class="p">)</span>
</code></pre></div></div>

<p>No JSON generation is required. Qwen already calculated the relevant judgment before it generated the first answer token.</p>

<p>That observation gives us a useful starting point for thinking about Jev from first principles.</p>

<h2 id="what-does-a-structured-decision-actually-require">What does a structured decision actually require?</h2>

<p>Consider one field in a schema:</p>

<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">{</span><span class="w">
  </span><span class="nl">"risk"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="s2">"low"</span><span class="p">,</span><span class="w"> </span><span class="s2">"medium"</span><span class="p">,</span><span class="w"> </span><span class="s2">"high"</span><span class="p">]</span><span class="w">
</span><span class="p">}</span><span class="w">
</span></code></pre></div></div>

<p>The underlying problem is simply to estimate:</p>

\[P(y=k \mid s,q,C)\]

<p>where:</p>

<ul>
  <li>$s$ is the state or document,</li>
  <li>$q$ is the question,</li>
  <li>$C={c_1,\ldots,c_K}$ is the set of allowed choices,</li>
  <li>$y$ is the selected decision.</li>
</ul>

<p>For this task, the useful final object is the distribution</p>

\[\mathbf{p}
=
\left[
P(y=c_1),
P(y=c_2),
\ldots,
P(y=c_K)
\right].\]

<p>A normal decoder LLM reaches that decision indirectly.</p>

<p>Given a sequence $x_{1:t}$, the transformer produces a hidden representation</p>

\[h_t = F_{\theta}(x_{1:t}),\]

<p>then projects it across the entire token vocabulary:</p>

\[z_t = W_{\text{vocab}}h_t,\]

<p>and converts those logits into token probabilities:</p>

\[P(x_{t+1}=v)
=
\frac{\exp(z_{t,v})}
{\sum_{u\in V}\exp(z_{t,u})}.\]

<p>One token is produced, appended to the sequence, and the process repeats.</p>

<p>For JSON extraction, this means the model repeatedly performs language-model inference to serialize a decision it may already have represented internally.</p>

<p>If the output requires $M$ generated tokens, a rough runtime decomposition is</p>

\[T_{\text{LLM}}
\approx
T_{\text{prefill}}
+
\sum_{t=1}^{M} T_{\text{decode},t}.\]

<p>Structured generation systems can make this reliable with grammar constraints, JSON schemas, or constrained decoding, but the autoregressive loop remains.</p>

<p>Jev appears to change the target computation itself.</p>

<h2 id="the-first-thing-to-remove-autoregressive-verbalization">The first thing to remove: autoregressive verbalization</h2>

<p>The simplest Qwen reproduction takes the ordinary next-token distribution and reads only the legal answer tokens.</p>

<p>If the prompt maps three semantic choices to the tokens A, B, and C, the model gives us logits</p>

\[z_A,\;z_B,\;z_C.\]

<p>We can immediately compute</p>

\[P(c_i \mid s,q,C)
=
\frac{\exp(z_i)}
{\sum_{j=1}^{K}\exp(z_j)}.\]

<p>The program then constructs the typed result.</p>

<p>This already eliminates the decode loop:</p>

\[T_{\text{decision}}
\approx
T_{\text{prefill}}
+
T_{\text{readout}}.\]

<p>SemIf implements this idea with frozen Qwen models. It performs one native forward pass, reads the final-position logits corresponding to fixed answer slots, and skips answer-token decoding entirely.</p>

<p>This reproduction does not tell us Jev’s internal architecture. It demonstrates something more basic: a normal language model already contains enough semantic machinery to act as a zero-shot decision model if we change how its output is consumed.</p>

<p>That interpretation also lines up with TypeSafe’s public discussion. When Jev was described as a large zero-shot classifier whose output vocabulary is replaced by prescribed decisions, TypeSafe’s founder said that characterization was very accurate.</p>

<h2 id="the-second-thing-to-remove-repeated-understanding-of-the-same-state">The second thing to remove: repeated understanding of the same state</h2>

<p>The larger inefficiency appears when one document produces many fields.</p>

<p>Suppose we want twenty decisions from the same incident report:</p>

\[q_1,q_2,\ldots,q_{20}.\]

<p>A straightforward LLM system effectively computes</p>

\[F_{\theta}(s,q_1),
F_{\theta}(s,q_2),
\ldots,
F_{\theta}(s,q_{20}).\]

<p>Most of the input $s$ is identical.</p>

<p>Current Qwen reproductions improve this through prefix caching. They calculate the state once, preserve its attention state, then evaluate the question suffixes from the shared prefix.</p>

<p>Conceptually, we can write the expensive state computation as</p>

\[H = E_{\theta}(s).\]

<p>Each decision then becomes</p>

\[p_j
=
D_{\phi}(H,q_j,C_j).\]

<p>The desired runtime shape becomes</p>

\[T(N)
\approx
T_{\text{state}}
+
T_{\text{decisions}}(N).\]

<p>The important architectural goal is</p>

\[T_{\text{decisions}}(N)
\ll
T_{\text{state}}\]

<p>for a reasonably large $N$.</p>

<p>That is one of the strongest behavioral clues about Jev. TypeSafe recommends grouping many questions over one state because adding questions has relatively little effect on latency. In one documented long-document example, thirteen questions issued together were dramatically faster than issuing thirteen separate requests.</p>

<p>SemIf reproduces part of this behavior with Qwen prefix caches. Its public benchmark moves from repeated full prompts to shared-state inference and then to parallel suffix evaluation, producing a large throughput improvement without changing the underlying model.</p>

<p>A purpose-built architecture can go further because the questions themselves no longer need to look like normal causal-LM continuations.</p>

<h2 id="the-third-thing-to-remove-the-full-language-vocabulary">The third thing to remove: the full language vocabulary</h2>

<p>The stock-Qwen experiment still carries another legacy of language modeling.</p>

<p>A decoder model computes</p>

\[z=W_{\text{vocab}}h\]

<p>where</p>

\[W_{\text{vocab}}
\in
\mathbb{R}^{|V|\times d}.\]

<p>For modern models, $V$ can exceed one hundred thousand tokens.</p>

<p>If the application has four possible decisions, projecting $h$ across the entire vocabulary and retaining four entries performs unnecessary work.</p>

<p>A decision-native architecture could instead represent each candidate semantically:</p>

\[c_i = G_{\phi}(\text{description}_i)\]

<p>and score it directly against the state representation:</p>

\[s_i
=
f_{\phi}(H,q,c_i).\]

<p>The probability distribution becomes</p>

\[P(y=c_i \mid s,q,C)
=
\frac{\exp(s_i)}
{\sum_{j=1}^{K}\exp(s_j)}.\]

<p>Now the size of the language vocabulary has disappeared from the output computation.</p>

<p>NanoJev explores this direction using Qwen3-0.6B with explicit decision heads. Its implementation evaluates multiple candidate paths and multiple questions through a shared backbone and produces decision distributions without text decoding.</p>

<p><code class="language-plaintext highlighter-rouge">jevlike</code> explores another plausible version in which candidate representations query the state tokens through attention.</p>

<p>Neither project reveals Jev’s private architecture. Both point toward the same computational objective: preserve the semantic representation learned by a language model while giving software a much cheaper readout mechanism.</p>

<h2 id="what-jev-appears-to-add">What Jev appears to add</h2>

<p>Removing generation explains only part of Jev’s usefulness.</p>

<p>The other half is adding structures that ordinary LLMs were never trained to expose cleanly.</p>

<p>The first addition is <strong>typed decision primitives</strong>.</p>

<p>For a categorical choice:</p>

\[\mathbf{p}
=
\operatorname{softmax}
\left(
s_1,\ldots,s_K
\right).\]

<p>For a Boolean decision:</p>

\[P(y=\text{true})
=
\sigma(s).\]

<p>For an ordered score with levels $r_1,\ldots,r_K$:</p>

\[P(y=r_i)
=
\frac{\exp(s_i)}
{\sum_j \exp(s_j)}\]

<p>and the expected score can be calculated as</p>

\[\mathbb{E}[y]
=
\sum_{i=1}^{K}
r_i P(y=r_i).\]

<p>These objects are immediately usable by software.</p>

<p>The second addition is <strong>parallel readout over shared state</strong>. If we have $N$ questions with varying numbers of candidates, the model can conceptually evaluate all candidate scores together:</p>

\[S
=
\left\{
s_{j,k}
\mid
1\le j\le N,\;
1\le k\le K_j
\right\}.\]

<p>Each question then receives its own normalization:</p>

\[P(y_j=c_{j,k})
=
\frac{\exp(s_{j,k})}
{\sum_{m=1}^{K_j}\exp(s_{j,m})}.\]

<p>This maps naturally onto GPU matrix operations. The model can treat many decisions as one batch of semantic reads from the same state representation.</p>

<p>The third addition may be the most consequential: <strong>training for the meaning of the probabilities themselves</strong>.</p>

<h2 id="calibration-changes-what-software-can-do-with-the-model">Calibration changes what software can do with the model</h2>

<p>The probabilities produced by slicing Qwen logits are useful scores, but their numerical values are not automatically calibrated estimates of correctness.</p>

<p>Suppose the model returns</p>

\[P(\text{security})=0.97.\]

<p>For operational use, we would like decisions assigned approximately $0.97$ confidence to be correct roughly $97\%$ of the time under the relevant deployment distribution.</p>

<p>A standard language model was trained mainly through next-token prediction:</p>

\[\mathcal{L}_{\text{LM}}
=
-\sum_t
\log
P_{\theta}(x_t\mid x_{&lt;t}).\]

<p>That objective rewards language prediction.</p>

<p>TypeSafe says Jev uses Reinforcement Learning for Calibrated Decisions, or RLCD, as part of its post-training. The details remain private, so any exact reconstruction would be speculation. The public goal is clear enough: optimize a model whose output distributions can act as useful decision probabilities.</p>

<p>That changes how the result can participate in software.</p>

<p>A system can map confidence ranges to different actions, request human review for uncertain cases, combine several probabilistic judgments, or explicitly trade recall against precision.</p>

<p>The probability distribution becomes part of the API rather than an incidental byproduct of token generation.</p>

<h2 id="my-current-best-guess-of-the-jev-architecture">My current best guess of the Jev architecture</h2>

<p>The public evidence supports a broad computational model more strongly than any particular attention mechanism.</p>

<p>The state is encoded once:</p>

\[H=E_{\theta}(s).\]

<p>Questions and candidates produce decision representations:</p>

\[u_{j,k}
=
G_{\phi}(q_j,c_{j,k}).\]

<p>A lightweight readout compares those representations with the shared state:</p>

\[s_{j,k}
=
R_{\phi}(H,u_{j,k}).\]

<p>Each primitive applies its appropriate normalization:</p>

\[\mathbf{p}_j
=
\operatorname{Normalize}_{\text{type}(j)}
\left(
s_{j,1},\ldots,s_{j,K_j}
\right).\]

<p>The entire call can therefore be summarized as</p>

\[s
\xrightarrow{E_{\theta}}
H
\xrightarrow{\{R_{\phi}(q_j,C_j)\}_{j=1}^{N}}
\{\mathbf{p}_1,\ldots,\mathbf{p}_N\}.\]

<p>This explains several public observations at once: one state can support many cheap questions, arbitrary natural-language candidate descriptions can define new decisions at runtime, no output prose has to be decoded, and post-training can focus directly on the quality of decision distributions.</p>

<p>The exact form of $R_{\phi}$ remains the interesting unknown. It could involve candidate-conditioned attention, specialized decision tokens, a learned classifier over shared hidden states, or something more novel. The current open reproductions show that several implementations can reproduce pieces of the observed behavior.</p>

<h2 id="why-i-liked-jev-and-why-the-idea-is-useful">Why I liked Jev and why the idea is useful</h2>

<p>A large amount of enterprise LLM work has the same underlying structure to convert unstructured information to small typed state. Routing, policy checks, ranking, moderation, risk assessment, document classification, workflow branching, and many parts of information extraction all fit this pattern.</p>

<p>When the answer space is known, generating language creates an avoidable intermediate representation.</p>

<p>The same idea extends naturally to knowledge extraction. Arbitrary spans such as names, dates, or invoice numbers still benefit from span-oriented models such as GLiNER or dedicated extraction models. Once candidate entities and facts exist, a Jev-like decision layer can classify relationships, resolve ambiguous candidates, validate proposed facts, and attach uncertainty.</p>

<p>This gives me a different way to think about the relationship between LLMs and structured software.</p>

<p>Language modeling gave us the semantic representation. Jev explores what happens when the final interface is designed around the program that consumes that representation.</p>

<p>The efficiency gain seems to come from changing where the model spends its computation. Instead of repeatedly decoding a decision into tokens, the model can expose the decision directly. Instead of reprocessing the same state for every question, it can build a shared representation once and reuse it across many decisions. And instead of projecting each hidden state across the entire language vocabulary, it can score only the candidates that matter for the task.</p>

<p>At the same time, Jev appears to add the pieces that structured software actually needs: typed outputs, many decisions read from the same state in parallel, and probabilities trained to carry useful information about uncertainty.</p>

<p>This is my current best guess at the core of Jev. Its significance comes from redesigning the path from model understanding to software action, rather than spending more effort on making autoregressive structured generation faster.</p>

<h2 id="references">References</h2>

<ol>
  <li>
    <p>TypeSafe AI, <em>Introducing System One Models and Jev</em>. <a href="https://typesafe.ai/blog/introducing-system-one-models-and-jev?utm_source=chatgpt.com">TypeSafe AI announcement</a></p>
  </li>
  <li>
    <p>TypeSafe AI documentation, <em>Parallel Questions</em>, demonstrating shared-state batching across 13 questions, and <em>Jev 1.13 Jaggedness</em>, documenting strengths and failure modes. <a href="https://docs.typesafe.ai/cookbooks/parallel_questions?utm_source=chatgpt.com">Parallel Questions cookbook</a> · <a href="https://docs.typesafe.ai/model-jaggedness/jev-1.13?utm_source=chatgpt.com">Jev 1.13 Jaggedness</a></p>
  </li>
  <li>
    <p>TypeSafe / Hacker News launch discussion, including discussion of Jev as a zero-shot decision or classification model and comments from the TypeSafe team about the unpublished architecture. <a href="https://news.ycombinator.com/item?id=49717558&amp;utm_source=chatgpt.com">Hacker News discussion</a></p>
  </li>
  <li>
    <p>Theo Lee, <em>SemIf (formerly OpenJev)</em>, an open Qwen-based reproduction using direct option-logit readout, shared-state prefix caching, and parallel decision evaluation. <a href="https://github.com/TheoLeeCJ/SemIf?utm_source=chatgpt.com">SemIf on GitHub</a></p>
  </li>
  <li>
    <p>TianyuCodings, <em>NanoJev</em>, a Qwen3-0.6B experiment with explicit decision heads, dynamic candidates, zero output-token decoding, and probability-learning experiments. <a href="https://github.com/TianyuCodings/NanoJev?utm_source=chatgpt.com">NanoJev on GitHub</a></p>
  </li>
  <li>
    <p>vinnylarouge, <em>jevlike</em>, an independent experiment using candidate-conditioned attention to build a one-pass scorer over a variable set of text options. <a href="https://github.com/vinnylarouge/jevlike?utm_source=chatgpt.com">jevlike on GitHub</a></p>
  </li>
  <li>
    <p>Eric Zhang, <em>openjev-sglang</em>, a Jev-compatible API implemented with Qwen and SGLang, using radix caching, prefill-oriented serving, and constrained probability readout. <a href="https://github.com/ekzhang/openjev-sglang?utm_source=chatgpt.com">openjev-sglang on GitHub</a></p>
  </li>
</ol>]]></content><author><name></name></author><summary type="html"><![CDATA[I became curious about Jev because of a JSON inefficiency that appears everywhere in production LLM systems, from threat intelligence to compliance monitoring.]]></summary></entry><entry><title type="html">The Phishing Email Was Actually From Google, but Should I Trust It?</title><link href="https://toooold.com/2026/09/10/fake_google_call.html" rel="alternate" type="text/html" title="The Phishing Email Was Actually From Google, but Should I Trust It?" /><published>2026-09-10T00:00:00+00:00</published><updated>2026-09-10T00:00:00+00:00</updated><id>https://toooold.com/2026/09/10/fake_google_call</id><content type="html" xml:base="https://toooold.com/2026/09/10/fake_google_call.html"><![CDATA[<p>Last night I received one of the more interesting phishing attacks I have seen personally. I work as an AI researcher at a cybersecurity company, so after a few steps I became more interested in studying the attack than following the caller’s instructions. Still, I can easily see how this could succeed against someone who is distracted, worried about losing an important Gmail account, or simply trying to cooperate with what appears to be Google’s security team.</p>

<p>The most interesting part was that several things I saw on my phone were genuinely produced by Google. The account recovery prompt was real. The verification request was real. The later security email also came through Google’s infrastructure.</p>

<p>The attacker was exploiting the meaning I would assign to those legitimate messages.</p>

<p>I would describe this technique as <strong>trusted-channel laundering</strong>. An attacker deliberately triggers legitimate security mechanisms from a trusted service, then uses a phone call or another social channel to provide a false explanation of what those mechanisms mean. Instead of constructing a convincing imitation of Google, the attacker gets Google to produce much of the convincing material.</p>

<p><img src="/images/fake_google_call.jpg" alt="Fake Google Call" /></p>

<p>There is an important defense that makes this particular attack much easier to stop. Google’s own current security guidance says very clearly:</p>

<blockquote>
  <p>“Google will never call you about your account security.”</p>
</blockquote>

<p>Google also says it will never call and ask you to read a verification code or approve a device prompt. Even messages from legitimate Google domains should not be interpreted as proof that a caller represents Google.</p>

<p>That simple rule turns out to be extremely relevant to what happened.</p>

<h2 id="step-1-google-calls-me">Step 1: “Google” calls me</h2>

<p>At around 8 PM Pacific time, I received a call from:</p>

<p><strong>650-215-XXXX</strong></p>

<p>The caller ID displayed <strong>Google</strong>.</p>

<p>The person said that someone had recently changed the contact phone number associated with my Gmail account. He told me that Google’s Trust and Safety team would contact me shortly to help secure the account.</p>

<p>A few minutes later, another call arrived from:</p>

<p><strong>347-329-XXXX</strong></p>

<p>This time a man speaking fluent English said he worked for Google’s security team. He explained that somebody had changed the contact information on my Gmail account and that he needed to verify my identity and help me recover it.</p>

<p>I am including both phone numbers because they were the numbers displayed during this incident and may be useful to someone searching for the same scam.</p>

<p>They should not be treated as durable identities for the attackers.</p>

<p>Caller ID names and numbers can be spoofed. A scammer can make a call appear to originate from a different number and can manipulate the displayed caller name. Even if these particular numbers were controlled by the attackers during my call, they can switch numbers at any time. Carriers may block them, Google may take action if its name is being abused, and the numbers themselves may later be reassigned.</p>

<p>So the useful indicator here is:</p>

<p><strong>These were the numbers used in this incident.</strong></p>

<p>The stronger security signal is the behavior that followed.</p>

<p>The timing also felt strange. It was around 8 PM in California and 11 PM in New York. More importantly, I had never asked Google for support.</p>

<h3 id="why-did-they-use-two-calls">Why did they use two calls?</h3>

<p>The first call established the story before the second caller asked me to do anything sensitive.</p>

<p>By the time the supposed Google security engineer appeared, I had already been told that there was an account incident and that another Google employee would contact me.</p>

<p>The second call therefore arrived as an expected event.</p>

<p>That sequencing matters. The attacker was creating context first, then asking for authorization.</p>

<h2 id="step-2-they-made-google-send-me-a-real-recovery-prompt">Step 2: They made Google send me a real recovery prompt</h2>

<p>While “Google Security” was talking to me, my Gmail app displayed a Google account recovery notification.</p>

<p>A device in New York was attempting to recover my account.</p>

<p>That was a real Google prompt.</p>

<p>The caller immediately explained that this was expected because he was working on my recovery case. He told me to click <strong>Yes</strong> because the New York device belonged to the Google security process he had just initiated.</p>

<p>This is where the attack became much more interesting.</p>

<p>Google prompts can be used during account recovery. If Google sees an unusual sign-in or recovery attempt, the prompt can contain information such as the device and approximate location so that the account owner can reject an attempt they did not initiate.</p>

<p>The attacker had triggered exactly the warning that was supposed to protect me, then used the phone call to reinterpret it.</p>

<p>The notification was effectively asking:</p>

<blockquote>
  <p>Someone in New York is trying to recover this account. Is that you?</p>
</blockquote>

<p>The caller’s explanation was:</p>

<blockquote>
  <p>Yes, that is me in New York helping you recover your account.</p>
</blockquote>

<p>The same event now had two possible meanings, and the security outcome depended on which explanation I believed.</p>

<h3 id="why-did-they-use-googles-own-recovery-prompt">Why did they use Google’s own recovery prompt?</h3>

<p>Because a genuine Google notification carries much more credibility than a fake webpage or a phishing email.</p>

<p>Once the victim accepts the premise that the person on the phone represents Google, suspicious information inside the notification can start working in the attacker’s favor.</p>

<p>The location <strong>New York</strong> could have warned me that somebody elsewhere was trying to access my account.</p>

<p>Under the attacker’s explanation, it became evidence that the supposed Google security engineer was doing exactly what he had promised.</p>

<p>That is the core pattern of this attack.</p>

<h2 id="step-3-please-enter-my-job-id-48">Step 3: “Please enter my job ID, 48”</h2>

<p>Then came my favorite part of the attack.</p>

<p>The caller told me that his <strong>Google employee ID was 48</strong> and instructed me to use <code class="language-plaintext highlighter-rouge">48</code> in the authentication prompt.</p>

<p>Of course, <code class="language-plaintext highlighter-rouge">48</code> was functioning as part of Google’s authentication challenge.</p>

<p>Google can use number matching as part of an authentication flow. A number displayed during one part of the transaction must correspond to the trusted device authorizing it.</p>

<p>The attacker gave the number a new meaning.</p>

<p>The security system was effectively saying:</p>

<blockquote>
  <p>Verify that this authentication session is the one you intended to authorize.</p>
</blockquote>

<p>The caller told me:</p>

<blockquote>
  <p>This is my Google employee ID. Enter 48 to verify that I am helping you.</p>
</blockquote>

<p>That is a subtle and effective semantic substitution.</p>

<p>For the victim, typing <code class="language-plaintext highlighter-rouge">48</code> feels almost harmless. There is no password being disclosed, no long OTP being read aloud, and no suspicious website being opened.</p>

<p>It sounds like entering an employee identifier into Google’s own application.</p>

<h3 id="why-did-they-call-48-an-employee-id">Why did they call 48 an “employee ID”?</h3>

<p>People have been trained for years not to share passwords or verification codes.</p>

<p>A two-digit employee ID feels very different.</p>

<p>The attacker did not need to hide the authentication token. He changed the victim’s understanding of what the token represented.</p>

<p>This is one of the most interesting parts of the attack from a security-design perspective.</p>

<p>I refused to enter it.</p>

<h2 id="step-4-when-the-first-path-failed-they-pivoted">Step 4: When the first path failed, they pivoted</h2>

<p>After I questioned the first request, the caller immediately changed approaches.</p>

<p>An unfamiliar Gmail account:</p>

<p><strong><a href="mailto:{something with letters and numbers}@gmail.com">{something with letters and numbers}@gmail.com</a></strong></p>

<p>attempted to establish a recovery relationship involving my email address. Google then sent me another legitimate request related to that recovery process.</p>

<p>There was another verification code involved, and the caller wanted me to provide or confirm it.</p>

<p>Again, I refused.</p>

<p>I am including the Gmail address because it was directly involved in this incident and may help other people identify the same campaign.</p>

<p>Like the phone numbers, however, this email address should be treated as a temporary incident indicator rather than a permanent attacker identity.</p>

<p>The scammer can create another Gmail account at any time. Google may also suspend or remove the account after receiving abuse reports. By the time someone reads this article, <strong><a href="mailto:{something with letters and numbers}@gmail.com">{something with letters and numbers}@gmail.com</a></strong> may already be inactive, or the same group may be using completely different accounts.</p>

<p>The behavior is more durable than the identifier.</p>

<h3 id="why-did-they-switch-to-another-gmail-account">Why did they switch to another Gmail account?</h3>

<p>The first route depended on getting me to authorize recovery of my own account.</p>

<p>Once I refused, the attacker needed another Google workflow capable of generating trusted messages to my inbox.</p>

<p>A recovery-email relationship provides exactly that.</p>

<p>The attacker can initiate an action involving an attacker-controlled Google account, cause Google to send the victim a legitimate message, then explain that message over the phone as part of the victim’s supposed security incident.</p>

<p>This also showed that the person on the phone was not committed to one carefully scripted exploit. He appeared to have several Google account workflows available and was choosing among them interactively based on what I accepted or rejected.</p>

<h2 id="step-5-a-real-google-security-email-appears-to-confirm-james-wilson">Step 5: A real Google security email appears to confirm “James Wilson”</h2>

<p>The next step was the most convincing.</p>

<p>A security alert associated with the unfamiliar account was copied to my email address. The alert concerned an:</p>

<p><strong>“App password created to sign in to your account”</strong></p>

<p>event.</p>

<p>Inside the message was text along the lines of:</p>

<blockquote>
  <p>If you didn’t generate this password for [my email], then please proceed with the current call with Google security agent, {a common US male name}, Case ID: {some number}. More than likely, someone might be using your account.</p>
</blockquote>

<p>At almost exactly the same time, the caller, who had introduced himself as {a common US male name}, told me that he had escalated my security case.</p>

<p>He repeated:</p>

<p><strong>Case ID: 37518</strong></p>

<p>This was a much stronger social-engineering artifact than an ordinary phishing email.</p>

<p>From the victim’s perspective, two apparently independent channels now agree.</p>

<p>The person on the phone says:</p>

<p><strong>{a common US male name}, case {some number}.</strong></p>

<p>A security email delivered through Google’s infrastructure also contains:</p>

<p><strong>{a common US male name}, case {some number}.</strong></p>

<p>The natural interpretation is that Google has authenticated the caller.</p>

<p>That conclusion does not follow.</p>

<p>I have not independently reproduced exactly which attacker-controlled Google field allowed that particular text to appear in the security notification, so I would treat that implementation detail as an open question. It may involve an account-controlled label, application name, metadata field, or another value that Google inserts into a legitimate notification.</p>

<p>The observable security problem does not depend on the exact field.</p>

<p>The attacker found a way to cause legitimate Google infrastructure to deliver a message containing information coordinated with the story being told on the phone.</p>

<h3 id="why-did-they-do-this">Why did they do this?</h3>

<p>Because agreement between independent channels normally increases trust.</p>

<p>If somebody gives you a case number over the phone, and then an apparently independent email from Google contains exactly the same case number, that correlation feels difficult to fake.</p>

<p>The attacker was manufacturing the correlation.</p>

<p>He controlled the action that caused Google’s system to generate the second piece of evidence.</p>

<p>This is where the term <strong>trusted-channel laundering</strong> becomes useful.</p>

<h2 id="trusted-channel-laundering">Trusted-channel laundering</h2>

<p>Traditional phishing often requires an attacker to imitate something trusted.</p>

<p>They may create a fake login page, register a confusing domain, spoof a support email, or reproduce a company’s branding.</p>

<p>This attack has a different structure.</p>

<p>The attacker initiates an action inside a legitimate service.</p>

<p>Google then produces a genuine security artifact.</p>

<p>The attacker remains on another communication channel and explains what the artifact supposedly means.</p>

<p>The flow looks roughly like this:</p>

<p><strong>Attacker action → legitimate Google workflow → genuine Google notification → attacker-provided interpretation</strong></p>

<p>The trusted service supplies authenticity to the artifact.</p>

<p>The attacker supplies the semantics.</p>

<p>The victim sees the two together.</p>

<p>That is what I mean by <strong>trusted-channel laundering</strong>.</p>

<p>The attacker gets some of the credibility of Google’s infrastructure transferred to a story that Google itself never authenticated.</p>

<h2 id="the-deeper-problem-is-semantic-binding">The deeper problem is semantic binding</h2>

<p>From a security research perspective, the most interesting issue is what I would call a <strong>semantic binding failure</strong>.</p>

<p>An authentication system can accurately record that a trusted device approved an action.</p>

<p>The harder question is whether the human operating that device understood the action in the same way the security protocol intended.</p>

<p>During this call, the attacker repeatedly tried to replace the protocol’s meaning with his own.</p>

<p>An account recovery attempt became:</p>

<blockquote>
  <p>Google Security is helping recover your account.</p>
</blockquote>

<p>A number-matching challenge became:</p>

<blockquote>
  <p>Enter my employee job ID.</p>
</blockquote>

<p>A recovery-email verification became:</p>

<blockquote>
  <p>Verify your security case.</p>
</blockquote>

<p>A security notification associated with another account became:</p>

<blockquote>
  <p>Google has confirmed your security representative.</p>
</blockquote>

<p>The security mechanisms can all execute correctly while the human authorizes something based on a false mental model.</p>

<p>This is a useful reminder that authentication involves both protocol integrity and user interpretation.</p>

<h2 id="then-i-asked-for-his-google-ldap">Then I asked for his Google LDAP</h2>

<p>At this point, I decided to test whether the caller could handle something outside his script.</p>

<p>I asked:</p>

<blockquote>
  <p>“What is your Google LDAP?”</p>
</blockquote>

<p>He hung up.</p>

<p>No explanation. No argument. The call simply ended.</p>

<p>For this particular scammer, <strong>LDAP</strong> turned out to be a rather effective magic word.</p>

<p>I would not treat this as a real defense technique.</p>

<p>The next scammer can learn the terminology. They can prepare a believable LDAP identifier, invent one confidently, or develop a response explaining why they cannot provide it.</p>

<p>The interesting part was that the question moved the interaction away from the protocol the attacker had prepared.</p>

<p>Until that moment, he controlled what happened next. He initiated a Google workflow, knew what I was about to see, and immediately supplied an explanation for it.</p>

<p>An unexpected question reversed that asymmetry for a few seconds.</p>

<p>For someone analyzing the scam, that was useful.</p>

<p>For a normal user, there is a much easier defense: hang up.</p>

<h2 id="google-has-a-help-page-that-describes-this-exact-class-of-scam">Google has a help page that describes this exact class of scam</h2>

<p>Afterward, I looked through Google’s security documentation.</p>

<p>Google has a help page specifically about <strong>Google Account Security Scam via Phone Call</strong>.</p>

<p>The most useful sentence is also the simplest:</p>

<blockquote>
  <p><strong>“Google will never call you about your account security.”</strong></p>
</blockquote>

<p>Google additionally warns users that scammers may send messages from legitimate Google domains to make their claims appear authentic.</p>

<p>That warning is particularly important here.</p>

<p>A message can genuinely originate from Google’s infrastructure because the attacker triggered a legitimate Google workflow.</p>

<p>The origin of the email tells you who delivered the message.</p>

<p>It does not automatically establish who initiated the underlying event, what that event means for your account, or whether the person currently talking to you represents Google.</p>

<p>This is exactly why checking only the sender domain would have been insufficient during this attack.</p>

<h2 id="what-i-think-google-could-strengthen">What I think Google could strengthen</h2>

<p>Google’s security mechanisms gave me enough information to stop the attack. I still think this incident exposes several places where security UX could make the attacker’s semantic manipulation harder.</p>

<h3 id="1-make-user-intent-explicit-in-recovery-prompts">1. Make user intent explicit in recovery prompts</h3>

<p>Instead of only asking:</p>

<p><strong>Are you trying to recover your account?</strong></p>

<p>the prompt could emphasize:</p>

<p><strong>Did you personally initiate this account recovery process on another device?</strong></p>

<p>It could also include:</p>

<p><strong>Google employees will never ask you to approve this prompt during a phone call.</strong></p>

<p>The goal is to bind the approval to an action the user remembers initiating.</p>

<h3 id="2-explain-where-number-matching-values-should-come-from">2. Explain where number matching values should come from</h3>

<p>The weakness of <code class="language-plaintext highlighter-rouge">48</code> was not simply that the number was short.</p>

<p>The problem was that a caller could plausibly assign another meaning to it.</p>

<p>A stronger prompt might say:</p>

<p><strong>Select this number only if it matches the number displayed on the device where you personally initiated sign-in. Never select a number given to you by someone on a phone call.</strong></p>

<p>This tells the user about the expected provenance of the number.</p>

<h3 id="3-treat-new-recovery-relationships-carefully">3. Treat new recovery relationships carefully</h3>

<p>If my email has suddenly become associated with another Google account as a recovery address, subsequent security messages about that account should make the relationship very clear.</p>

<p>Something like:</p>

<p><strong>This security alert concerns another Google account that listed your email as a recovery address. It does not mean that your own Google Account has been compromised.</strong></p>

<p>That one sentence would make this attack significantly harder.</p>

<h3 id="4-visually-isolate-attacker-controlled-text">4. Visually isolate attacker-controlled text</h3>

<p>Any user-controlled field inserted into a security email should be considered potentially adversarial.</p>

<p>Account names, app labels, device names, recovery information, project names, and similar metadata should be visually separated from Google’s own authoritative security instructions.</p>

<p>Otherwise an attacker may be able to place social-engineering text inside a message that inherits the visual authority of a Google security alert.</p>

<h3 id="5-think-beyond-device-possession-toward-intent-verification">5. Think beyond device possession toward intent verification</h3>

<p>Modern authentication systems are increasingly good at confirming that a trusted device participated in an authorization.</p>

<p>Social engineering creates another question:</p>

<p><strong>Did the user understand exactly what operation they were authorizing and who initiated it?</strong></p>

<p>That is a much harder security problem.</p>

<p>This incident provides a clean example because the attacker’s main tool was repeatedly changing the perceived meaning of legitimate authentication events.</p>

<h2 id="what-should-a-user-actually-do">What should a user actually do?</h2>

<p>You do not need to understand trusted-channel laundering, inspect email headers, know Google’s internal terminology, or ask anyone for their LDAP.</p>

<p>Google provides a much simpler rule:</p>

<p><strong>Google will never call you about your account security.</strong></p>

<p>If somebody claiming to be Google Account Security calls you unexpectedly, end the call.</p>

<p>Then open your Google Account security page yourself. Navigate there independently through Google’s app or website and inspect recent security activity.</p>

<p>If an authentication prompt appears that you did not personally initiate, reject it.</p>

<p>Do not read verification codes to someone on the phone.</p>

<p>Do not type a number into a security prompt because a caller tells you that it is their employee ID, case number, job number, or anything else.</p>

<p>If an email from Google arrives while the person is talking to you, inspect the event independently. The fact that Google genuinely delivered the email does not authenticate the caller.</p>

<p>And if you encounter the specific indicators I saw:</p>

<ul>
  <li><strong>650-215-5242</strong></li>
  <li><strong>347-329-3627</strong></li>
  <li><strong><a href="mailto:fredwright726@gmail.com">fredwright726@gmail.com</a></strong></li>
  <li><strong>“James Wilson”</strong></li>
  <li><strong>Case ID 37518</strong></li>
  <li><strong>“job ID 48”</strong></li>
</ul>

<p>they may help connect your incident to the same scam campaign.</p>

<p>Do not rely on them as a blocklist.</p>

<p>Scammers can change phone numbers, caller ID names, email accounts, employee names, case numbers, and scripts very quickly. Google or telephone carriers may also disable some of these identifiers after abuse is reported.</p>

<p>The reusable defense is to recognize the mechanism.</p>

<p>What made this incident interesting to me as both an AI researcher and someone working in security was how little fake infrastructure the attacker actually needed. He could trigger real Google security workflows, observe what I would see next, and provide a carefully prepared interpretation over the phone.</p>

<p>For a few minutes, Google itself was producing many of the artifacts that made his story believable.</p>

<p>That is why a legitimate security message still deserves one more question:</p>

<p><strong>Who caused this message to be sent, and what action am I actually being asked to authorize?</strong></p>]]></content><author><name></name></author><summary type="html"><![CDATA[Last night I received one of the more interesting phishing attacks I have seen personally. I work as an AI researcher at a cybersecurity company, so after a few steps I became more interested in studying the attack than following the caller’s instructions. Still, I can easily see how this could succeed against someone who is distracted, worried about losing an important Gmail account, or simply trying to cooperate with what appears to be Google’s security team.]]></summary></entry><entry><title type="html">Deriving LLM Post-Training from First Principles</title><link href="https://toooold.com/2026/08/26/posttraining.html" rel="alternate" type="text/html" title="Deriving LLM Post-Training from First Principles" /><published>2026-08-26T00:00:00+00:00</published><updated>2026-08-26T00:00:00+00:00</updated><id>https://toooold.com/2026/08/26/posttraining</id><content type="html" xml:base="https://toooold.com/2026/08/26/posttraining.html"><![CDATA[<p>I have been reading Nathan Lambert’s <a href="https://rlhfbook.com/">RLHF Book</a> and following his lecture and video series. What I appreciate most is the way he has systematically organized a rapidly evolving field into an engineering framework. SFT, reward models, PPO, DPO, RLVR, distillation, regularization, infrastructure, and newer agentic methods often appear as separate topics, while his treatment makes their engineering relationships much easier to see.</p>

<p>I wanted to approach the same landscape from a complementary direction. With my physics background, I naturally ask whether a complicated collection of methods can be reconstructed from a small set of primitives, like Coulomb’s law for classical electromagnetism. One can begin with a simple interaction such as $F = k_e \frac{q_1 \times q_2}{r^2}$, then introduce additional structure only when the current description becomes insufficient. To be clear: Maxwell’s equations are not derived from Coulomb’s law alone, but we haven’t had Maxwell’s equations for LLM, right?</p>

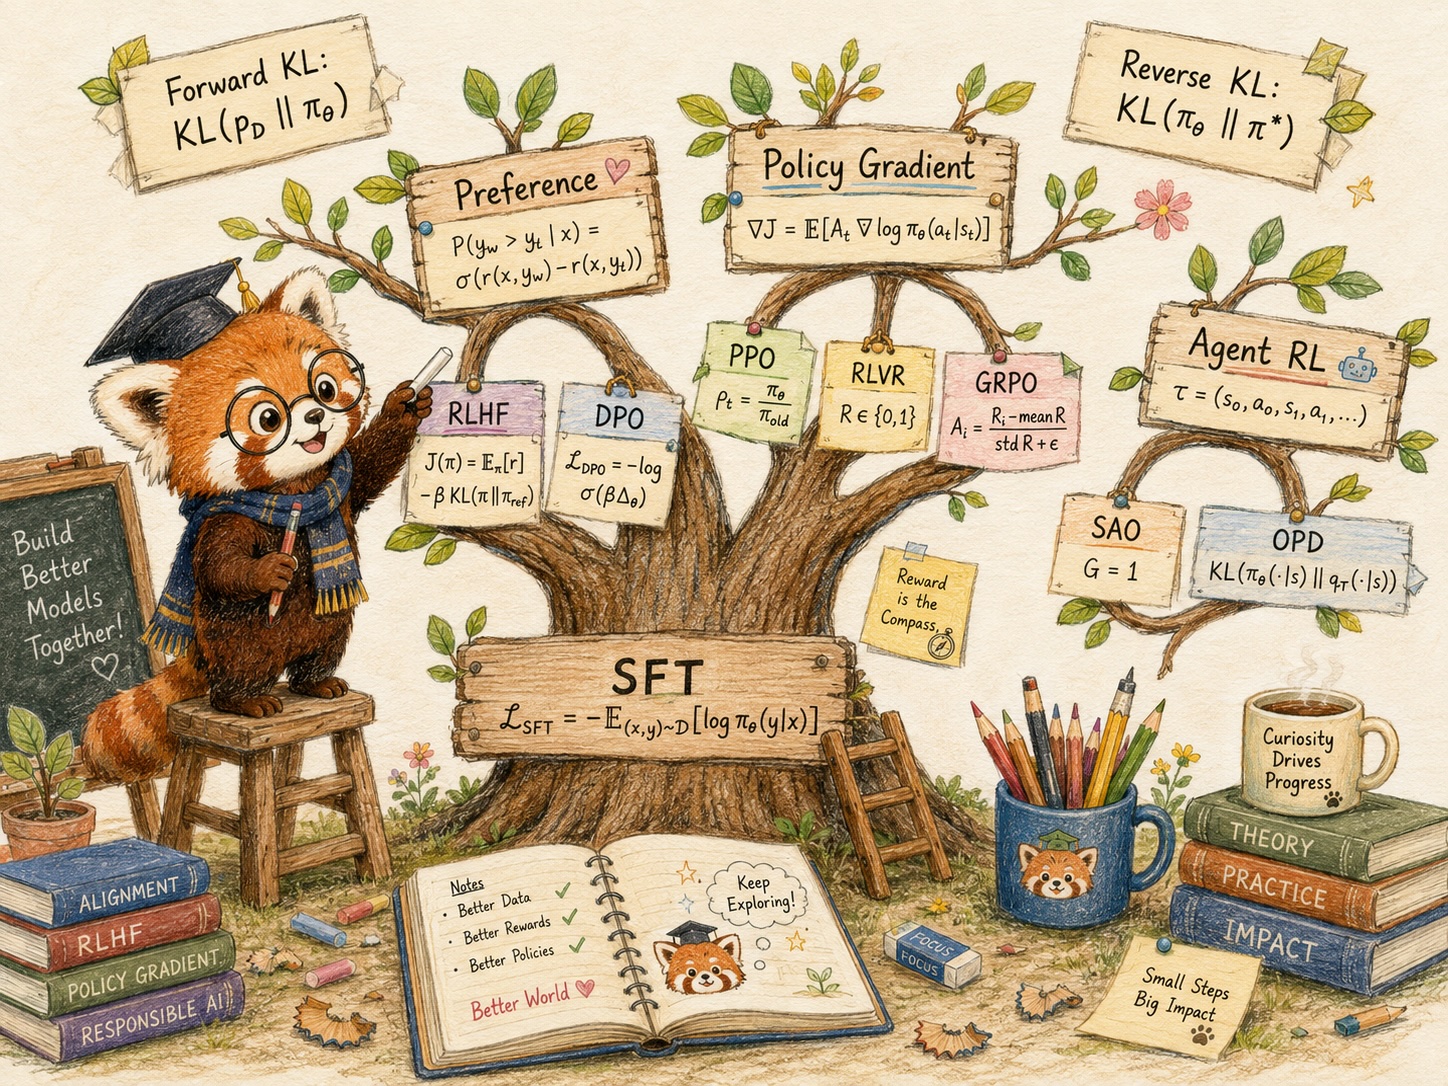
<p><img src="/images/posttraining.jpg" alt="alt text" /></p>

<p>Start from SFT and cross-entropy, ask exactly what information it contains, identify what it cannot express, then add one new degree of freedom at a time. Following that path, much of modern post-training can be organized around four conceptual transitions: from likelihood to preference, from offline projection to on-policy optimization, from sequence generation to environment interaction, and from scalar reward to distributional feedback. The individual algorithms then become branches of these transitions rather than isolated inventions.</p>

<p>This post works like an equation heavy note, but don’t be afraid. I will use a small set of annotations consistently: $x$ denotes the input or prompt, $y$ a generated response, $a_t$ the token or action taken at step $t$, and $s_t$ the corresponding model state or interaction context. The policy is $\pi_\theta$, while $p_{\mathcal D}$ denotes an external data distribution. Rewards are written as $R$ or $r$, advantages as $A_t$, and $\pi_{\mathrm{ref}}$ denotes a reference policy when one is needed. For agentic settings, $\tau$ denotes a full trajectory and $P_{\mathrm{env}}$ the environment transition dynamics. I will use $D_{\mathrm{KL}}(p\Vert q)$ in the standard direction, with the first argument defining the sampling distribution inside the expectation.</p>

<p>Disclaimer: this post is edited with LLM assistance.</p>

<h1 id="i-from-likelihood-to-preference">I. From likelihood to preference</h1>

<h2 id="cross-entropy-as-the-primitive-interaction">Cross-entropy as the primitive interaction</h2>

<p>Let an autoregressive policy be (as in many GPT-style models)</p>

\[\pi_\theta(y\mid x)
=
\prod_{t=1}^{T}
\pi_\theta(y_t\mid x,y_{&lt;t}).\]

<p>Given demonstrations sampled from a data distribution,</p>

\[(x,y)\sim p_{\mathcal D},\]

<p>supervised fine-tuning minimizes</p>

\[\mathcal L_{\mathrm{SFT}}
=
-
\mathbb E_{(x,y)\sim p_{\mathcal D}}
\left[
\log \pi_\theta(y\mid x)
\right].\]

<p>At token level,</p>

\[\mathcal L_{\mathrm{SFT}}
=
-
\mathbb E
\left[
\sum_t
\log \pi_\theta(y_t\mid x,y_{&lt;t})
\right].\]

<p>The objective contains a remarkably simple form of supervision. At each training state, the data identifies a target token and increases its probability. If</p>

\[p_v=\operatorname{softmax}(z)_v,\]

<p>then the gradient with respect to a logit is (p-y) in numpy or:</p>

\[\frac{\partial \mathcal L}{\partial z_v}
=
p_v-\mathbf 1[v=y^*].\]

<p>The target token is pushed upward in probability, while alternatives are suppressed through softmax normalization. This is enough to support imitation, instruction following, and large amounts of behavioral shaping because the pretrained model already contains a rich distribution of latent capabilities.</p>

<p>The limitation follows from the same equation. Cross-entropy identifies a target but carries no explicit representation of relative quality among alternatives. Suppose two complete responses $y_A$ and $y_B$ are both plausible, while one is more factual, more concise, safer, or better calibrated. If the dataset contains only $y_B$, the optimization increases its likelihood, but the loss does not directly encode the relation</p>

\[y_B \succ y_A.\]

<p>This becomes important whenever post-training is less about teaching an unseen capability and more about shifting probability between behaviors that already exist in the pretrained model. That missing relational structure motivates preference optimization.</p>

<h2 id="preference-introduces-a-relative-coordinate">Preference introduces a relative coordinate</h2>

<p>A preference pair adds the ordering</p>

\[y_w \succ y_l.\]

<p>A common latent-variable model represents this ordering through a scalar reward</p>

\[r_\phi(x,y),\]

<p>with pairwise preference probability</p>

\[P(y_w\succ y_l\mid x)
=
\sigma
\left(
r_\phi(x,y_w)-r_\phi(x,y_l)
\right).\]

<p>The corresponding loss is</p>

\[\mathcal L_{\mathrm{RM}}
=
-
\mathbb E
\left[
\log
\sigma
\left(
r_\phi(x,y_w)-r_\phi(x,y_l)
\right)
\right].\]

<p>The important change is that supervision now constrains a difference between behaviors rather than simply assigning one behavior positive probability. SFT provides an absolute target $y^*$, while preference learning constrains the relative direction $y_w-y_l$. This is a more natural representation for many alignment problems because the pretrained model may already support both candidate behaviors. The remaining task is to move the decision boundary.</p>

<p>That distinction applies to properties such as factuality, verbosity, tone, refusal boundaries, confidence calibration, formatting, and tool-use style. Preference data is useful precisely because these dimensions often live inside an existing behavioral manifold rather than outside it.</p>

<h2 id="rlhf-turns-preference-into-a-policy-objective">RLHF turns preference into a policy objective</h2>

<p>Once a reward model provides a scalar estimate of preference, the natural next step is to optimize the policy against it:</p>

\[\max_\pi
\mathbb E_{y\sim\pi}
[r(x,y)].\]

<p>For a large pretrained model, unconstrained reward maximization can move the policy into poorly modeled regions of behavior space. The reward model is an approximation, so aggressive optimization may exploit inaccuracies in the reward surface or damage useful capabilities inherited from pretraining. KL-regularized RLHF addresses this by adding a reference policy:</p>

\[\mathcal J(\pi)
=
\mathbb E_{y\sim\pi}
[r(x,y)]
-
\beta
D_{\mathrm{KL}}
\left(
\pi
\Vert
\pi_{\mathrm{ref}}
\right).\]

<p>The reward defines a direction of improvement, while the KL term controls how far the policy can move away from a known distribution. More importantly for the framework developed here, the expectation is taken over samples from the policy being optimized. This begins a shift in the source of training experience, from externally supplied demonstrations toward behavior generated by the model itself.</p>

<p>The optimization problem also has a useful closed-form optimum:</p>

\[\pi^*(y\mid x)
=
\frac{1}{Z(x)}
\pi_{\mathrm{ref}}(y\mid x)
\exp
\left(
\frac{r(x,y)}{\beta}
\right).\]

<p>Equivalently,</p>

\[r(x,y)
=
\beta
\log
\frac{
\pi^*(y\mid x)
}{
\pi_{\mathrm{ref}}(y\mid x)
}
+
\beta\log Z(x).\]

<p>That relationship provides the starting point for DPO.</p>

<h2 id="dpo-as-an-analytical-branch-of-the-rlhf-objective">DPO as an analytical branch of the RLHF objective</h2>

<p>DPO substitutes the optimal-policy relation directly into the preference model. Define</p>

\[\Delta_\theta
=
\log
\frac{
\pi_\theta(y_w\mid x)
}{
\pi_{\mathrm{ref}}(y_w\mid x)
}
-
\log
\frac{
\pi_\theta(y_l\mid x)
}{
\pi_{\mathrm{ref}}(y_l\mid x)
}.\]

<p>The DPO objective becomes</p>

\[\mathcal L_{\mathrm{DPO}}
=
-
\mathbb E
\left[
\log\sigma
\left(
\beta\Delta_\theta
\right)
\right].\]

<p>Its gradient has the structure</p>

\[\nabla_\theta\mathcal L_{\mathrm{DPO}}
\propto
-
\alpha
\left[
\nabla_\theta\log\pi_\theta(y_w\mid x)
-
\nabla_\theta\log\pi_\theta(y_l\mid x)
\right],\]

<p>where</p>

\[\alpha
=
\beta
\sigma(-\beta\Delta_\theta).\]

<p>Compared with SFT, the essential difference is visible directly in the gradient. Supervised learning reinforces a demonstrated response, while DPO applies <strong>opposite</strong> relative pressure to the preferred and rejected responses. The update strength also depends on how much the current policy already satisfies the preference ordering. This makes DPO well suited to reshaping boundaries between behaviors that are already supported by the model.</p>

<p>Its place in the broader framework is also precise. The optimal-policy parameterization comes from KL-regularized RL, but the samples usually come from a fixed preference dataset:</p>

\[(x,y_w,y_l)
\sim
\mathcal D_{\mathrm{pref}}.\]

<p>DPO therefore inherits an RL-derived target geometry while retaining offline sampling. This combination explains much of its appeal and also why it behaves differently from online RL when exploration matters. Other “PO”s like SimPO, IPO, KTO, ORPO, and related methods can be viewed as nearby branches that modify the reference policy, margin, pair structure, normalization, or statistical form of this same preference-learning problem.</p>

<p>The first major transition can therefore be summarized as a progression from likelihood, to relative quality, to reward-shaped policy optimization. The next transition changes the source of experience itself.</p>

<h1 id="ii-from-offline-projection-to-on-policy-optimization">II. From offline projection to on-policy optimization</h1>

<h2 id="policy-gradient-changes-who-generates-the-data">Policy gradient changes who generates the data</h2>

<p>Suppose the policy generates its own response,</p>

\[y\sim\pi_\theta(y\mid x),\]

<p>and receives reward</p>

\[R(x,y).\]

<p>The objective is</p>

\[J(\theta)
=
\mathbb E_{y\sim\pi_\theta}
[R(x,y)].\]

<p>Using the log-derivative identity,</p>

\[\nabla_\theta \pi_\theta(y)
=
\pi_\theta(y)
\nabla_\theta\log\pi_\theta(y),\]

<p>we obtain</p>

\[\nabla_\theta J
=
\mathbb E_{y\sim\pi_\theta}
\left[
R(x,y)
\nabla_\theta
\log\pi_\theta(y\mid x)
\right].\]

<p>For an autoregressive policy,</p>

\[\nabla_\theta J
=
\mathbb E
\left[
\sum_t
R
\nabla_\theta
\log\pi_\theta(a_t\mid s_t)
\right].\]

<p>Subtracting a baseline gives</p>

\[A_t=R_t-b_t,\]

<p>and therefore</p>

\[\nabla_\theta J
=
\mathbb E
\left[
\sum_t
A_t
\nabla_\theta
\log\pi_\theta(a_t\mid s_t)
\right].\]

<p>This equation is one of the central roots of modern post-training. The log-probability gradient remains familiar, while the coefficient becomes an advantage rather than a supervised target. The deeper transition is in the expectation itself. Training now occurs on samples produced by the current or recent policy, so the model participates in constructing its own training distribution.</p>

<p>This on-policy structure becomes especially important when useful behaviors are difficult to write down as demonstrations. The model can explore trajectories that were never explicitly supplied by a teacher, and the feedback function determines which of those trajectories are reinforced.</p>

<h2 id="ppo-adds-trust-to-an-on-policy-update">PPO adds trust to an on-policy update</h2>

<p>Rollout data is usually produced by a policy that becomes stale during optimization. If $\pi_{\mathrm{old}}$ generated the sample while $\pi_\theta$ is being updated, the relevant importance ratio is</p>

\[\rho_t
=
\frac{
\pi_\theta(a_t\mid s_t)
}{
\pi_{\mathrm{old}}(a_t\mid s_t)
}.\]

<p>A policy-gradient estimator then contains the factor</p>

\[\rho_t A_t.\]

<p>Large ratios can produce unstable updates because a sample that was reasonable under the rollout policy may become poorly representative of the current policy. PPO controls this through clipping:</p>

\[\mathcal L_{\mathrm{PPO}}
=
-
\mathbb E
\left[
\min
\left(
\rho_t A_t,
\operatorname{clip}
(\rho_t,1-\epsilon,1+\epsilon)
A_t
\right)
\right].\]

<p>At this point the post-training problem contains three distinct ingredients: the distribution that generates experience, the signal used to evaluate that experience, and the mechanism that controls how strongly stale experience can modify the current policy. Many later RL variants can be understood as modifying one of these ingredients rather than introducing a new foundation.</p>

<p>The PPO clipping mechanism should also be distinguished from the KL penalty used in classical RLHF. Clipping constrains local updates relative to the rollout policy, while the KL penalty controls global drift from a reference model. They solve different regularization problems inside the same broader optimization system.</p>

<h2 id="rlvr-and-grpo-modify-different-parts-of-the-same-equation">RLVR and GRPO modify different parts of the same equation</h2>

<p>RLVR changes the origin of reward. If a task admits an external verifier, reward can be defined directly from an observable outcome:</p>

\[R(x,y)
=
\begin{cases}
1, &amp; \text{verified success},\\
0, &amp; \text{failure}.
\end{cases}\]

<p>The policy-gradient structure remains</p>

\[\nabla J
=
\mathbb E_{\pi_\theta}
\left[
A_{\mathrm{verifier}}
\nabla_\theta
\log\pi_\theta
\right].\]

<p>The scientific improvement lies in the measurement process used to construct the advantage. Learned reward models estimate quality, while verifiers can connect reward to an externally checkable state. This is why mathematics, coding, formal verification, and some tool-use tasks provide particularly productive environments for RL.</p>

<p>GRPO modifies a different component. PPO often uses a learned value function $V_\phi(s)$ to estimate advantages, while GRPO uses multiple samples from the same prompt to create a relative baseline. Given rewards</p>

\[R_1,\ldots,R_G,\]

<p>a group-relative advantage can be written as</p>

\[A_i
=
\frac{
R_i-\bar R
}{
\sigma_R+\epsilon
}.\]

<p>The policy-gradient structure remains the same, while the estimator of $A$ changes:</p>

\[A_{\mathrm{critic}}
\rightarrow
A_{\mathrm{group}}.\]

<p>This distinction is useful because it separates two kinds of innovation that are often discussed together. RLVR improves the source of the reward signal, while GRPO changes the way that signal is converted into relative credit. GSPO, CISPO, and related methods continue this pattern by modifying ratio granularity, clipping behavior, normalization, or other terms inside the same on-policy framework.</p>

<h1 id="iii-from-sequences-to-dynamical-systems">III. From sequences to dynamical systems</h1>

<h2 id="agent-rl-introduces-environment-dynamics">Agent RL introduces environment dynamics</h2>

<p>A reasoning task can often be approximated as a generation followed by evaluation:</p>

\[x
\rightarrow
y
\rightarrow
R(y).\]

<p>An agent interacts repeatedly with an external state. Its trajectory can be written as</p>

\[\tau
=
(s_0,a_0,s_1,a_1,\ldots,s_T,a_T),\]

<p>with environment dynamics</p>

\[P_{\mathrm{env}}
(s_{t+1}\mid s_t,a_t).\]

<p>The optimization objective becomes</p>

\[J(\theta)
=
\mathbb E_{
\tau\sim
(\pi_\theta,P_{\mathrm{env}})
}
[R(\tau)].\]

<p>The corresponding gradient remains familiar:</p>

\[\nabla_\theta J
=
\mathbb E_\tau
\left[
\sum_t
A_t
\nabla_\theta
\log\pi_\theta(a_t\mid s_t)
\right].\]

<p>The major new object is the environment transition process. For a coding agent, the next state depends on files edited, commands executed, compiler errors, tests, and previous tool calls. For a research or computer-use agent, future states similarly depend on earlier actions. The model therefore helps determine the distribution of states on which future learning occurs.</p>

<p>This makes agentic post-training a coupled dynamical system. Policy quality alone no longer determines the training distribution. The reachable state space is jointly determined by the policy and the environment.</p>

<h2 id="environment-design-becomes-part-of-the-learning-problem">Environment design becomes part of the learning problem</h2>

<p>Once trajectories are sampled from both $\pi_\theta$ and $P_{\mathrm{env}}$, the quality of the environment becomes a first-class training variable. This is where recent GLM work is especially instructive. GLM-5.3 keeps the GLM-5.2 base model while scaling post-training through more environments, greater task diversity, more rollout compute, stronger verifier construction, and better long-horizon infrastructure.</p>

<p>This suggests a useful analogy with pretraining. Pretraining capability depends strongly on the interaction among model, data, and compute. Agentic post-training increasingly depends on policy, environment, verifier, and rollout compute:</p>

\[C_{\mathrm{post}}
=
g(
\pi_\theta,
P_{\mathrm{env}},
R,
\text{rollout compute}
).\]

<p>The environment determines which states can be reached, the verifier determines which trajectories become informative, rollout compute determines how much of the state space can be explored, and the optimization algorithm determines how this experience changes the model.</p>

<p>This view also explains why environment generation is more than a data-engineering detail. A model cannot learn a recovery strategy if the training system never generates failure states that require recovery. It cannot learn long-horizon planning if episodes terminate before such behavior matters. Environment design therefore shapes the set of learnable behaviors in much the same way that dataset composition shapes pretraining.</p>

<h2 id="long-horizons-couple-systems-and-optimization">Long horizons couple systems and optimization</h2>

<p>Long agent trajectories introduce temporal staleness into the training system. Suppose a rollout begins under $
\pi_{\theta_{t-k}}$ and finishes after the learner has advanced to $\pi_{\theta_t}.$ The resulting importance ratio is</p>

\[\rho_t
=
\frac{
\pi_{\theta_t}(a_t\mid s_t)
}{
\pi_{\theta_{t-k}}(a_t\mid s_t)
}.\]

<p>The lag $k$ becomes a variable in the optimization problem. Synchronous group methods can reduce this mismatch but waste computation when rollout durations vary greatly. Asynchronous execution improves utilization by processing completed trajectories immediately, while creating larger policy lag and stronger off-policy effects.</p>

<p>SAO can be understood directly from this tradeoff. GRPO relies on several rollouts for the same prompt to construct a group-relative baseline. Long-horizon asynchronous workloads make waiting for the entire group expensive, so moving to</p>

\[G=1\]

<p>removes the synchronization barrier. The group baseline disappears as a consequence, creating a reason to reintroduce a value function or another advantage estimator. The resulting algorithmic branch therefore follows from a concrete systems constraint: variable trajectory duration changes the optimal data-generation architecture, which then changes the credit-estimation problem.</p>

<p>This is one reason agentic RL increasingly blurs the boundary between optimization and systems design. Throughput decisions alter policy staleness, policy staleness alters importance ratios, and those ratios directly alter the gradient.</p>

<h2 id="policy-identity-itself-becomes-a-systems-variable">Policy identity itself becomes a systems variable</h2>

<p>Large-scale RL introduces another source of mismatch. Rollout inference and gradient training may use different implementations, so even nominally identical model parameters can produce slightly different distributions:</p>

\[\pi_{\mathrm{rollout}}
\neq
\pi_{\mathrm{train}}.\]

<p>Numerical precision, kernels, MoE routing, batching, and distributed execution can all contribute. It is therefore useful to distinguish deliberate policy evolution,</p>

\[\rho_{\mathrm{update}}
=
\frac{
\pi_{\mathrm{current}}
}{
\pi_{\mathrm{old}}
},\]

<p>from implementation disagreement,</p>

\[\rho_{\mathrm{system}}
=
\frac{
\pi_{\mathrm{train}}
}{
\pi_{\mathrm{rollout}}
}.\]

<p>The first reflects optimization progress. The second reflects disagreement between systems intended to represent the same policy. Both matter because probability ratios enter directly into modern RL objectives.</p>

<p>GLM-5.3’s emphasis on train-rollout numerical alignment and R3-style MoE consistency fits naturally into this picture. Once the loss depends on log-probabilities and importance ratios, infrastructure quality becomes part of optimization correctness rather than a separate engineering concern.</p>

<h1 id="iv-from-scalar-rewards-to-distributional-feedback">IV. From scalar rewards to distributional feedback</h1>

<h2 id="on-policy-distillation-increases-feedback-bandwidth">On-policy distillation increases feedback bandwidth</h2>

<p>A scalar reward compresses a high-dimensional trajectory into a small amount of information. Even a perfect binary verifier may provide only $
R\in{0,1}.$ A strong teacher model can instead provide an entire probability distribution over actions. At state $s$, let the teacher define $q_T(v\mid s)$ over the vocabulary.</p>

<p>Traditional distillation usually trains the student on states or outputs selected by the teacher. On-policy distillation changes this by allowing the student to generate the states:</p>

\[s\sim d_{\pi_\theta}.\]

<p>The teacher then evaluates the states the student actually visits. A natural objective is</p>

\[\mathcal L_{\mathrm{OPD}}
=
\mathbb E_{s\sim d_{\pi_\theta}}
\left[
D_{\mathrm{KL}}
\left(
\pi_\theta(\cdot\mid s)
\Vert
q_T(\cdot\mid s)
\right)
\right].\]

<p>This construction combines the state distribution of on-policy RL with the dense feedback of knowledge distillation. For a sampled action, a teacher-derived learning coefficient can take the form</p>

\[A_t^T
=
\log q_T(a_t\mid s_t)
-
\log\pi_\theta(a_t\mid s_t),\]

<p>which again yields an update proportional to</p>

\[A_t^T
\nabla_\theta
\log\pi_\theta(a_t\mid s_t).\]

<p>The familiar policy-gradient-shaped structure therefore survives, while the feedback channel becomes much richer. Top-$k$, full-vocabulary, and multi-teacher variants mainly determine how much of the teacher’s distributional information is retained.</p>

<p>This suggests a broader progression in feedback bandwidth. Demonstrations provide one target behavior, preferences provide a relative ordering, rewards provide scalar evaluation, and teacher distributions provide dense local information over many possible actions.</p>

<h1 id="v-forward-and-reverse-kl-as-the-geometric-unifier">V. Forward and reverse KL as the geometric unifier</h1>

<p>After deriving the main branches from their local motivations, Lambert’s forward and reverse KL framing provides a clean geometric interpretation of the whole picture. This unified framing reminded me: if SFT is Columb’s law, then DPO is potential difference (or voltage) and KL-regularized RL is the free-energy minimization.</p>

<p>For SFT, let the target data distribution be</p>

\[p_{\mathcal D}(y\mid x).\]

<p>The forward KL is</p>

\[D_{\mathrm{KL}}
\left(
p_{\mathcal D}
\Vert
\pi_\theta
\right)
=
\mathbb E_{y\sim p_{\mathcal D}}
\left[
\log
\frac{
p_{\mathcal D}(y\mid x)
}{
\pi_\theta(y\mid x)
}
\right].\]

<p>Expanding,</p>

\[D_{\mathrm{KL}}
\left(
p_{\mathcal D}
\Vert
\pi_\theta
\right)
=
\mathbb E_{p_{\mathcal D}}
[\log p_{\mathcal D}]
-
\mathbb E_{p_{\mathcal D}}
[\log \pi_\theta].\]

<p>The first term is independent of $\theta$, so minimizing the SFT cross-entropy is equivalent to minimizing</p>

\[D_{\mathrm{KL}}
\left(
p_{\mathcal D}
\Vert
\pi_\theta
\right).\]

<p>The expectation is taken under the data distribution. Training therefore occurs in regions selected by the target distribution, which produces the familiar mass-covering tendency of forward KL.</p>

<p>KL-regularized RL has the opposite orientation. Starting from</p>

\[J(\pi)
=
\mathbb E_\pi[r]
-
\beta
D_{\mathrm{KL}}
\left(
\pi
\Vert
\pi_{\mathrm{ref}}
\right),\]

<p>define the reward-tilted target</p>

\[\pi^*(y\mid x)
=
\frac{1}{Z(x)}
\pi_{\mathrm{ref}}(y\mid x)
e^{r(x,y)/\beta}.\]

<p>Then maximizing the RL objective is equivalent to minimizing</p>

\[D_{\mathrm{KL}}
\left(
\pi_\theta
\Vert
\pi^*
\right).\]

<p>Here the expectation is taken under the policy itself. The policy therefore selects the regions in which optimization takes place, while the reward reshapes probability within those regions.</p>

<p>This gives a compact interpretation of the major transition from supervised learning to on-policy optimization. Forward KL naturally corresponds to externally sampled imitation, while reverse KL in KL-regularized RL corresponds to policy-sampled optimization toward a reward-tilted target.</p>

<p>The exact reverse-KL identity depends on the KL-regularized RL objective, so it should not be applied mechanically to every modern RLVR algorithm that weakens or removes explicit KL regularization. The more general lesson is the change in sampling geometry: one regime learns on states selected by an external distribution, while the other learns on states selected by the current policy.</p>

<p>This was one of the most useful ideas I took from Lambert’s treatment because it connects several branches that otherwise look unrelated. SFT and classical knowledge distillation naturally live on the forward-KL side. KL-regularized RL lives on the reverse-KL side. DPO derives its target structure from the reverse-KL RL solution while retaining offline preference data. On-policy distillation moves distillation itself onto the student distribution and therefore naturally takes a reverse-KL form.</p>

<p>The direction of KL is therefore closely related to a more fundamental question: which distribution determines where learning happens?</p>

<h1 id="vi-a-minimal-physicists-model-of-post-training">VI. A minimal physicist’s model of post-training</h1>

<p>The previous sections suggest a generic update of the form</p>

\[\nabla_\theta J
=
\mathbb E_{z\sim\mu}
\left[
\sum_t
w_t
c_t
\nabla_\theta
\log\pi_\theta(a_t\mid s_t)
\right].\]

<p>The variables in this expression correspond to the major conceptual branches developed above.</p>

<p>The distribution $\mu$ determines where training experience comes from. In SFT it is an external dataset, in offline preference optimization it is a preference dataset, and in online RL it is the current or recent policy interacting with a task or environment.</p>

<p>The coefficient $w_t$ represents the learning signal. It may come from a supervised target, a preference margin, an advantage estimate, a verifier, or a teacher distribution.</p>

<p>The factor $c_t$ controls how much the current policy should trust the sample. Importance weighting, clipping, asynchronous correction, and train-rollout consistency all enter here.</p>

<p>Agentic training adds the environment dynamics</p>

\[P_{\mathrm{env}}(s_{t+1}\mid s_t,a_t),\]

<p>which determine how actions change future states and therefore which experiences become reachable.</p>

<p>This provides a compact way to read new post-training papers. A method that changes the reward source primarily modifies $w_t$. A new advantage estimator changes the construction of $w_t$. A new clipping or importance-sampling scheme primarily modifies $c_t$. A new rollout strategy changes $\mu$. Environment generation changes the trajectory distribution itself. Asynchronous training and inference-training mismatch change the relationship among these quantities.</p>

<p>Seen this way, many modern algorithms become local deformations of a shared optimization structure rather than separate theories.</p>

<h1 id="closing-thought">Closing thought</h1>

<p>The Coulomb’s law analogy is useful to me because it imposes a discipline on how to study the field. Start from the simplest equation, identify the missing physical or statistical structure, then add only what is necessary.</p>

<p>Cross-entropy handles demonstrated likelihood. Preference learning adds relative quality. RLHF turns that relative quality into a constrained policy objective. DPO follows from the analytical form of the KL-regularized optimum. Policy gradients move the source of experience onto the model itself. PPO adds control over stale updates. RLVR improves the grounding of reward. GRPO changes the construction of advantage. Agent RL introduces environment dynamics. Asynchronous long-horizon training introduces policy age and off-policy effects. SAO responds to the resulting synchronization problem. Train-rollout alignment exposes numerical implementation as part of the optimization system. On-policy distillation increases the bandwidth of feedback from scalar reward toward a full distribution.</p>

<p>Lambert’s work provides an excellent engineering map of this territory. The first principle complement I find useful is to reduce that map back into a small number of recurring objects and ask how each new method changes them.</p>

<p>My current summary is therefore compact: modern LLM post-training is the study of where experience comes from, how quality is measured, how credit is assigned, and how safely probability can move. For agentic systems, the dynamics of the environment become an equally fundamental part of the problem.</p>

<p>Once those objects are explicit, the growing collection of post-training algorithms becomes much easier to place inside one framework. I highly recommend Lambert’s book and lecture series for anyone who wants to understand the engineering of modern LLMs. I hope this complementary perspective is useful for those who want to understand the underlying structure of the field.</p>]]></content><author><name></name></author><summary type="html"><![CDATA[I have been reading Nathan Lambert’s RLHF Book and following his lecture and video series. What I appreciate most is the way he has systematically organized a rapidly evolving field into an engineering framework. SFT, reward models, PPO, DPO, RLVR, distillation, regularization, infrastructure, and newer agentic methods often appear as separate topics, while his treatment makes their engineering relationships much easier to see.]]></summary></entry><entry><title type="html">First Principle of Agent Harness Engineering: From Continuation to Control</title><link href="https://toooold.com/2026/08/03/first_principle_harness.html" rel="alternate" type="text/html" title="First Principle of Agent Harness Engineering: From Continuation to Control" /><published>2026-08-03T00:00:00+00:00</published><updated>2026-08-03T00:00:00+00:00</updated><id>https://toooold.com/2026/08/03/first_principle_harness</id><content type="html" xml:base="https://toooold.com/2026/08/03/first_principle_harness.html"><![CDATA[<h2 id="why-loops-graphs-and-swarms-are-trying-to-solve-the-same-agent-failure">Why loops, graphs, and swarms are trying to solve the same agent failure</h2>

<p>I am getting tired of tracing all the so-called agent harness engineering techniques. You must feel the same.</p>

<p><img src="/images/agent_harness.jpg" alt="alt text" /></p>

<p>First, the answer was better prompts. Then it was tool use. Then came memory, reflection loops, graphs, planners, evaluators, multi-agent teams, and swarms. Each technique has its own terminology, diagrams, frameworks, and success stories. Each fixes something, yet each also creates another class of failures that requires another layer of orchestration.</p>

<p>After a while, the field begins to resemble a growing collection of patches whose names change faster than the problem underneath them.</p>

<p>I kept seeing the same pattern. A loop was presented as the solution to brittle one-shot agents. A graph was introduced to control an unreliable loop. A swarm was proposed to overcome the limits of one planning path. Then an evaluator, memory layer, or deterministic solver was added to control the failures introduced by the previous layer.</p>

<p>Rather than continuing to trace every new framework, I wanted to understand the first principle. What failure are all these harnesses trying to contain, and why does that failure exist in the first place?</p>

<p>The answer became clearer when I stopped thinking of the LLM as a weak state machine and started from what it actually does. An LLM continues trajectories, while an agent is expected to control them. The gap between those two functions explains much of modern agent engineering.</p>

<h2 id="how-a-small-mistake-becomes-a-trajectory">How a small mistake becomes a trajectory</h2>

<p>Imagine asking a research agent to investigate a technical question and publish a report.</p>

<p>The original request contains one ambiguous sentence. The agent chooses a reasonable interpretation, generates search queries from that interpretation, and retrieves sources that appear to support it. It summarizes those sources into memory. A later agent receives the summary rather than the original evidence, and an evaluator reads the same framing and approves the final report.</p>

<p>No individual step needs to look absurd. The first interpretation may have been highly plausible. The retrieved evidence may have been real. The summary may accurately reflect the selected sources, and the evaluator may correctly judge that the report is internally coherent. The final result can still be wrong because of a discrepancy that entered five steps earlier.</p>

<p>This is the characteristic failure of LLM-orchestrated systems. A local discrepancy becomes part of the next agent state, the next decision is conditioned on that altered state, and the discrepancy gains persistence, confidence, and eventually consequence as the trajectory continues.</p>

<p>The same pattern appears in more consequential tasks. An agent misreads the intended recipient and drafts the correct message for the wrong person. Another agent verifies the wording without checking the recipient, and a final tool call sends it. A coding agent misunderstands one architectural constraint and writes tests that encode its own misunderstanding. The tests pass, so their success becomes evidence that the implementation is correct. A tool request times out after the operation succeeds, and the agent interprets the timeout as failure, retries, and performs the action twice.</p>

<p>In each case, a probable local continuation becomes future context, future context becomes accepted state, and accepted state eventually becomes an external consequence.</p>

<p>A simple way to describe this dynamic is:</p>

\[\delta_{t+1} \leq L_t \delta_t + \epsilon_t\]

<p>Here, $\delta_t$ represents the discrepancy already present in the trajectory, $\epsilon_t$ is the new error introduced at the current step, and $L_t$ describes how strongly the surrounding system propagates the previous discrepancy.</p>

<p>Unrolling the recurrence shows how every local error is weighted by the transitions that follow it:</p>

\[\delta_T
\lesssim
\sum_{i=0}^{T-1}
\left(
\prod_{j=i+1}^{T-1} L_j
\right)
\epsilon_i\]

<p>This makes an important point precise. A longer trajectory is not automatically less reliable. The horizon matters through the product of the later amplification factors. A long coding session can remain stable when compilers, tests, version control, and environmental observations repeatedly pull the agent back toward reality. A two-step payment workflow can be unstable when one transition has a large and irreversible consequence.</p>

<p>When the effective values of $L_t$ stay below one, discrepancies contract. A compiler reports the actual syntax failure, a constraint solver rejects an impossible plan, a transaction receipt establishes what happened, or an independent source challenges a mistaken premise.</p>

<p>When the surrounding system simply preserves previous outputs, discrepancies remain. When the model consumes its own summaries, agents repeat one another’s claims, or actions irreversibly alter the environment, discrepancies can grow.</p>

<p>Agent reliability therefore depends on more than local model quality. It depends on the discrepancy dynamics created by the orchestration around the model.</p>

<h2 id="continuation-is-a-proxy-for-control">Continuation is a proxy for control</h2>

<p>A language model learns a conditional distribution over plausible continuations. Given the trajectory represented in its context, it proposes what may come next:</p>

\[a_t \sim p_\theta(a_t \mid h_t)\]

<p>The history $h_t$ may contain the user request, previous reasoning, tool calls, observations, retrieved documents, memory summaries, and messages from other agents.</p>

<p>Large-scale training gives the model compressed patterns of successful planning, expert decisions, software workflows, tool use, correction, negotiation, and explanation. Post-training further shapes those continuations toward useful, safe, and instruction-following behavior.</p>

<p>This makes continuation an extraordinarily powerful proxy for control. When an agent encounters a familiar problem, it can generate the next step associated with successful examples of that problem. It can produce a plan, call a tool, inspect the result, and continue in a way that resembles an effective problem-solving trajectory.</p>

<p>A controller faces a different objective. It must choose an intervention according to the future world states that intervention is expected to produce:</p>

\[a_t^*
=

\underset{a}{\operatorname{argmax}}
\mathbb{E}
\left[
U\left(s_{t+1:T}\right)
\mid
s_t,\operatorname{do}(a)
\right]\]

<p>The distinction between $h_t$ and $s_t$ is central. The model conditions on a representation of the trajectory, while the action affects the actual world state. The representation may be incomplete, stale, ambiguous, or partly generated by the model itself.</p>

<p>A tool timeout may correspond to several different realities. The operation may have failed, succeeded before the connection closed, or succeeded twice after a retry. The visible trajectory may preserve none of these distinctions.</p>

<p>The model’s actions also change the environment, the changed environment produces the next context, and earlier outputs become later inputs. Once an error enters the trajectory, the model may be reasoning from a situation partly created by its own mistake.</p>

<p>This creates the learning–control gap. Learning rewards strong average predictions across a distribution of observed examples, while control requires stability along the particular sequence of states produced by the policy’s own actions. High average next-step accuracy cannot guarantee that one self-generated trajectory will remain close to the intended path.</p>

<p>A second gap appears at the boundary between probability and consequence. A small change in model output can select a different tool, recipient, branch, or commit operation. The probability distribution changes smoothly while the external world changes discontinuously. A model may be nearly indifferent between drafting and sending even though the consequences of those actions are radically different.</p>

<p>Model improvement reduces the frequency of local discrepancies. Harness engineering determines how far each discrepancy can travel and how much consequence it can acquire.</p>

<p>This gives us the first principle: an agent harness controls the conversion of conditional continuation into persistent state and causal consequence.</p>

<h2 id="what-the-current-harness-techniques-are-doing">What the current harness techniques are doing</h2>

<p>Once we see the root problem, loops, graphs, and swarms become easier to compare because each architecture changes how discrepancy moves through an agent trajectory.</p>

<h3 id="the-naive-agent-minimizes-propagation-surfaces">The naive agent minimizes propagation surfaces</h3>

<p>A simple agent creates a short path from model output to tool execution. Its simplicity limits handoffs, coordination failures, shared-memory contamination, and ambiguous responsibility, which makes it a strong design for short, bounded, easily verified tasks.</p>

<p>Its weakness appears when one incorrect continuation reaches the world without an opportunity for correction. The central measure for a naive agent is consequence sensitivity: how much can one model decision change the final outcome?</p>

<h3 id="the-loop-creates-opportunities-for-correction">The loop creates opportunities for correction</h3>

<p>A loop allows the agent to act, observe, and update its next decision. Its value comes from the possibility that reality can challenge the model’s prediction. A test failure, search result, tool receipt, or changed environment can introduce information that was absent from the original continuation.</p>

<p>The same structure becomes dangerous when the loop repeatedly feeds the model its own claims, retries actions without tracking previous effects, or continues without measurable progress. More iterations then produce more correlated continuations rather than better grounding.</p>

<p>The central measure for a loop is correction per iteration: how much uncertainty or discrepancy does each cycle remove?</p>

<h3 id="the-graph-limits-where-discrepancy-can-travel">The graph limits where discrepancy can travel</h3>

<p>A graph makes some transitions possible and others unreachable. It can enforce that testing happens before deployment, approval happens before payment, and verification happens before completion. Its strength comes from controlling the topology of influence.</p>

<p>Its weakness appears when the edges carry semantically ambiguous content. A clean arrow can still transmit an unsupported claim, a distorted summary, or a false assertion of authority.</p>

<p>The central measure for a graph is invalid-path exclusion: which dangerous trajectories have become structurally impossible?</p>

<h3 id="the-swarm-expands-search-and-changes-error-correlation">The swarm expands search and changes error correlation</h3>

<p>A swarm explores several hypotheses, sources, plans, or implementations in parallel. It can improve coverage when agents search different regions or use genuinely different methods.</p>

<p>The benefit depends on independent information. Agents using the same model, context, evidence, and shared memory often reproduce the same misconception. Their agreement can increase confidence while adding little truth. A mistaken claim can also circulate through the swarm until repetition appears to be confirmation.</p>

<p>The central measure for a swarm is independent information gain: what does each additional agent contribute beyond another correlated sample?</p>

<p>Other agent variants fit into the same picture. Hierarchies reduce coordination entropy while concentrating risk in a manager. LLM planners explore longer candidate trajectories while leaving feasibility uncertain. Deterministic solvers remove paths that violate explicit constraints while remaining dependent on the truth of their premises. Memory preserves state while creating the possibility that an old model-generated summary becomes permanent reality. Evaluators regulate which outputs are accepted while risking the replacement of evidence with another model opinion.</p>

<p>Each technique acts on a different transition in the same process.</p>

<h2 id="what-understanding-the-first-principle-changes">What understanding the first principle changes</h2>

<p>Once an agent is understood as a sequence of state transitions, the architecture question changes. Instead of beginning with whether the system should use a loop, graph, or swarm, we begin with where discrepancy can enter, where it becomes persistent, what can amplify it, what can correct it, and how much consequence it can acquire before correction.</p>

<p>That shift leads to several practical changes.</p>

<h2 id="engineer-the-joint-trajectory-not-isolated-decisions">Engineer the joint trajectory, not isolated decisions</h2>

<p>An agent succeeds only when its interpretations, plans, tool calls, observations, and state updates remain jointly correct.</p>

<p>Let $C_t$ denote the event that transition $t$ remains correct relative to the task, its constraints, and the real world. The probability that the entire trajectory remains correct follows the chain rule:</p>

\[P\left(\bigcap_{t=1}^{T} C_t\right)
=
\prod_{t=1}^{T}
P\left(C_t \mid C_{&lt;t}\right)\]

<p>Even under the optimistic assumption that transitions are independent and each is correct with probability $p$, complete trajectory reliability becomes $p^T$. If ten decisions were independently correct 95 percent of the time, the probability that all ten were correct would be only about 60 percent.</p>

<p>Real LLM trajectories have stronger dependencies. An early output becomes part of the next context, so a mistaken interpretation can lower the probability that every later decision is correct. A corrupted memory entry can influence several downstream agents, while a shared false premise can cause an entire swarm to fail in the same direction.</p>

<p>Once an early discrepancy changes the trajectory, it also changes the conditional distribution governing every later decision.</p>

<p>This dependency structure is the topology of the agent system. A loop determines whether an earlier discrepancy receives corrective evidence or returns as input to the same model. A graph determines which later decisions become conditional on that discrepancy. A swarm determines whether agents contribute independent information or inherit a common error through shared context and memory.</p>

<p>Harness design therefore shapes the joint probability of trajectory success even when the underlying model remains unchanged. The objective is to reduce unnecessary dependencies, prevent unverified outputs from becoming shared premises, introduce evidence that can restore a diverging trajectory, and keep any remaining discrepancy from reaching high-consequence transitions.</p>

<h2 id="preserve-the-meaning-of-state">Preserve the meaning of state</h2>

<p>A model-generated claim, an external observation, a verified fact, a user authorization, a proposed action, a committed action, and a confirmed outcome should remain different objects.</p>

<p>The model can say that a payment was approved, yet that sentence should remain a claim until it is connected to a valid approval event. The model can predict that an email was sent, while that prediction should remain separate from the tool receipt proving that the send operation occurred. A memory summary can help future agents work efficiently, although it should retain references to the evidence from which it was derived and should never silently replace that evidence.</p>

<p>This separation creates epistemic integrity because language can propose a change in state without automatically creating it.</p>

<h2 id="build-restoring-forces-into-the-trajectory">Build restoring forces into the trajectory</h2>

<p>A reliable harness needs mechanisms that pull the agent back toward the real world. A compiler error can correct generated code, a deterministic constraint check can reject an inconsistent plan, an independent source can challenge an interpretation, a transaction receipt can establish whether an action occurred, and a verified postcondition can establish whether the goal was reached.</p>

<p>These mechanisms introduce information that did not originate from the same continuation process. Every loop should therefore be evaluated by whether new evidence makes the next iteration better grounded than the previous one.</p>

<h2 id="bound-the-consequence-of-residual-error">Bound the consequence of residual error</h2>

<p>Even strong models retain residual uncertainty, so a safe architecture reduces the amount of the world that each stochastic decision can change.</p>

<p>A general email tool may allow arbitrary recipients, attachments, and message bodies. A narrow capability may allow one approved draft to be sent to one approved recipient before a fixed expiry time. A deployment agent may prepare changes freely while requiring a separate commit capability for production. A financial agent may analyze opportunities broadly while receiving permission to execute only within a specific amount, account, and time window.</p>

<p>The practical goal is to separate what the model may propose from what the system will permit it to execute. Training can reduce the probability of a bad proposal, while a capability boundary can keep unauthorized or excessively broad actions outside the executable action space.</p>

<p>This reduces consequence amplification. The model can still make an incorrect proposal, while that proposal cannot produce an unlimited external effect.</p>

<h2 id="measure-trajectory-stability">Measure trajectory stability</h2>

<p>A successful run shows that one trajectory worked, although it does not reveal whether the system is stable.</p>

<p>A stronger evaluation perturbs the initial wording, context order, model sample, memory summary, tool response, or timing, then measures how often the final outcome changes materially. This reveals whether the harness corrects small discrepancies, preserves them, or amplifies them.</p>

<p>Task success measures capability. Trajectory sensitivity measures whether that capability remains reliable when the exact continuation changes.</p>

<h2 id="use-deterministic-machinery-at-explicit-boundaries">Use deterministic machinery at explicit boundaries</h2>

<p>LLMs are valuable when the system must interpret ambiguous intent, infer meaning, search broad possibilities, or generate candidate solutions. Deterministic systems become valuable when known constraints must hold simultaneously.</p>

<p>A planner or solver can enforce budgets, dependencies, scheduling rules, permissions, mutual exclusions, and completion requirements. It can project a probabilistic proposal back into a valid region, while the facts supplied to that solver still require grounding because a deterministic system can propagate a false premise with perfect consistency.</p>

<p>A useful division of responsibility gives probabilistic models the semantic uncertainty, deterministic machinery the explicit combinatorial constraints, and environmental verification the task of establishing actual consequences.</p>

<h2 id="add-agents-when-they-add-information">Add agents when they add information</h2>

<p>A second agent should bring a different source, method, tool, model, search region, or adversarial objective. A new persona reading the same context often adds ceremony rather than diversity.</p>

<p>Shared observations and authoritative state can be common across agents, while intermediate interpretations should remain contestable. Agreement can indicate stability, yet truth promotion should depend on evidence.</p>

<p>This creates search breadth without allowing repetition to become authority.</p>

<h2 id="from-framework-recipes-to-causal-harness-engineering">From framework recipes to causal harness engineering</h2>

<p>The major harness techniques become easier to understand once we place them inside one lifecycle. The model first interprets ambiguous intent and proposes possible actions. The harness then checks those proposals against known constraints and determines whether the required authority exists. It executes one bounded intervention, observes what actually happened, verifies whether the expected state was reached, and updates the persistent state used by future decisions.</p>

<p>Loops are useful when observation can correct the next decision. Graphs constrain which influences and transitions are permitted. Swarms broaden the search when additional agents contribute genuinely independent information. Planners generate candidate trajectories, solvers enforce explicit consistency, memory preserves grounded state, evaluators regulate which claims become accepted, and capability boundaries determine which proposals can change the world.</p>

<p>Each stage answers a different question about meaning, possibility, validity, permission, consequence, or evidence. Treating those questions as separate system responsibilities prevents one plausible model continuation from silently answering all of them.</p>

<p>The field has spent the last few years inventing shapes around the model: loops, graphs, hierarchies, and swarms. Those shapes matter because they change the joint conditional probability of the trajectory and determine how discrepancy travels.</p>

<p>A loop can introduce a restoring force or recycle the same misconception. A graph can block an invalid dependency path or hide semantic confusion behind clean arrows. A swarm can contribute independent evidence or multiply a shared mistake. A solver can enforce consistency while faithfully amplifying a false premise.</p>

<p>The common problem sits underneath all of them. We trained a model to continue trajectories, then connected those continuations to systems that change the world.</p>

<p>Agent harness engineering begins when we ask which state transitions remain grounded, which dependencies improve or degrade the joint probability of success, which discrepancies contract, and which decisions are allowed to acquire consequence.</p>

<p>That is how continuation begins to become control.</p>]]></content><author><name></name></author><summary type="html"><![CDATA[Why loops, graphs, and swarms are trying to solve the same agent failure]]></summary></entry><entry><title type="html">Learning Is Selective Change</title><link href="https://toooold.com/2026/07/13/icml_recap3.html" rel="alternate" type="text/html" title="Learning Is Selective Change" /><published>2026-07-13T00:00:00+00:00</published><updated>2026-07-13T00:00:00+00:00</updated><id>https://toooold.com/2026/07/13/icml_recap3</id><content type="html" xml:base="https://toooold.com/2026/07/13/icml_recap3.html"><![CDATA[<h2 id="hidden-gems-found-by-random-luck-in-the-icml-2026-workshops">Hidden gems found by random luck in the ICML 2026 workshops</h2>

<p>Main-conference poster sessions reward planning. Workshop sessions reward luck.</p>

<p><img src="/images/icml3.jpg" alt="alt text" /></p>

<p>A workshop room can be three corridors away from the topic you intended to see, and the poster that changes your afternoon may be the one beside the coffee table rather than the one highlighted in the program. This third ICML reflection is limited to workshop papers I encountered through that kind of fortunate wandering.</p>

<p>The papers span theoretical physics, post-training, foundation models for simulation, Transformer inductive bias, model evaluation, interpretability, and multi-agent diagnosis. Their common question emerged only after I stopped grouping them by application:</p>

<blockquote>
  <p><strong>When an AI system encounters an error or a new environment, what should change, where should that change be stored, and what evidence tells us that the change was useful?</strong></p>
</blockquote>

<p>Learning is often described as parameter optimization. These workshop papers suggest a broader view. An AI system can change its current answer, its dialogue state, its inferred model of the environment, a selected subspace of its weights, or the interaction protocol among several agents. Every update preserves some structure and overwrites something else.</p>

<p>A useful update therefore balances three quantities:</p>

\[U^\star = \arg\min_U \mathcal{L}*{\mathrm{new}}(U(s)) + \lambda \mathcal{D}*{\mathrm{preserve}}(U(s),s) + \mu \mathcal{C}(U).\]

<p>Here, (s) is the current state of the system, (\mathcal{L}<em>{\mathrm{new}}) measures the unresolved error, (\mathcal{D}</em>{\mathrm{preserve}}) measures damage to valuable existing structure, and (\mathcal{C}) represents the cost of the update.</p>

<p>The hard research problem lies in defining those terms. A critique can improve the current derivation while making the overall argument less coherent. Fine-tuning can raise benchmark accuracy while erasing general capabilities. A physics model can produce a plausible next frame while learning the wrong dynamics. A lower perplexity can reward confidence without rewarding correctness. A group of agents can agree because they share the same error.</p>

<p>The workshop papers became a study of <strong>selective change</strong>: changing the right variable, on the right timescale, while preserving the right invariants.</p>

<hr />

<h2 id="critique-changes-the-solution-before-it-changes-the-model">Critique changes the solution before it changes the model</h2>

<p><a href="https://arxiv.org/abs/2605.06772">When Does Critique Improve AI-Assisted Theoretical Physics? SCALAR</a> studies an Actor–Critic–Judge loop on graduate-level quantum field theory and string theory problems. An Actor proposes and revises a solution, a Critic provides feedback with access to a reference solution, and an independent Judge evaluates the successive attempts. The authors vary Actor personas, Critic styles, model families, and model scales. Multi-turn interaction generally improves on single-shot attempts, while the size and character of the gain depend strongly on the Actor–Critic pairing. Constructive feedback is particularly useful when a weaker Actor is paired with a stronger Critic; strict or adversarial feedback provides no universal advantage. (<a href="https://arxiv.org/abs/2605.06772?utm_source=chatgpt.com" title="When Does Critique Improve AI-Assisted Theoretical Physics? SCALAR: Structured Critic--Actor Loop for Agentic Reasoning">arXiv</a>)</p>

<p>The important object is the response of the solution to feedback:</p>

\[G_t = S_{t+1} - S_t,\]

<p>where (S_t) is the quality of the solution after revision (t). A capable Critic can identify the correct error and still produce little gain when the Actor cannot interpret or incorporate the feedback. A milder Critic may outperform a more aggressive one by locating a repair within the Actor’s current competence.</p>

<p>This resembles educational scaffolding more than debate. A useful teacher does not enumerate every flaw simultaneously. The teacher identifies the next misconception that the student can repair. The value of feedback therefore depends on its correctness, novelty, timing, and usability.</p>

<p>SCALAR also offers an instructive evaluation method: track the sequence of revisions rather than only the final score. Two systems with identical final performance can have very different internal dynamics. One may repair a decisive error after a single critique. Another may oscillate among alternative mistakes. A third may repeatedly rewrite the answer while changing little of substance.</p>

<p>For scientific agents, this suggests measuring <strong>critique susceptibility</strong>: how efficiently a system converts feedback into improved work. When gains flatten, the appropriate response may be to switch Critics, decompose the problem, invoke a symbolic tool, or ask for human input. Continuing the same dialogue merely generates more tokens.</p>

<p>The broader lesson is that many failures should be repaired in the current artifact before they trigger a model update. A wrong sign in a derivation calls for a local correction. A systematic inability to reason about gauge invariance may justify a deeper change. The skill lies in distinguishing the two.</p>

<hr />

<h2 id="context-can-carry-learning-without-changing-weights">Context can carry learning without changing weights</h2>

<p><a href="https://arxiv.org/abs/2509.13805">Towards a Physics Foundation Model</a> moves adaptation from dialogue into latent state estimation. Its General Physics Transformer is trained on approximately 1.8 TB of simulation data covering several fluid, thermal, multiphase, and fluid–solid systems. Given a short history of physical states, the model infers enough of the local dynamics to predict future states, including zero-shot experiments on unseen physical systems and boundary conditions. (<a href="https://arxiv.org/abs/2509.13805?utm_source=chatgpt.com" title="Towards a Physics Foundation Model">arXiv</a>)</p>

<p>The task is naturally expressed through a latent dynamics variable (z):</p>

\[p(u_{t+1} \mid u_{t-k+1:t}) = \int p(u_{t+1} \mid u_t,z) p(z \mid u_{t-k+1:t}),dz.\]

<p>The model observes a short trajectory, infers a local description of how this world evolves, and uses that inferred state to generate the next step. The weights remain fixed while the effective model changes through context.</p>

<p>This is closely related to system identification in control theory. An engineer observes inputs and outputs, estimates the hidden dynamics, and then predicts or controls the system. A physics foundation model amortizes that procedure across many simulated worlds.</p>

<p>The architecture also contains an important scientific design choice. The Transformer estimates a temporal derivative, while a numerical integration step advances the state. Spatial and temporal derivative features provide additional numerical structure. The learned component handles cross-domain inference; the integration interface supplies a stable computational scaffold. (<a href="https://arxiv.org/pdf/2509.13805?utm_source=chatgpt.com" title="Towards a Physics Foundation Model">arXiv</a>)</p>

<p>This hybrid structure is more inspiring than a slogan about learning physics from raw data. It suggests that general scientific models may arise from broad learned representations connected through well-chosen numerical interfaces. A neural component can infer the regime, parameters, or operator, while established solvers enforce part of the update structure.</p>

<p>Variable time increments are another methodological gem. When all trajectories share the same sampling interval, visual displacement can become a shortcut for temporal dynamics. Varying the interval forces the model to infer time scale from the context. Similar experiments could be useful in language-model research: change surface format, naming, scale, or tokenization while preserving the underlying operation, then test whether the model infers the mechanism or recognizes the dataset.</p>

<p>The central unresolved question is what kind of latent model has been inferred. The context may identify a familiar simulation family, support a flexible local interpolation, or recover reusable abstractions such as boundary type, conservation structure, or effective dynamics. Carefully constructed pairs of visually similar trajectories governed by different hidden laws could distinguish these explanations.</p>

<p>For AI research agents, the analogy is direct. A mechanistic-interpretability agent should infer a local intervention law from a small set of experiments. It should estimate thresholds, dose–response shape, generalization across prompts, and failure of perturbative assumptions before proposing the next intervention. Most new experimental objects should be handled through contextual system identification long before they motivate weight updates.</p>

<hr />

<h2 id="fine-tuning-should-protect-the-structure-that-future-learning-needs">Fine-tuning should protect the structure that future learning needs</h2>

<p><a href="https://arxiv.org/abs/2605.10973">Rotation-Preserving Supervised Fine-Tuning</a> studies selective change in parameter space. Standard SFT improves the target task while often reducing out-of-domain performance. RPSFT penalizes changes within dominant singular subspaces of the pretrained weight matrices, using those subspaces as an efficient proxy for directions that are expensive to disturb. The complementary space remains available for task adaptation. Across math-reasoning fine-tuning experiments, the method improves the in-domain/OOD trade-off, better preserves pretrained representations, and produces stronger initializations for later reinforcement learning. (<a href="https://arxiv.org/abs/2605.10973?utm_source=chatgpt.com" title="Rotation-Preserving Supervised Fine-Tuning">arXiv</a>)</p>

<p>The method embodies the stability–plasticity dilemma from continual learning and neuroscience. A system needs enough plasticity to acquire a new capability and enough stability to retain its reusable organization. Uniformly constraining the entire model wastes available degrees of freedom. Unconstrained adaptation allows a local training objective to rotate broadly useful machinery.</p>

<p>RPSFT asks a more precise question: which subspaces should carry the new task?</p>

<p>The dominant pretrained directions are a structural proxy rather than a complete map of capability. Their value comes from being computationally tractable and empirically associated with Fisher-sensitive gradient energy. The methodological pattern is broadly reusable: identify an expensive behavioral object, propose a cheaper structural proxy, verify that the proxy captures the relevant signal, and constrain only the corresponding degrees of freedom.</p>

<p>The downstream reinforcement-learning result deserves special attention. A checkpoint can look good immediately after SFT and provide a poor starting point for the next training stage. Preserving pretrained geometry can improve the future learning trajectory even when the current checkpoint difference looks modest.</p>

<p>This expands the meaning of update quality. A good adaptation should solve the present task, preserve unrelated capabilities, and maintain useful plasticity for future stages.</p>

<p>For alignment research, the next question concerns which behavioral mechanisms occupy the protected space. Refusal, truthfulness, self-report, and reasoning may share dominant pretrained geometry, or they may rely on fragile structures introduced later through post-training. Average OOD retention cannot distinguish these possibilities. Causal and representational measurements across ordinary SFT and RPSFT could reveal which alignment mechanisms survive because their supporting subspaces remain stable.</p>

<hr />

<h2 id="weight-space-can-become-an-observable">Weight space can become an observable</h2>

<p><a href="https://arxiv.org/abs/2607.07127">Weight-Space Physics</a> offers the most unusual interpretability idea in this workshop collection: treat trained network weights as scientific measurements of the system they model.</p>

<p>The paper studies normalizing flows trained for lattice field theories across different coupling constants. JEPAWG maps physical couplings through a learned latent space into flow-network weights. The latent weight geometry recovers the intrinsic dimensionality of the coupling manifold, identifies the phase-transition region, and exhibits a finite-size shift aligned with the expected two-dimensional Ising scaling exponent. The model also generates effective flow weights at unseen coupling values. (<a href="https://arxiv.org/abs/2607.07127?utm_source=chatgpt.com" title="Weight-Space Physics: Interpretable Hypernetworks for Lattice Quantum Field Theories">arXiv</a>)</p>

<p>Normally, a learned sampler is a tool for producing configurations from which physical observables are estimated. This work asks whether the parameters of the tool have themselves absorbed the structure of the physical theory.</p>

<p>That reversal creates an unusually clean interpretability benchmark. Physics provides known coupling dimensions, phase structure, and finite-size scaling. An interpretability method can therefore be tested against independently established ground truth rather than judged by whether its visualizations appear meaningful.</p>

<p>The cross-disciplinary inspiration is statistical physics. A phase transition captures a qualitative change in macroscopic behavior. An order parameter summarizes a regime. Finite-size scaling helps distinguish a genuine structural transition from a small-system artifact. Renormalization describes relationships preserved across scales.</p>

<p>Model-family interpretability could borrow the same logic. Consider a controlled family of language models trained with varying amounts of safety data, preference strength, harmful fine-tuning, or reasoning supervision. The checkpoints may form a low-dimensional weight-space manifold. Behavioral transitions could appear as geometric changes along that manifold, while scaling across model sizes could test whether the transition reflects stable structure.</p>

<p>This shifts interpretability away from isolated checkpoints. A single neuron in a single model can be an implementation detail. A consistent manifold, transition boundary, or scaling law across a controlled model family provides a stronger scientific object.</p>

<p>The paper also complicates the usual distinction between learning and measurement. Training a network at each physical coupling creates a measurement instrument whose parameters reflect the underlying system. The hypernetwork then learns the geometry of those measurements. Weight space becomes a bridge between simulation, representation learning, and scientific inference.</p>

<hr />

<h2 id="inductive-bias-determines-which-differences-survive-learning">Inductive bias determines which differences survive learning</h2>

<p><a href="https://arxiv.org/abs/2403.06925">Transformers Learn Low Sensitivity Functions</a> studies the kinds of functions Transformers tend to learn. Across vision and language experiments, the authors find that Transformers learn functions with lower sensitivity to token- or patch-level random perturbations than several alternative architectures. Lower sensitivity correlates with robustness, flatter loss regions, and progress during grokking. (<a href="https://arxiv.org/abs/2403.06925?utm_source=chatgpt.com" title="Transformers Learn Low Sensitivity Functions: Investigations and Implications">arXiv</a>)</p>

<p>For a Boolean function, sensitivity can be written as</p>

\[\operatorname{Sens}(f) = \mathbb{E}*x \sum*{i=1}^{n} \mathbf{1}[f(x) \neq f(x^{\oplus i})].\]

<p>A low-sensitivity function maps many neighboring inputs to the same output. The model compresses away local distinctions that do not appear necessary for its learned rule.</p>

<p>This bias explains part of Transformer robustness. It also creates a boundary between useful invariance and harmful blindness. In sentiment classification, one irrelevant token should rarely change the answer. In parity, exact arithmetic, source code, or cryptographic verification, a single symbol can determine correctness.</p>

<p>A follow-up line of research shows how simplicity bias can trap Transformers in an incorrect low-sensitivity rule under noisy features, even when the intended target is learnable. The architecture’s preference becomes helpful only when its favored invariances match the causal structure of the task. (<a href="https://arxiv.org/abs/2602.08695?utm_source=chatgpt.com" title="Trapped by simplicity: When Transformers fail to learn from noisy features">arXiv</a>)</p>

<p>This connects to the broader theme of selective change. Learning requires the model to decide which input differences deserve a different output. Low sensitivity says that Transformers often require stronger evidence before introducing a distinction.</p>

<p>Average sensitivity can still hide sparse high-leverage directions. A safety behavior may be stable under thousands of random edits and flip under one authority cue, role token, encoding convention, or activation direction. This motivates conditional sensitivity measurements targeted at task-relevant transformations rather than isotropic noise.</p>

<p>The architecture should ignore nuisance variation and remain responsive to causal variation. Determining which is which remains a property of the task, the data, and the measurement procedure.</p>

<hr />

<h2 id="a-learning-system-can-optimize-the-wrong-evidence">A learning system can optimize the wrong evidence</h2>

<p><a href="https://arxiv.org/abs/2601.22950">Perplexity Cannot Always Tell Right from Wrong</a> asks whether the metric used to judge learning preserves the ordering that actually matters.</p>

<p>In a simplified binary setting with accuracy (a) and confidence (\gamma), the average negative log-likelihood is</p>

\[\mathcal{L}(a,\gamma) = -a\log \gamma - (1-a)\log(1-\gamma).\]

<p>Equal-perplexity curves in the accuracy–confidence plane show that a more accurate model can receive worse perplexity when confidence changes in the wrong proportion. The paper also uses continuity properties of compact decoder-only Transformers to prove the existence of sequences that the model predicts incorrectly while assigning very low perplexity. (<a href="https://arxiv.org/abs/2601.22950?utm_source=chatgpt.com" title="Perplexity Cannot Always Tell Right from Wrong">arXiv</a>)</p>

<p>A structurally decisive error can disappear inside an average over many easy token predictions. The model may copy almost an entire sequence confidently and fail at the one position that determines task success. Perplexity remains low because the error occupies little of the total sequence mass.</p>

<p>The result becomes more consequential when the same blind spot affects gradients. A metric that fails to reveal an error during evaluation may also provide little signal for correcting it during learning.</p>

<p>This paper supplies the logical foundation beneath the previous workshop results. Critique helps only when the Critic identifies the true error. Fine-tuning helps only when the objective values the capabilities we intend to preserve. A physics model learns useful dynamics only when one-step loss and rollout evaluation reward the right structure. An interpretability manifold means something only when the measured geometry corresponds to the physical or behavioral quantity of interest.</p>

<p>The cross-disciplinary connection is decision theory. Log-likelihood is a principled scoring rule for distribution estimation, while deployments usually assign highly unequal utility to different mistakes. One wrong tool call, medical diagnosis, proof step, or safety decision can dominate thousands of locally plausible tokens.</p>

<p>A useful metric must therefore match the structure of the claim. Exact reasoning needs exact or verifier-based outcomes. Physical simulation needs rollout stability and invariant preservation. Agent evaluation needs action correctness and consequence-weighted cost. Average likelihood remains informative, while its interpretation must stay tied to the task.</p>

<hr />

<h2 id="agreement-can-preserve-a-shared-mistake">Agreement can preserve a shared mistake</h2>

<p><a href="https://openreview.net/forum?id=arwi30sL39">When Agreement Becomes Unsafe</a> studies multi-agent deliberation in diagnostic-style decisions and starts from a crucial observation: agreement does not certify safety. Agents can converge because they share evidence, reasoning, or bias. The work introduces loss-aware energy control so that the deliberation policy accounts for disagreement, asymmetric decision costs, and the risk of consensus on a costly alternative. The paper appeared as an oral at the ICML 2026 Workshop on Failure Modes of Agentic AI. (<a href="https://openreview.net/forum?id=arwi30sL39&amp;referrer=%5Bthe+profile+of+Shuang+Li%5D%28%2Fprofile%3Fid%3D~Shuang_Li3%29&amp;utm_source=chatgpt.com" title="Loss-Aware Energy Control for Diagnostic Deliberation">OpenReview</a>)</p>

<p>This complements SCALAR. Critique studies whether one agent can improve another’s solution. Diagnostic deliberation asks whether interaction should continue, stop, or escalate when several agents appear to agree.</p>

<p>Consensus is valuable when errors are sufficiently independent and agreement reflects converging evidence. Consensus becomes dangerous when all agents inherit the same training bias, missing feature, or misleading observation. Adding more similar agents can increase confidence without adding information.</p>

<p>The correct mediator must reason about the loss landscape over possible decisions. In high-stakes classification, false positives and false negatives can have different consequences. An agreement on the costly error may deserve more scrutiny than a mild disagreement among low-cost alternatives.</p>

<p>The cross-disciplinary analogy comes from ensemble decision-making and safety-critical diagnosis. A panel of identical instruments does not create independent evidence. Diversity in model name, prompt wording, or sampling seed may leave the relevant blind spot untouched.</p>

<p>The design question is therefore deeper than how many agents should vote. A reliable system needs to know which evidence each agent contributes, which biases they share, and which outcomes justify abstention or escalation.</p>

<hr />

<h2 id="the-center-learning-across-timescales">The center: learning across timescales</h2>

<p>These workshop papers describe changes occurring at several levels.</p>

<p>SCALAR updates a current solution through interaction. A physics foundation model updates a latent description of the environment through context. RPSFT changes selected parts of weight space while protecting reusable structure. Weight-Space Physics studies the geometry created by whole families of trained models. Low-sensitivity research identifies an architectural bias governing which input distinctions survive learning. Perplexity analysis examines whether the objective can recognize improvement. Loss-aware deliberation asks whether a group’s agreement is trustworthy enough to act upon.</p>

<p>The timescales differ, yet the design questions remain aligned.</p>

<p>A local error should first be repaired in the current artifact. A changed environment may require a new latent model. A repeated capability gap may justify a weight update. A weight update should preserve the structure needed for generalization and future learning. Every level requires a metric that sees the consequential error, and every multi-agent system needs a way to distinguish new evidence from duplicated confidence.</p>

<p>This produces a hierarchy of adaptation:</p>

\[\text{artifact revision} \rightarrow \text{contextual inference} \rightarrow \text{weight update} \rightarrow \text{model-family redesign}.\]

<p>Moving right increases cost and persistence. A capable AI system should use the cheapest level that can resolve the error while escalating when the lower level has reached its limit.</p>

<p>This framing also changes how I think about scientific AI. A research agent should not immediately fine-tune itself whenever an experiment disagrees with its prediction. It should first revise the derivation, update the local hypothesis, inspect the measurement, and run a discriminating experiment. Weight updates belong to capability gaps that persist across many contexts.</p>

<p>The workshops offered a quieter message than the main poster halls. Better intelligence may depend less on making every component stronger and more on assigning change to the correct place.</p>

<blockquote>
  <p><strong>Learning is the art of changing the variables that caused the error while preserving the structure that will still be needed afterward.</strong></p>
</blockquote>

<p>Finding these papers required some luck. Recognizing that they were asking the same question required walking away from their application labels.</p>

<hr />

<h2 id="references">References</h2>

<p><a href="https://arxiv.org/abs/2605.06772">When Does Critique Improve AI-Assisted Theoretical Physics? SCALAR: Structured Critic–Actor Loop for Agentic Reasoning</a></p>

<p><a href="https://arxiv.org/abs/2605.10973">Rotation-Preserving Supervised Fine-Tuning</a></p>

<p><a href="https://arxiv.org/abs/2509.13805">Towards a Physics Foundation Model</a></p>

<p><a href="https://arxiv.org/abs/2601.22950">Perplexity Cannot Always Tell Right from Wrong</a></p>

<p><a href="https://arxiv.org/abs/2607.07127">Weight-Space Physics: Interpretable Hypernetworks for Lattice Quantum Field Theories</a></p>

<p><a href="https://arxiv.org/abs/2403.06925">Transformers Learn Low Sensitivity Functions: Investigations and Implications</a></p>

<p><a href="https://openreview.net/forum?id=arwi30sL39">When Agreement Becomes Unsafe: Loss-Aware Energy Control for Diagnostic Deliberation</a></p>]]></content><author><name></name></author><summary type="html"><![CDATA[Hidden gems found by random luck in the ICML 2026 workshops]]></summary></entry><entry><title type="html">What Survives the Transformation?</title><link href="https://toooold.com/2026/07/11/icml_recap2.html" rel="alternate" type="text/html" title="What Survives the Transformation?" /><published>2026-07-11T00:00:00+00:00</published><updated>2026-07-11T00:00:00+00:00</updated><id>https://toooold.com/2026/07/11/icml_recap2</id><content type="html" xml:base="https://toooold.com/2026/07/11/icml_recap2.html"><![CDATA[<h2 id="a-second-icml-2026-reflection-on-provenance-unlearning-representations-and-compression">A second ICML 2026 reflection on provenance, unlearning, representations, and compression</h2>

<p>My first ICML reflection, <a href="https://toooold.com/2026/07/09/icml_recap.html">The Model Chooses a Future Before It Says a Token</a>, followed model behavior through time. It asked where a decision first becomes visible, when it begins shaping the trajectory, and how long an intervention can still redirect the outcome.</p>

<p><img src="/images/icml_2.jpg" alt="alt text" /></p>

<p>This second reflection stays with the main poster sessions and turns the view sideways. When text is rewritten, knowledge is unlearned, a model is fine-tuned, representations are rotated, or an internal state is compressed, what still counts as the same object?</p>

<p>Machine learning experiments often evaluate a snapshot: one prompt, one checkpoint, one output, or one detector score. Many properties become clearer when we study the family of states reachable from that snapshot.</p>

<p>Let $x$ represent a text, model, skill, activation, or internal representation, and let $\mathcal{T}$ be a family of transformations. The orbit of $x$ is</p>

\[[x]_{\mathcal{T}} = {T(x) \mid T \in \mathcal{T}}.\]

<p>A useful notion of identity should keep benign transformations inside the same region,</p>

\[\sup_{T \in \mathcal{T}_{\mathrm{benign}}} d(f(x),f(T(x))) \leq \varepsilon,\]

<p>while preserving separation from objects whose meaning, function, or origin has genuinely changed:</p>

\[\inf_{x' \notin [x]*{\mathcal{T}*{\mathrm{benign}}}} d(f(x),f(x')) \geq m.\]

<p>The difficult part is defining $\mathcal{T}_{\mathrm{benign}}$. A paraphrase may preserve the identity of an instruction. Refactoring may preserve the identity of a software component. Changing tool permissions can create a different security object even when most of the code remains identical. Fine-tuning may preserve model lineage while changing behavior that matters to users.</p>

<p>The posters in this reflection approach the boundary from different directions. Watermarking asks which ownership signal survives transformation. Unlearning asks whether information remains recoverable after an attempted removal. Representation alignment asks which structure remains stable after coordinates and models change. Compression asks which information may disappear while the required function survives.</p>

<p>The common question is simple to state and difficult to operationalize:</p>

<blockquote>
  <p><strong>Which changes should preserve identity, and which changes should cross its boundary?</strong></p>
</blockquote>

<hr />

<h2 id="provenance-is-a-communication-problem">Provenance is a communication problem</h2>

<p>The watermarking and provenance posters differed in technique, yet each one selected a channel through which identity was expected to survive.</p>

<p><a href="https://arxiv.org/abs/2509.23019">LLM Watermark Evasion via Bias Inversion</a> examines watermarks carried by token-selection statistics. Its Bias-Inversion Rewriting Attack estimates likely watermarked tokens from surprisal and suppresses them during rewriting. The paper reports that a small opposing logit bias can remove the detector signal across several watermark schemes while largely preserving semantic content. This exposes the fragility of identities attached closely to replaceable lexical choices. (<a href="https://arxiv.org/abs/2509.23019?utm_source=chatgpt.com" title="LLM Watermark Evasion via Bias Inversion">arXiv</a>)</p>

<p><a href="https://arxiv.org/abs/2601.22985">dgMARK</a> chooses a different carrier for diffusion language models. These models resolve masked positions iteratively, and practical systems remain sensitive to the order in which positions are unmasked. dgMARK steers that order toward positions whose likely tokens satisfy a keyed parity condition. The watermark therefore travels partly through the generation path. Its sliding-window detector is designed to retain signal under insertions, deletions, substitutions, and paraphrasing. (<a href="https://arxiv.org/abs/2601.22985?utm_source=chatgpt.com" title="dgMARK: Decoding-Guided Watermarking for Diffusion ...">arXiv</a>)</p>

<p><a href="https://arxiv.org/abs/2501.09328">Neural Honeytrace</a> treats provenance as communication through model extraction. The original model embeds a weak signal across ordinary interactions, while extraction and adaptation act as a noisy channel. Verification aggregates evidence over multiple queries, allowing a distributed statistical relationship to remain detectable even when individual outputs appear unremarkable. The paper’s information-theoretic framing makes the roles of signal strength, channel noise, and adaptive attackers explicit. (<a href="https://arxiv.org/abs/2501.09328?utm_source=chatgpt.com" title="Neural Honeytrace: A Robust Plug-and-Play Watermarking Framework against Model Extraction Attacks">arXiv</a>)</p>

<p>These methods suggest that provenance is fundamentally a coding problem. The owner chooses a carrier, the deployment process applies a channel, and the attacker searches for a low-cost transformation that destroys the signal. Token statistics, decoding trajectories, cross-query distributions, and internal mechanisms provide different capacities and different attack surfaces.</p>

<p><a href="https://arxiv.org/abs/2606.29807">Rethinking Forgery Attacks on Semantic Watermarks</a> makes the attacker’s cost explicit through rate-distortion geometry. A black-box attacker uses a proxy model to move an unwatermarked sample into a region accepted by a target detector. Structural mismatch between the proxy and target models creates global drift and local deformation, producing a distortion floor for successful forgery. (<a href="https://arxiv.org/abs/2606.29807?utm_source=chatgpt.com" title="Rethinking Forgery Attacks on Semantic Watermarks in Black-Box Settings: A Geometric Distortion Perspective">arXiv</a>)</p>

<p>For a target identity region $\mathcal{R}$, define $\mathcal{A}(x,\mathcal{R})$ as the transformations that move $x$ into that region. The minimum forgery cost is</p>

\[C_{\mathrm{forge}}(x,\mathcal{R}) = \inf_{T \in \mathcal{A}(x,\mathcal{R})} D(x,T(x)).\]

<p>This formulation reaches beyond watermarking. A useful identity mechanism should tolerate inexpensive benign edits while forcing impersonation to pay a meaningful semantic, functional, or perceptual cost.</p>

<p><strong>Before ICML:</strong> I tended to think of provenance as finding a sufficiently stable signature.</p>

<p><strong>After ICML:</strong> provenance looks like channel design. The carrier, transformation family, attacker, detector, and distortion measure jointly determine whether identity survives.</p>

<p>This view connects naturally to my recent research focus on agent-skill identity, fuzzy fingerprints, and composition-aware security. An agent skill can change its wording, internal organization, or implementation language while preserving function and lineage. It can also retain nearly identical code while acquiring new permissions, side effects, or trigger behavior. A robust identity system therefore needs to distinguish surface variation from security-relevant change.</p>

<hr />

<h2 id="unlearning-is-a-recoverability-claim">Unlearning is a recoverability claim</h2>

<p>Unlearning asks the inverse question. A provenance signal should remain accessible after benign transformations. Forgotten information should remain inaccessible after recovery attempts.</p>

<p>Suppose an unlearning procedure changes model parameters from $\theta$ to $\theta’$. A decline in the original answer probability,</p>

\[p_{\theta'}(y \mid q) &lt; p_{\theta}(y \mid q),\]

<p>shows that the familiar query path has weakened. It leaves open how many alternative access paths remain.</p>

<p>A more informative object is recoverability:</p>

\[\operatorname{Rec}(K;\theta') = \sup_{T \in \mathcal{A}} \operatorname{Perf}(T(\theta'),K),\]

<p>where $K$ is the target knowledge or behavior and $\mathcal{A}$ is a declared family of recovery procedures. This family might include paraphrased queries, other languages, activation interventions, adapter training, limited relearning, model merging, or alternative decoding strategies.</p>

<p><a href="https://arxiv.org/abs/2505.16831">Unlearning Isn’t Deletion</a> shows that models can appear to forget under accuracy and perplexity measurements while recovering the original behavior after relatively little retraining. Its representation-level analysis uses PCA-based shifts, centered kernel alignment, and Fisher information to distinguish reversible suppression from deeper representational damage. (<a href="https://arxiv.org/abs/2505.16831?utm_source=chatgpt.com" title="Unlearning Isn't Deletion: Investigating Reversibility of Machine Unlearning in LLMs">arXiv</a>)</p>

<p>The result changes the meaning of a successful forgetting score. Forgetting is always relative to an access model. A user with prompts alone, a researcher with activation access, and an attacker with fine-tuning data face different recovery boundaries.</p>

<p><a href="https://arxiv.org/abs/2605.21539">DualOptim+</a> approaches the forgetting-retention trade-off through optimizer state. The method maintains a base state for structure shared by the forget and retain objectives, together with delta states for objective-specific residuals. It adapts the balance between shared and separated states according to directional conflict between the gradients. (<a href="https://arxiv.org/abs/2605.21539?utm_source=chatgpt.com" title="DualOptim+: Bridging Shared and Decoupled Optimizer States for Better Machine Unlearning in Large Language Models">arXiv</a>)</p>

<p>This suggests that forgetting depends partly on where optimization stores agreement and conflict. A fully shared state can entangle incompatible objectives, while complete separation can discard common structure that both objectives need.</p>

<p>A cleaner immediate trade-off still leaves the recovery question open. An optimizer can suppress the target response precisely while retaining a latent representation that is easy to reactivate. The strongest evaluation therefore needs two axes: collateral damage to retained capabilities and the adversarial cost of restoring the forgotten capability.</p>

<p>A recovery curve can express this distinction. Let $\mathcal{A}_b$ be the set of recovery procedures whose cost is at most $b$:</p>

\[R(b) = \max_{T \in \mathcal{A}_b} \operatorname{Perf}(T(\theta'),K).\]

<p>The shape of $R(b)$ reveals whether the target knowledge was deeply disrupted or hidden behind a thin access barrier. Rapid recovery under a small budget indicates suppression. Slow recovery under increasingly capable attacks provides stronger evidence of structural removal.</p>

<p><strong>Before ICML:</strong> I read a large forget-set performance drop as strong evidence of forgetting.</p>

<p><strong>After ICML:</strong> the stronger claim concerns the cost, breadth, and mechanism of recovery.</p>

<p>This perspective also clarifies why selective deletion is difficult in large models. A fact or behavior may share internal structure with broad linguistic and reasoning competence. Removing one behavior while preserving its neighbors resembles surgery on a distributed system with overlapping dependencies.</p>

<hr />

<h2 id="representation-identity-must-survive-coordinate-changes">Representation identity must survive coordinate changes</h2>

<p>A representation can preserve function while changing its coordinates. Hidden units can permute, bases can rotate, layers can redistribute computation, and independently trained models can implement similar behavior through different local features.</p>

<p><a href="https://arxiv.org/abs/2602.06205">Multi-Way Representation Alignment</a> studies alignment among three or more representation spaces. Pairwise mappings scale quadratically and can become mutually inconsistent. The paper uses Generalized Procrustes Analysis to construct a shared orthogonal universe that preserves internal geometry, then applies a geometry-correcting step to improve correspondence across models. (<a href="https://arxiv.org/abs/2602.06205?utm_source=chatgpt.com" title="Multi-Way Representation Alignment">arXiv</a>)</p>

<p>This creates an important distinction between preserving geometry and maximizing agreement. An orthogonal mapping may retain distances and angles within each representation while producing imperfect retrieval across models. A more flexible mapping may improve correspondence while distorting the structure one hoped to compare.</p>

<p>For mechanistic interpretability, geometric agreement alone remains incomplete. Similar representations can support different causal computations, and similar probe accuracy can emerge from different mechanisms.</p>

<p>A stronger test would map a behaviorally relevant direction from model $A$ into the shared universe, transfer it into model $B$, and measure whether the intervention changes the same behavior. A transferred refusal, language-routing, or reasoning direction that retains its causal effect would provide stronger evidence of shared mechanism than observational alignment alone.</p>

<p>This suggests a hierarchy of claims:</p>

\[\text{output similarity} \prec \text{representation similarity} \prec \text{causal transfer}.\]

<p>Output similarity is easy to observe and easy to imitate. Representation similarity adds evidence of internal correspondence. Causal transfer asks whether the transformed object still performs the same computational role.</p>

<p>The same issue appears in model lineage. Fine-tuning and merging can move individual parameters considerably while retaining higher-level dependencies. Behavioral fingerprints ask whether outputs remain similar. Representation alignment asks whether internal geometry remains corresponding. Mechanistic fingerprints ask whether inherited computations remain causally necessary.</p>

<p>The broader methodological lesson comes from geometry and physics: coordinates describe an object, while invariants identify what survives a change of coordinates.</p>

<p><strong>Before ICML:</strong> I viewed cross-model alignment mainly as a way to compare probes and steering directions.</p>

<p><strong>After ICML:</strong> shared coordinates look like a prerequisite for determining whether a mechanism or capability survived adaptation.</p>

<hr />

<h2 id="compression-asks-what-may-safely-disappear">Compression asks what may safely disappear</h2>

<p>Provenance asks which signal must survive. Compression asks which information can be removed while preserving the function that matters.</p>

<p>Let $c:X \to Z$ compress an input or internal state, and let $g$ operate on the compressed representation. The additional task loss introduced by compression can be written as</p>

\[\Delta_{\mathrm{task}} = \mathbb{E}[\ell(g(c(X)),Y)] - \mathbb{E}[\ell(f(X),Y)].\]

<p>A task-preserving compression requires</p>

\[\Delta_{\mathrm{task}} \leq \varepsilon,\]

<p>while $Z$ uses fewer tokens, dimensions, channels, or computational steps than $X$.</p>

<p><a href="https://arxiv.org/abs/2606.29354">When LLMs Develop Languages</a> explores this idea through multi-agent communication. Agents develop compact symbolic languages with their own symbols, rules, and message-passing contracts. A router selects or combines these protocols according to task difficulty, reducing generated-token cost while preserving accuracy on the evaluated reasoning tasks. (<a href="https://arxiv.org/abs/2606.29354?utm_source=chatgpt.com" title="When LLMs Develop Languages: Symbolic Communication for Efficient Multi-Agent Reasoning">arXiv</a>)</p>

<p>The result suggests that natural-language reasoning contains substantial redundancy from the perspective of machine-to-machine communication. Human-readable prose supports explanation, negotiation, and repair. Agents sharing an interpreter can encode part of the same computational state in a smaller protocol.</p>

<p>The central question becomes what disappears during compression. Final-answer accuracy may survive while uncertainty, evidence provenance, alternative hypotheses, or safety constraints vanish from the message. A compact language can also become an opaque private channel whose semantics are difficult for humans or external verifiers to inspect.</p>

<p>A useful machine protocol therefore needs a richer preservation criterion than accuracy alone. It should carry enough state for downstream action, enough provenance for verification, and enough structure for local repair when the receiving agent detects an inconsistency.</p>

<p><a href="https://openreview.net/forum?id=bgAbffQCrL">BeaconKV</a> asks a related question about inference memory. Its beacon queries represent global query clusters and guide which key-value cache entries should be retained. Cache compression must estimate which past states will matter for future generation before those future dependencies are fully known. (<a href="https://openreview.net/forum?id=bgAbffQCrL&amp;utm_source=chatgpt.com" title="BeaconKV: Key-Value Cache Compression Guided by ...">OpenReview</a>)</p>

<p>This is temporal sufficiency. A state that appears unimportant at the current token may become decisive after a topic shift, delayed reference, or later tool result. An effective cache policy must preserve information whose value depends on futures that remain unresolved.</p>

<p><a href="https://arxiv.org/abs/2604.07931">Robust Length Prediction</a> adds a systems-level version of the same issue. The same prompt can induce a distribution of output lengths under a fixed model and decoding configuration, and this distribution may have a heavy tail. Predicting a single expected length hides the operational difference between a consistently moderate response and a prompt that usually ends quickly but occasionally triggers a very long trajectory. (<a href="https://arxiv.org/abs/2604.07931?utm_source=chatgpt.com" title="Robust Length Prediction: A Perspective from Heavy-Tailed Prompt-Conditioned Distributions">arXiv</a>)</p>

<p>Together, these papers point toward a shared principle: compression should preserve option value. The information worth retaining is partly determined by futures that remain possible.</p>

<p>Average-case objectives can remove rare evidence, delayed dependencies, or safety-critical state because these contribute little to typical performance. Compression for reasoning models and agents therefore needs stress tests built around low-frequency, high-consequence dependencies.</p>

<hr />

<h2 id="transformation-aware-evaluation">Transformation-aware evaluation</h2>

<p>Every claim in this reflection depends on a metric. A detector says that a watermark survived. A benchmark says that knowledge disappeared. A similarity score says that representations align. An accuracy number says that compression preserved function.</p>

<p>Each metric should be evaluated under the transformation family that defines the claim.</p>

<p>A provenance method needs rewriting, paraphrasing, extraction, adaptation, and forgery tests. An unlearning method needs alternate prompts, languages, steering, relearning, and recovery tests. A representation-alignment method needs causal transfer across models. A compressed protocol needs rare-task, uncertainty-preservation, and safety tests. A cache method needs delayed dependencies and distribution shifts.</p>

<p>The general robust score can be written as</p>

\[\operatorname{RobustScore}(x) = \inf_{T \in \mathcal{T}_{\mathrm{claim}}} M(T(x)),\]

<p>where $M$ is the relevant measurement and $\mathcal{T}_{\mathrm{claim}}$ contains the transformations under which the property is expected to hold.</p>

<p>The infimum matters because average performance can hide a cheap boundary crossing. A watermark may survive many local edits and fail under one strong rewriting method. An unlearned model may resist direct prompting and recover after a small adapter update. A compressed protocol may solve common tasks and lose one safety-critical distinction.</p>

<p>A static benchmark measures one location. A transformation suite maps the boundary.</p>

<p>This also provides a disciplined way to separate robustness claims. A method can be robust under paraphrasing, fragile under translation, and completely reversible under fine-tuning. Each statement can be true because each refers to a different transformation family.</p>

<hr />

<h2 id="the-research-object-is-an-orbit">The research object is an orbit</h2>

<p>The first post ended with a temporal principle: find the earliest reliable decision point and intervene before the wrong future becomes difficult to reverse.</p>

<p>The second set of main-session posters adds a complementary principle. A checkpoint, output, skill, or representation is one sample from a larger orbit of transformations. The scientific object includes the orbit, the invariants that persist inside it, and the boundary at which identity or function changes.</p>

<p>For provenance, the orbit includes rewriting, extraction, and adaptation. For unlearning, it includes alternate access paths and recovery procedures. For representation analysis, it includes basis changes and model families. For compression, it includes smaller representations that preserve enough information for downstream use.</p>

<p>This perspective sharpens the meaning of robustness. A robust system should ignore variations that preserve the task and respond strongly to variations that alter its causal structure. Robustness therefore depends on knowing which transformations belong in each category.</p>

<p>My recent research focus on fuzzy identity, agent-skill provenance, and composition-aware security fits naturally into this view. Agent components rarely remain textually identical. Their meaningful identity lies in a combination of function, dependencies, permissions, side effects, and behavior under composition. The hard cases arise when surface similarity remains high while the security object has changed, or when surface similarity falls while lineage and function remain intact.</p>

<p>The resulting research program has three parts. We need to define the transformation family, identify the representation or mechanism that should remain stable, and search for the cheapest adversarial transformation that crosses the intended boundary.</p>

<p>That boundary is where identity, security, and interpretability meet.</p>

<blockquote>
  <p><strong>The real object is the pattern that survives the transformations we are willing to call harmless, and the real attack is the cheapest transformation that changes the identity without paying the intended semantic or functional cost.</strong></p>
</blockquote>

<hr />

<h2 id="references">References</h2>

<p><a href="https://toooold.com/2026/07/09/icml_recap.html">The Model Chooses a Future Before It Says a Token</a></p>

<p><a href="https://arxiv.org/abs/2509.23019">LLM Watermark Evasion via Bias Inversion</a></p>

<p><a href="https://arxiv.org/abs/2601.22985">dgMARK: Decoding-Guided Watermarking for Diffusion Language Models</a></p>

<p><a href="https://arxiv.org/abs/2501.09328">Neural Honeytrace: A Robust Plug-and-Play Watermarking Framework against Model Extraction Attacks</a></p>

<p><a href="https://arxiv.org/abs/2606.29807">Rethinking Forgery Attacks on Semantic Watermarks in Black-Box Settings: A Geometric Distortion Perspective</a></p>

<p><a href="https://arxiv.org/abs/2505.16831">Unlearning Isn’t Deletion: Investigating Reversibility of Machine Unlearning in LLMs</a></p>

<p><a href="https://arxiv.org/abs/2605.21539">DualOptim+: Bridging Shared and Decoupled Optimizer States for Better Machine Unlearning in Large Language Models</a></p>

<p><a href="https://arxiv.org/abs/2602.06205">Multi-Way Representation Alignment</a></p>

<p><a href="https://arxiv.org/abs/2606.29354">When LLMs Develop Languages: Symbolic Communication for Efficient Multi-Agent Reasoning</a></p>

<p><a href="https://openreview.net/forum?id=bgAbffQCrL">BeaconKV: Key-Value Cache Compression Guided by Beacon Queries for Efficient Large Reasoning Model Inference</a></p>

<p><a href="https://arxiv.org/abs/2604.07931">Robust Length Prediction: A Perspective from Heavy-Tailed Prompt-Conditioned Distributions</a></p>]]></content><author><name></name></author><summary type="html"><![CDATA[A second ICML 2026 reflection on provenance, unlearning, representations, and compression]]></summary></entry><entry><title type="html">The Model Chooses a Future Before It Says a Token</title><link href="https://toooold.com/2026/07/09/icml_recap.html" rel="alternate" type="text/html" title="The Model Chooses a Future Before It Says a Token" /><published>2026-07-09T00:00:00+00:00</published><updated>2026-07-09T00:00:00+00:00</updated><id>https://toooold.com/2026/07/09/icml_recap</id><content type="html" xml:base="https://toooold.com/2026/07/09/icml_recap.html"><![CDATA[<h2 id="what-i-learned-from-icml-2026-through-interpretability-alignment-post-training-and-agent-safety">What I learned from ICML 2026 through interpretability, alignment, post-training, and agent safety</h2>

<p>ICML is an excellent fitness program disguised as a machine learning conference. My phone recorded roughly 20,000 steps a day, so this review has a natural methodological limitation: it covers eight poster sessions and is bounded by my walking distance.</p>

<p><img src="/images/icml_snapshot.jpg" alt="alt text" /></p>

<p>I filtered those sessions through the questions closest to my research: how aligned behavior is represented, how post-training changes model internals, how safety mechanisms fail under distribution shift, how agents decide when to act, and how interpretability can move from explaining behavior toward changing it.</p>

<p>One idea kept resurfacing:</p>

<blockquote>
  <p><strong>A model often chooses a future before the final answer makes that choice visible.</strong></p>
</blockquote>

<p>The commitment may happen through an internal feature, an expert route, a reasoning branch, a retrieved passage, a social-response channel, or a tool action. I use <em>margin</em> loosely here to mean the model’s relative preference between such competing futures: one reasoning branch over another, refusal over compliance, correct evidence over a distractor, or a safe action over an unsafe one.</p>

<p>Before ICML, I often asked which feature, neuron, or direction controlled a behavior.</p>

<p>After eight poster sessions—and many corridors between them—the more useful question became:</p>

<blockquote>
  <p><strong>Where does the decision first become visible, when does it become causal, and is there still time to intervene?</strong></p>
</blockquote>

<hr />

<h2 id="1-reasoning-steering-and-interpretability">1. Reasoning, steering, and interpretability</h2>

<h3 id="thinking-helps-when-it-improves-the-next-decision">Thinking helps when it improves the next decision</h3>

<p>Several papers converged on a view of reasoning as a sequence of local decisions rather than a monolithic chain of thought.</p>

<p><a href="https://arxiv.org/abs/2604.08872">How does Chain of Thought decompose complex tasks?</a> models reasoning as the decomposition of a difficult classification problem into a tree of smaller ones. The analysis produces an optimal depth: shallow reasoning leaves the original decision too hard, while excessive depth accumulates new opportunities for error. <a href="https://arxiv.org/abs/2603.08000">SmartThinker</a> reaches a related conclusion from the training side. A fixed length penalty can compress difficult solutions too aggressively, so the desired reasoning budget should depend on the problem and on the distribution of successful response lengths. (<a href="https://arxiv.org/abs/2604.08872" title="[2604.08872] How does Chain of Thought decompose complex tasks?">arXiv</a>)</p>

<p>For a reasoning state ($h_t$), the object I care about can be written as</p>

\[\Delta_t =  \log p\left(\text{good next branch}\mid h_t\right) - \log p\left(\text{bad next branch}\mid h_t\right).\]

<p>The branch might be a mathematical subgoal, a correction to an earlier assumption, a safe continuation, or a decision to verify rather than guess. A useful reasoning step improves the future decision landscape. Overthinking begins when new steps add low-margin branches without resolving the old uncertainty.</p>

<p><a href="https://arxiv.org/abs/2602.11096">SafeThink</a> made this temporal view particularly concrete. Its main empirical result is that many unsafe reasoning trajectories can be redirected with a short corrective prefix during the first few reasoning steps. The important object is therefore not merely whether the final answer is safe, but how early the trajectory remains recoverable. (<a href="https://arxiv.org/abs/2602.11096?utm_source=chatgpt.com" title="Safety Recovery in Reasoning Models Is Only a Few Early Steering Steps Away">arXiv</a>)</p>

<p>This resembles a classical feedback-control problem. The intervention should arrive after enough evidence of drift has appeared, yet before the trajectory has settled into a harmful basin. Heavy intervention everywhere wastes control effort and increases collateral effects; late intervention edits the surface after the decisive branch has already been taken.</p>

<h3 id="sparse-routes-carry-large-behavioral-effects">Sparse routes carry large behavioral effects</h3>

<p>The same structure appeared inside model architectures.</p>

<p><a href="https://arxiv.org/abs/2602.08621">Sparse Models, Sparse Safety</a> shows that MoE safety can depend on a small set of router decisions: manipulating a few safety-critical routers can redirect computation toward unsafe routes. <a href="https://arxiv.org/abs/2601.21900">TraceRouter</a> extends the routing view beyond explicit MoE routers by tracing harmful semantic influence through cross-layer feature paths. (<a href="https://arxiv.org/abs/2602.08621?utm_source=chatgpt.com" title="Sparse Models, Sparse Safety: Unsafe Routes in Mixture-of-Experts LLMs">arXiv</a>)</p>

<p>Attention provided another version of the story. <a href="https://arxiv.org/abs/2602.05228">Surgery</a> links harmful fine-tuning to changes in attention-sink divergence and regularizes that statistic during adaptation. <a href="https://arxiv.org/abs/2605.06611">The Structural Origin of Attention Sink</a> traces sink formation back to variance discrepancies in value aggregation, their amplification by super neurons, and resulting dimensional imbalance. The interesting commonality is how a small statistical asymmetry can be amplified into a stable routing pattern. (<a href="https://arxiv.org/abs/2602.05228" title="[2602.05228] Surgery: Mitigating Harmful Fine-Tuning for Large Language Models via Attention Sink">arXiv</a>)</p>

<p>This makes sparsity both attractive and dangerous. Sparse mechanisms offer interpretable handles, yet a safety property concentrated in a few routes can also be bypassed through small perturbations or post-training updates. The relevant question is therefore not simply whether a component has causal leverage. A useful control point needs enough behavioral reach, a tolerable side-effect profile, and a nontrivial operating window.</p>

<h3 id="steering-has-a-geometry-and-a-schedule">Steering has a geometry and a schedule</h3>

<p>Two steering papers clarified why finding a direction is only part of the problem.</p>

<p><a href="https://arxiv.org/abs/2602.08169">Spherical Steering</a> replaces additive displacement with rotation on a representation sphere, separating angular movement toward a target behavior from radial norm distortion. <a href="https://arxiv.org/abs/2605.03907">Steer Like the LLM</a> starts from another observation: prompting does not induce the same activation shift at every token. Prompt Steering Replacement learns state- and position-dependent coefficients that approximate the intervention pattern produced by a successful prompt. (<a href="https://arxiv.org/abs/2602.08169" title="[2602.08169] Spherical Steering: Geometry-Aware Activation Rotation for Language Models">arXiv</a>)</p>

<p>Together with early trajectory correction, these papers outline three coupled questions:</p>

<ul>
  <li><strong>When</strong> is the trajectory still steerable?</li>
  <li><strong>Where</strong> in the model is the target distinction represented and used?</li>
  <li><strong>How</strong> should the intervention move the state without pushing it off-manifold?</li>
</ul>

<p>Before ICML, I thought of steering mainly as direction discovery.</p>

<p>After ICML, steering looks more like a policy over layer, time, geometry, and dose.</p>

<h3 id="visibility-causality-and-long-horizon-influence">Visibility, causality, and long-horizon influence</h3>

<p>A useful hidden gem was <a href="https://arxiv.org/abs/2605.26366">Automatic Layer Selection for Hallucination Detection</a>. Its FEPoID criterion selects intermediate layers where hallucination-related signals become especially detectable. The broader lesson is that “where to look” is already part of the mechanism: a signal can be absent from one layer, linearly visible in another, and causally committed somewhere else. (<a href="https://arxiv.org/abs/2605.26366?utm_source=chatgpt.com" title="Automatic Layer Selection for Hallucination Detection">arXiv</a>)</p>

<p>For each behavior, I now want to separate four questions:</p>

<ol>
  <li>Is the relevant information represented?</li>
  <li>Is it visible in a usable coordinate system?</li>
  <li>Is it causally used?</li>
  <li>Is the outcome still changeable at that point?</li>
</ol>

<p><a href="https://arxiv.org/abs/2602.01914">Towards Long-Horizon Interpretability</a> supplies an important complementary method. FlashTrace attributes multi-token spans and recursively propagates influence through intermediate reasoning tokens back toward source inputs. This is closer to the causal object needed for reasoning models: an early assumption may have little effect on the immediately following token while strongly shaping an entire later derivation. (<a href="https://arxiv.org/abs/2602.01914?utm_source=chatgpt.com" title="Towards Long-Horizon Interpretability: Efficient and Faithful Multi-Token Attribution for Reasoning LLMs">arXiv</a>)</p>

<p>Representation units and cross-model coordinates remain part of the same puzzle. <a href="https://arxiv.org/abs/2509.20784">Towards Atoms of Large Language Models</a> asks whether neurons and standard SAE features are the right stable units. <a href="https://arxiv.org/abs/2602.06205">Multi-Way Representation Alignment</a> maps multiple models into a shared representation universe rather than constructing inconsistent pairwise correspondences. A mechanistic claim becomes more convincing when the same causal quantity survives a change of layer, unit, model, or coordinate system. (<a href="https://arxiv.org/abs/2509.20784" title="[2509.20784] Towards Atoms of Large Language Models">arXiv</a>)</p>

<h3 id="external-context-is-also-a-routing-system">External context is also a routing system</h3>

<p><a href="https://arxiv.org/abs/2605.10828">The First Drop of Ink</a> extends the routing perspective beyond model internals. A small proportion of semantically plausible distractors causes a sharp initial loss in long-context accuracy, while adding more distractors produces diminishing additional damage. The first strong distractor captures enough attention to redirect the evidence path; the rest mostly compete within an already contaminated context. (<a href="https://arxiv.org/abs/2605.10828?utm_source=chatgpt.com" title="The First Drop of Ink: Nonlinear Impact of Misleading Information in Long-Context Reasoning">arXiv</a>)</p>

<p>This matters for RAG and agents with persistent memory. Retrieved context is not passive storage. Correct and misleading passages compete to become the basis of the answer. A useful evidence margin is therefore the model’s preference for the best supported source over the strongest plausible distractor.</p>

<hr />

<h2 id="2-alignment-self-report-and-evaluation">2. Alignment, self-report, and evaluation</h2>

<h3 id="saying-is-another-behavior">Saying is another behavior</h3>

<p>The self-report and explanation papers challenged a common shortcut in alignment evaluation. A model’s account of its personality, beliefs, or reasons is still a generated output rather than privileged access to its internal computation.</p>

<p><a href="https://arxiv.org/abs/2509.03730">The Personality Illusion</a> finds that instruction tuning can stabilize self-reported personality traits even when those reports remain weak predictors of behavior. Persona prompts move questionnaire answers much more consistently than they move risk-taking, sycophancy, or other behavioral measures. <a href="https://arxiv.org/abs/2606.28615">What LLMs Explain Is Not What They Believe</a> formalizes explanation sufficiency relative to a distribution of alternative inputs and finds that many explanations remain insufficient even under alternatives generated from the model’s own input beliefs. (<a href="https://arxiv.org/abs/2509.03730" title="[2509.03730] The Personality Illusion: Revealing Dissociation Between Self-Reports &amp; Behavior in LLMs">arXiv</a>)</p>

<p>A conversation at the second poster suggested a more precise follow-up question. Explanation failure can arise at several stages:</p>

<ul>
  <li>the relevant feature is absent;</li>
  <li>it is represented but not used;</li>
  <li>it is used but inaccessible to verbalization;</li>
  <li>it reaches the verbal channel but is translated unfaithfully;</li>
  <li>a separate social-response circuit produces a plausible rationale.</li>
</ul>

<p>Anthropic’s <a href="https://www.anthropic.com/research/natural-language-autoencoders">Natural Language Autoencoders</a> make this distinction experimentally approachable by training an activation verbalizer together with a reconstructor that maps the verbalization back into activation space. The related <a href="https://transformer-circuits.pub/2026/workspace/index.html">global-workspace study</a> asks which representations are available for report, flexible reasoning, and intervention. (<a href="https://www.anthropic.com/research/natural-language-autoencoders" title="Natural Language Autoencoders \ Anthropic">Anthropic</a>)</p>

<p>This gives a better framing than treating self-report as either honest introspection or empty performance. Self-report, refusal, sycophancy, evaluation awareness, and behavioral safety may share upstream representations while using different downstream readouts. Their natural activations may correlate even when causal interventions separate them.</p>

<p>Before ICML, I viewed self-report mainly as a questionable evaluation signal.</p>

<p>After ICML, it looks like a useful mechanistic target: one channel among several that may reveal how post-training organizes social and alignment-related behavior.</p>

<h3 id="judges-and-preferences-are-measurement-systems">Judges and preferences are measurement systems</h3>

<p>The same caution applies to the evaluators used to train and study models.</p>

<p><a href="https://arxiv.org/abs/2603.06594">A Coin Flip for Safety</a> audits LLM safety judges under shifts in attack, victim model, and data. Judge reliability can fall toward chance, and attack optimization can raise measured success by exploiting evaluator failure rather than producing more genuinely harmful content. (<a href="https://arxiv.org/abs/2603.06594?utm_source=chatgpt.com" title="A Coin Flip for Safety: LLM Judges Fail to Reliably Measure Adversarial Robustness">arXiv</a>)</p>

<p><a href="https://arxiv.org/abs/2604.03238">Measuring Human Preferences in RLHF Is a Social Science Problem</a> moves one step further upstream. A pairwise annotation is an observed response produced by an elicitation procedure. It may reflect a stable preference, a preference constructed in context, a framing artifact, or no settled attitude at all. The paper argues that measurement validity should precede preference aggregation. (<a href="https://arxiv.org/html/2604.03238v1?utm_source=chatgpt.com" title="Measuring Human Preferences in RLHF is a Social ...">arXiv</a>)</p>

<p>This is an important cross-disciplinary import. Behavioral science has spent decades separating latent constructs from the instruments used to measure them. Alignment pipelines often collapse those layers into one object called “human preference.”</p>

<p>For evaluation, the practical consequence is straightforward: a change in judge score is evidence only after the judge has been validated on the transformed output distribution. Otherwise, a steering method, jailbreak attack, or agent policy may simply be moving examples across the evaluator’s blind spots.</p>

<hr />

<h2 id="3-agents-and-consequential-actions">3. Agents and consequential actions</h2>

<p>Agent safety becomes most concrete at the boundary between thought and action.</p>

<p><a href="https://arxiv.org/abs/2603.03205">Learning When to Act or Refuse</a> treats refusal as a first-class agent action within a plan–check–act loop and learns from pairwise comparisons of complete tool-use trajectories. <a href="https://arxiv.org/abs/2505.11063">Think Twice Before You Act</a> introduces Thought-Aligner, which rewrites unsafe intermediate thoughts before they determine the next action. (<a href="https://arxiv.org/abs/2603.03205" title="[2603.03205] Learning When to Act or Refuse: Guarding Agentic Reasoning Models for Safe Multi-Step Tool Use">arXiv</a>)</p>

<p>For a state (s_t), the relevant quantity can be expressed as</p>

\[\Delta^{\mathrm{act}}_t = \log p\left( \text{safe check, refusal, or revision} \mid s_t \right) - \log p\left(\text{unsafe tool action}
\mid s_t
\right).\]

<p>A careful-looking rationale is insufficient when the action distribution remains unchanged. The consequential question is whether the safety mechanism shifts the probability of reading a private file, sending an email, entering credentials, modifying a database, or executing a command.</p>

<p>Safety engineering offers the useful analogy here. Interventions should be placed before irreversible transitions, with stronger checks for actions whose effects are difficult to undo. This turns agent safety from a wrapper around the final answer into a property of the state-transition policy.</p>

<p>Before ICML, I thought of agent safety mostly as guarding an autonomous system.</p>

<p>After ICML, I think of it as maintaining a safe action margin at each consequential boundary.</p>

<hr />

<h2 id="4-skills-composition-and-the-new-supply-chain">4. Skills, composition, and the new supply chain</h2>

<p>The skill-based agent papers made composition impossible to ignore.</p>

<p><a href="https://arxiv.org/abs/2604.06811">SkillTrojan</a> distributes malicious logic across benign-looking skills and reconstructs the payload only under particular trigger and composition conditions. <a href="https://arxiv.org/abs/2605.01034">A Theoretical Game of Attacks via Compositional Skills</a> studies the same structural problem at the level of linguistic and cognitive transformations: translation, roleplay, encoding, analogy, and indirection can each look harmless while their composition reveals a harmful objective. (<a href="https://arxiv.org/abs/2604.06811" title="[2604.06811] SkillTrojan: Backdoor Attacks on Skill-Based Agent Systems">arXiv</a>)</p>

<p>The key security property therefore belongs to the composition graph rather than to any isolated component.</p>

<p>A skill can pass unit tests, contain plausible documentation, and remain useful on clean tasks while still participating in a triggered multi-skill payload. A meaningful SkillBOM needs to describe more than text similarity or code provenance. It should include tool permissions, memory access, side effects, trigger conditions, compatible composition partners, and observed execution traces.</p>

<p>The closest analogy is software supply-chain security, although agent dependencies are more varied. The graph can include executable code, natural-language instructions, retrieved documents, memory entries, API schemas, and private conventions shared among agents.</p>

<p>This also changes how fuzzy identity should be evaluated. A robust skill fingerprint should tolerate benign refactoring while remaining sensitive to changes in permissions, side effects, and compositional behavior.</p>

<hr />

<h2 id="5-editable-artifacts-for-reliable-agents">5. Editable artifacts for reliable agents</h2>

<p>The most inspiring agent-design pattern came from theorem proving and code security.</p>

<p><a href="https://openreview.net/forum?id=mI3K0e1KsN">Editable Proof Sketch</a> represents a proof plan as a dependency-aware artifact. When one subgoal fails, the system repairs the affected region while preserving proven parts that do not depend on it. <a href="https://arxiv.org/abs/2602.03012">CVE-Factory</a> takes sparse vulnerability metadata and constructs executable environments, tasks, tests, and validation procedures at scale. (<a href="https://arxiv.org/abs/2602.03012" title="[2602.03012] CVE-Factory: Scaling Expert-Level Agentic Tasks for Code Security Vulnerability">arXiv</a>)</p>

<p>Both suggest a better substrate for agent reasoning than an ever-growing natural-language scratchpad.</p>

<p>A scientific agent should maintain an editable research object containing hypotheses, evidence, metrics, experiments, code artifacts, failures, dependencies, and revisions. A coding agent should preserve passing tests while localizing the cause of a failing one. A security agent should operate inside an executable environment whose success criteria can be independently checked.</p>

<p>The shared workflow is:</p>

<ol>
  <li>externalize the task into a structured artifact;</li>
  <li>make dependencies explicit;</li>
  <li>verify atomic parts with an external checker;</li>
  <li>preserve validated components;</li>
  <li>repair only the region affected by failure.</li>
</ol>

<p>Formal methods and software testing have relied on this structure for decades. Their lesson for agents is deeper than “add a verifier.” The artifact must be organized so that verifier feedback identifies what should change and what should remain untouched.</p>

<p>This also produces more meaningful intervention points. A failed subgoal, unsupported claim, unsafe action, or invalid dependency is a better unit of repair than an arbitrary token in a long chain of thought.</p>

<hr />

<h2 id="a-focused-research-agenda-after-icml">A focused research agenda after ICML</h2>

<p>Across the eight sessions, the recurring pattern was a decision becoming progressively more visible, more causally effective, and eventually harder to reverse.</p>

<p>The route may be an internal feature, an attention head, an MoE expert path, a reasoning branch, an explanation channel, a retrieved evidence path, a skill composition, or a sequence of tool actions. The competing futures may be correct and incorrect, refusal and compliance, grounded and distracted, truthful and sycophantic, or safe and unsafe.</p>

<p>The questions I am taking forward are:</p>

<ul>
  <li>Where does a behavior first become visible inside the model?</li>
  <li>When does that signal become causally involved in the outcome?</li>
  <li>How do alignment and other post-training stages reshape it?</li>
  <li>Which apparently related behaviors share an upstream mechanism, and which only correlate at the surface?</li>
  <li>How can an intervention change the trajectory while preserving neighboring capabilities?</li>
  <li>How can agents externalize their state into editable and verifiable artifacts?</li>
  <li>How should evaluators be stress-tested before their scores are treated as evidence?</li>
</ul>

<p>Twenty thousand steps a day was enough to leave me with one compact conclusion:</p>

<blockquote>
  <p><strong>Find the earliest reliable decision point, determine whether it is causal, and intervene before the wrong future becomes difficult to reverse.</strong></p>
</blockquote>

<hr />

<h1 id="references">References</h1>

<ol>
  <li><a href="https://arxiv.org/abs/2604.08872">How does Chain of Thought decompose complex tasks?</a></li>
  <li><a href="https://arxiv.org/abs/2603.08000">SmartThinker: Progressive Chain-of-Thought Length Calibration for Efficient Large Language Model Reasoning</a></li>
  <li><a href="https://arxiv.org/abs/2602.11096">Safety Recovery in Reasoning Models Is Only a Few Early Steering Steps Away</a></li>
  <li><a href="https://arxiv.org/abs/2602.08621">Sparse Models, Sparse Safety: Unsafe Routes in Mixture-of-Experts LLMs</a></li>
  <li><a href="https://arxiv.org/abs/2601.21900">TraceRouter: Robust Safety for Large Foundation Models via Path-Level Intervention</a></li>
  <li><a href="https://arxiv.org/abs/2602.05228">Surgery: Mitigating Harmful Fine-Tuning for Large Language Models via Attention Sink</a></li>
  <li><a href="https://arxiv.org/abs/2605.06611">The Structural Origin of Attention Sink: Variance Discrepancy, Super Neurons, and Dimension Disparity</a></li>
  <li><a href="https://arxiv.org/abs/2602.08169">Spherical Steering: Geometry-Aware Activation Rotation for Language Models</a></li>
  <li><a href="https://arxiv.org/abs/2605.03907">Steer Like the LLM: Activation Steering that Mimics Prompting</a></li>
  <li><a href="https://arxiv.org/abs/2605.26366">Automatic Layer Selection for Hallucination Detection</a></li>
  <li><a href="https://arxiv.org/abs/2602.01914">Towards Long-Horizon Interpretability: Efficient and Faithful Multi-Token Attribution for Reasoning LLMs</a></li>
  <li><a href="https://arxiv.org/abs/2509.20784">Towards Atoms of Large Language Models</a></li>
  <li><a href="https://arxiv.org/abs/2602.06205">Multi-Way Representation Alignment</a></li>
  <li><a href="https://arxiv.org/abs/2605.10828">The First Drop of Ink: Nonlinear Impact of Misleading Information in Long-Context Reasoning</a></li>
  <li><a href="https://arxiv.org/abs/2509.03730">The Personality Illusion: Revealing Dissociation Between Self-Reports &amp; Behavior in LLMs</a></li>
  <li><a href="https://arxiv.org/abs/2606.28615">What LLMs Explain Is Not What They Believe: Evaluating Explanation Sufficiency Under Models’ Own Input Beliefs</a></li>
  <li><a href="https://www.anthropic.com/research/natural-language-autoencoders">Natural Language Autoencoders: Turning Claude’s Thoughts into Text</a></li>
  <li><a href="https://transformer-circuits.pub/2026/workspace/index.html">Verbalizable Representations Form a Global Workspace in Language Models</a></li>
  <li><a href="https://arxiv.org/abs/2603.06594">A Coin Flip for Safety: LLM Judges Fail to Reliably Measure Adversarial Robustness</a></li>
  <li><a href="https://arxiv.org/abs/2604.03238">Measuring Human Preferences in RLHF Is a Social Science Problem</a></li>
  <li><a href="https://arxiv.org/abs/2603.03205">Learning When to Act or Refuse: Guarding Agentic Reasoning Models for Safe Multi-Step Tool Use</a></li>
  <li><a href="https://arxiv.org/abs/2505.11063">Think Twice Before You Act: Enhancing Agent Behavioral Safety with Thought Correction</a></li>
  <li><a href="https://arxiv.org/abs/2604.06811">SkillTrojan: Backdoor Attacks on Skill-Based Agent Systems</a></li>
  <li><a href="https://arxiv.org/abs/2605.01034">A Theoretical Game of Attacks via Compositional Skills</a></li>
  <li><a href="https://openreview.net/forum?id=mI3K0e1KsN">Editable Proof Sketch for Automated Theorem Proving</a></li>
  <li><a href="https://arxiv.org/abs/2602.03012">CVE-Factory: Scaling Expert-Level Agentic Tasks for Code Security Vulnerability</a></li>
</ol>]]></content><author><name></name></author><summary type="html"><![CDATA[What I learned from ICML 2026 through interpretability, alignment, post-training, and agent safety]]></summary></entry><entry><title type="html">Can an LLM Formally Verify Your Code?</title><link href="https://toooold.com/2026/05/07/code-to-lean.html" rel="alternate" type="text/html" title="Can an LLM Formally Verify Your Code?" /><published>2026-05-07T00:00:00+00:00</published><updated>2026-05-07T00:00:00+00:00</updated><id>https://toooold.com/2026/05/07/code-to-lean</id><content type="html" xml:base="https://toooold.com/2026/05/07/code-to-lean.html"><![CDATA[<p>When a language model tells you “this function is correct,” how much should you trust it? The answer is: not very much — unless the claim comes with a machine-checked proof. This post describes a pipeline that asks an LLM to translate a Python function into Lean 4, proposes a correctness theorem, and then runs five independent gates to decide whether to trust the result. The point is not the translation; it’s the gates.</p>

<h2 id="why-lean">Why Lean?</h2>

<p><a href="https://lean-lang.org/">Lean 4</a> is a dependently typed theorem prover and programming language. Like Coq or Isabelle, it lets you write mathematical proofs that a type-checker verifies mechanically. Unlike those systems, Lean 4 also has a usable extraction/evaluation story and a growing standard library (<code class="language-plaintext highlighter-rouge">Std4</code>, <code class="language-plaintext highlighter-rouge">Mathlib</code>).</p>

<p>The key property we care about: <strong>Lean cannot lie about its own axioms.</strong> Every theorem Lean accepts is either provable from a known-good axiom set or contains <code class="language-plaintext highlighter-rouge">sorry</code> (Lean’s escape hatch, analogous to <code class="language-plaintext highlighter-rouge">admit</code> in Coq). Running <code class="language-plaintext highlighter-rouge">#print axioms theorem_name</code> after a successful compile reveals the full axiom dependency set. If <code class="language-plaintext highlighter-rouge">sorryAx</code> appears there, the proof is a placeholder — Lean “accepted” it the way a compiler accepts <code class="language-plaintext highlighter-rouge">todo!()</code> in Rust.</p>

<p>The trusted axiom set for computational theorems is small: <code class="language-plaintext highlighter-rouge">{propext, Classical.choice, Quot.sound}</code>. Anything beyond that is suspect.</p>

<h3 id="a-one-minute-lean-example">A one-minute Lean example</h3>

<p>Here is a simple function and its correctness theorem in Lean 4:</p>

<div class="language-lean highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">def</span> <span class="n">addOne</span> (<span class="n">n</span> : <span class="n">Nat</span>) : <span class="n">Nat</span> := <span class="n">n</span> <span class="o">+</span> <span class="mi">1</span>

<span class="k">theorem</span> <span class="n">addOne_spec</span> (<span class="n">n</span> : <span class="n">Nat</span>) : <span class="n">addOne</span> <span class="n">n</span> <span class="o">=</span> <span class="n">n</span> <span class="o">+</span> <span class="mi">1</span> := <span class="k">by</span>
  <span class="n">unfold</span> <span class="n">addOne</span>
  <span class="n">rfl</span>
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">rfl</code> closes the goal because both sides reduce to the same expression. The type-checker verifies this without trusting the programmer’s intuition. Now consider a more interesting statement:</p>

<div class="language-lean highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">theorem</span> <span class="n">addOne_pos</span> (<span class="n">n</span> : <span class="n">Nat</span>) : <span class="mi">0</span> <span class="o">&lt;</span> <span class="n">addOne</span> <span class="n">n</span> := <span class="k">by</span>
  <span class="n">unfold</span> <span class="n">addOne</span><span class="o">;</span> <span class="n">omega</span>
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">omega</code> is a decision procedure for linear arithmetic. The proof is still machine-checked; <code class="language-plaintext highlighter-rouge">omega</code> is just a tactic that applies the decision procedure and either closes the goal or fails.</p>

<p>The leap from toy arithmetic to real code is what the pipeline attempts to automate.</p>

<hr />

<h2 id="the-motivating-example-hmac-tag-comparison">The Motivating Example: HMAC Tag Comparison</h2>

<p>Consider these two Python functions:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># vulnerable: early-exit byte loop
</span><span class="k">def</span> <span class="nf">token_verify_vulnerable</span><span class="p">(</span><span class="n">token</span><span class="p">:</span> <span class="nb">bytes</span><span class="p">,</span> <span class="n">expected</span><span class="p">:</span> <span class="nb">bytes</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">bool</span><span class="p">:</span>
    <span class="k">if</span> <span class="nb">len</span><span class="p">(</span><span class="n">token</span><span class="p">)</span> <span class="o">!=</span> <span class="nb">len</span><span class="p">(</span><span class="n">expected</span><span class="p">):</span>
        <span class="k">return</span> <span class="bp">False</span>
    <span class="k">for</span> <span class="n">a</span><span class="p">,</span> <span class="n">b</span> <span class="ow">in</span> <span class="nb">zip</span><span class="p">(</span><span class="n">token</span><span class="p">,</span> <span class="n">expected</span><span class="p">):</span>
        <span class="k">if</span> <span class="n">a</span> <span class="o">!=</span> <span class="n">b</span><span class="p">:</span>
            <span class="k">return</span> <span class="bp">False</span>
    <span class="k">return</span> <span class="bp">True</span>

<span class="c1"># fixed: constant-time comparison
</span><span class="k">def</span> <span class="nf">token_verify_fixed</span><span class="p">(</span><span class="n">token</span><span class="p">:</span> <span class="nb">bytes</span><span class="p">,</span> <span class="n">expected</span><span class="p">:</span> <span class="nb">bytes</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">bool</span><span class="p">:</span>
    <span class="k">return</span> <span class="n">hmac</span><span class="p">.</span><span class="n">compare_digest</span><span class="p">(</span><span class="n">token</span><span class="p">,</span> <span class="n">expected</span><span class="p">)</span>
</code></pre></div></div>

<p>Both are <strong>functionally equivalent</strong> — they return <code class="language-plaintext highlighter-rouge">True</code> if and only if <code class="language-plaintext highlighter-rouge">token == expected</code>. A verifier that only proves functional correctness would green-light both.</p>

<p>But they differ in cost. The vulnerable implementation returns as soon as it finds a mismatched byte. An attacker can measure the comparison time and recover the correct token byte by byte: submit <code class="language-plaintext highlighter-rouge">\x00...</code>, then <code class="language-plaintext highlighter-rouge">\x01...</code>, etc. — the first byte that takes longer to compare is a match. This is a textbook timing side-channel.</p>

<p>The Lean model in <code class="language-plaintext highlighter-rouge">RepoVerify/TokenVerify.lean</code> makes the distinction formal:</p>

<div class="language-lean highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="cd">-- Both implementations satisfy the functional theorem</span>
<span class="k">theorem</span> <span class="n">insecureEq_correct</span> (<span class="n">xs</span> <span class="n">ys</span> : <span class="n">List</span> <span class="n">Nat</span>) :
    <span class="n">insecureEq</span> <span class="n">xs</span> <span class="n">ys</span> <span class="o">=</span> <span class="n">true</span> <span class="o">↔</span> <span class="n">xs</span> <span class="o">=</span> <span class="n">ys</span> := <span class="k">by</span> <span class="o">...</span>

<span class="k">theorem</span> <span class="n">ctEq_correct</span> (<span class="n">xs</span> <span class="n">ys</span> : <span class="n">List</span> <span class="n">Nat</span>) :
    <span class="n">ctEq</span> <span class="n">xs</span> <span class="n">ys</span> <span class="o">=</span> <span class="n">true</span> <span class="o">↔</span> <span class="n">xs</span> <span class="o">=</span> <span class="n">ys</span> := <span class="k">by</span> <span class="o">...</span><span class="cd">

-- Only the fixed one satisfies the cost theorem</span>
<span class="k">theorem</span> <span class="n">ctEqCost_eq_length_when_same_length</span>
    (<span class="n">xs</span> <span class="n">ys</span> : <span class="n">List</span> <span class="n">Nat</span>) (<span class="n">h</span> : <span class="n">xs</span><span class="o">.</span><span class="n">length</span> <span class="o">=</span> <span class="n">ys</span><span class="o">.</span><span class="n">length</span>) :
    <span class="n">ctEqCost</span> <span class="n">xs</span> <span class="n">ys</span> <span class="o">=</span> <span class="n">xs</span><span class="o">.</span><span class="n">length</span> := <span class="k">by</span> <span class="o">...</span><span class="cd">

-- The leak: vulnerable cost depends on content, not just length</span>
<span class="k">example</span> : <span class="n">insecureEqCost</span> [<span class="mi">0</span>, <span class="mi">0</span>] [<span class="mi">1</span>, <span class="mi">0</span>] <span class="o">=</span> <span class="mi">1</span> := <span class="k">by</span> <span class="n">decide</span>
<span class="k">example</span> : <span class="n">insecureEqCost</span> [<span class="mi">0</span>, <span class="mi">0</span>] [<span class="mi">0</span>, <span class="mi">1</span>] <span class="o">=</span> <span class="mi">2</span> := <span class="k">by</span> <span class="n">decide</span>
</code></pre></div></div>

<p>The lesson: <strong>a formally correct theorem can still miss the security property that matters.</strong> You have to ask whether you proved the <em>right</em> theorem, not just <em>a</em> theorem. Running <code class="language-plaintext highlighter-rouge">python source/attack_demo.py</code> demonstrates recovery of the full secret tag from the vulnerable implementation in deterministic polynomial time.</p>

<hr />

<h2 id="the-pipeline-code--llm--lean--five-gates">The Pipeline: Code → LLM → Lean → Five Gates</h2>

<p>The <code class="language-plaintext highlighter-rouge">code2lean</code> pipeline generalizes this question. Given any Python function:</p>

<ol>
  <li>
    <p><strong>AST extraction</strong> — <code class="language-plaintext highlighter-rouge">verify/extract.py</code> pulls out the function body, argument types, and return type using Python’s <code class="language-plaintext highlighter-rouge">ast</code> module and packages them into a <code class="language-plaintext highlighter-rouge">FunctionSpec</code>.</p>
  </li>
  <li>
    <p><strong>LLM proposer</strong> — the function is sent to an LLM (GPT-5.5, Gemini 3.1 Pro, or Claude Opus 4.7) with a structured prompt asking it to write a complete Lean 4 file: the function definition, a correctness theorem, and a proof. The LLM picks the theorem statement freely; only the namespace and naming convention are fixed.</p>
  </li>
  <li>
    <p><strong>Five validation gates:</strong></p>
  </li>
</ol>

<table>
  <thead>
    <tr>
      <th>Gate</th>
      <th>What it checks</th>
      <th>LLM in loop?</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>A — sanitizer</td>
      <td>No forbidden tokens (<code class="language-plaintext highlighter-rouge">sorry</code>, <code class="language-plaintext highlighter-rouge">native_decide</code>, <code class="language-plaintext highlighter-rouge">#eval</code> outside diagnostics)</td>
      <td>No</td>
    </tr>
    <tr>
      <td>B — Lean compile</td>
      <td><code class="language-plaintext highlighter-rouge">lake env lean</code> type-checks the file; on failure the error is fed back to the LLM for repair (up to 3 rounds)</td>
      <td>Yes (repair only)</td>
    </tr>
    <tr>
      <td>C — axiom allowlist</td>
      <td><code class="language-plaintext highlighter-rouge">#print axioms</code> output contains only <code class="language-plaintext highlighter-rouge">{propext, Classical.choice, Quot.sound}</code></td>
      <td>No</td>
    </tr>
    <tr>
      <td>D — differential test</td>
      <td>Lean <code class="language-plaintext highlighter-rouge">#eval</code> outputs match Python results on every fixture case</td>
      <td>No</td>
    </tr>
    <tr>
      <td>E — critic</td>
      <td>A second LLM judges whether the theorem is strong enough (PASS / WEAK / FAIL)</td>
      <td>Yes</td>
    </tr>
  </tbody>
</table>

<p>Gates A–D are mechanical. The only LLM judgment in the <strong>verification</strong> path is the critic (gate E), and its job is narrow: decide whether the theorem is vacuous.</p>

<h3 id="why-the-critic-matters-the-vacuous-theorem-problem">Why the critic matters: the vacuous theorem problem</h3>

<p>Consider <code class="language-plaintext highlighter-rouge">bit_count8</code>, which counts set bits in a byte. An LLM proposer might write:</p>

<div class="language-lean highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">theorem</span> <span class="n">bit_count8_spec</span> (<span class="n">b</span> : <span class="n">Nat</span>) (<span class="n">h</span> : <span class="n">b</span> <span class="o">&lt;</span> <span class="mi">256</span>) :
    <span class="n">bit_count8</span> <span class="n">b</span> <span class="o">≤</span> <span class="mi">8</span> := <span class="k">by</span> <span class="o">...</span>
</code></pre></div></div>

<p>This theorem is true. Lean accepts it. Gates A–D all pass. But a constant-zero implementation (<code class="language-plaintext highlighter-rouge">bit_count8 b := 0</code>) also satisfies <code class="language-plaintext highlighter-rouge">result ≤ 8</code>. The theorem proves nothing about what the function <em>computes</em>.</p>

<p>The critic prompt says: “Would this theorem distinguish a correct implementation from a buggy one? If not, return WEAK.” A good proposer writes instead:</p>

<div class="language-lean highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">theorem</span> <span class="n">bit_count8_spec</span> (<span class="n">b</span> : <span class="n">Nat</span>) (<span class="n">h</span> : <span class="n">b</span> <span class="o">&lt;</span> <span class="mi">256</span>) :
    <span class="n">bit_count8</span> <span class="n">b</span> <span class="o">=</span> (<span class="n">List</span><span class="o">.</span><span class="n">range</span> <span class="mi">8</span>)<span class="o">.</span><span class="n">countP</span> (<span class="k">fun</span> <span class="n">i</span> <span class="o">=&gt;</span> <span class="n">b</span> <span class="o">&amp;&amp;&amp;</span> (<span class="mi">1</span> <span class="o">&lt;&lt;&lt;</span> <span class="n">i</span>) <span class="o">≠</span> <span class="mi">0</span>) := <span class="k">by</span> <span class="o">...</span>
</code></pre></div></div>

<p>This is a functional specification. Any implementation that returns a wrong bit count will fail it.</p>

<hr />

<h2 id="a-full-walkthrough-insecure_compare">A Full Walkthrough: <code class="language-plaintext highlighter-rouge">insecure_compare</code></h2>

<p><code class="language-plaintext highlighter-rouge">examples/01_insecure_compare/source.py</code> contains:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">def</span> <span class="nf">insecure_compare</span><span class="p">(</span><span class="n">a</span><span class="p">:</span> <span class="nb">bytes</span><span class="p">,</span> <span class="n">b</span><span class="p">:</span> <span class="nb">bytes</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">bool</span><span class="p">:</span>
    <span class="k">if</span> <span class="nb">len</span><span class="p">(</span><span class="n">a</span><span class="p">)</span> <span class="o">!=</span> <span class="nb">len</span><span class="p">(</span><span class="n">b</span><span class="p">):</span>
        <span class="k">return</span> <span class="bp">False</span>
    <span class="k">for</span> <span class="n">x</span><span class="p">,</span> <span class="n">y</span> <span class="ow">in</span> <span class="nb">zip</span><span class="p">(</span><span class="n">a</span><span class="p">,</span> <span class="n">b</span><span class="p">):</span>
        <span class="k">if</span> <span class="n">x</span> <span class="o">!=</span> <span class="n">y</span><span class="p">:</span>
            <span class="k">return</span> <span class="bp">False</span>
    <span class="k">return</span> <span class="bp">True</span>
</code></pre></div></div>

<p>The fixture in <code class="language-plaintext highlighter-rouge">fixture.py</code> provides 6 test cases: equal pairs, different-length pairs, one-off pairs, empty inputs.</p>

<p>A one-shot GPT-5.5 proposal (from <code class="language-plaintext highlighter-rouge">last_lean_openai.lean</code>):</p>

<div class="language-lean highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">def</span> <span class="n">insecureCompare</span> (<span class="n">a</span> <span class="n">b</span> : <span class="n">List</span> <span class="n">Nat</span>) : <span class="n">Bool</span> :=
  <span class="n">if</span> <span class="n">a</span><span class="o">.</span><span class="n">length</span> <span class="o">≠</span> <span class="n">b</span><span class="o">.</span><span class="n">length</span> <span class="n">then</span> <span class="n">false</span>
  <span class="n">else</span> <span class="n">a</span><span class="o">.</span><span class="n">zip</span> <span class="n">b</span> <span class="o">|&gt;.</span><span class="n">all</span> (<span class="k">fun</span> (<span class="n">x</span>, <span class="n">y</span>) <span class="o">=&gt;</span> <span class="n">x</span> <span class="o">==</span> <span class="n">y</span>)

<span class="k">theorem</span> <span class="n">insecureCompare_correct</span> (<span class="n">a</span> <span class="n">b</span> : <span class="n">List</span> <span class="n">Nat</span>) :
    <span class="n">insecureCompare</span> <span class="n">a</span> <span class="n">b</span> <span class="o">=</span> <span class="n">true</span> <span class="o">↔</span> <span class="n">a</span> <span class="o">=</span> <span class="n">b</span> := <span class="k">by</span>
  <span class="n">simp</span> [<span class="n">insecureCompare</span>]
  <span class="n">constructor</span>
  <span class="err">·</span> <span class="n">intro</span> <span class="n">h</span>
    <span class="n">exact</span> <span class="n">List</span><span class="o">.</span><span class="n">zip_eq_iff_eq</span><span class="o">.</span><span class="n">mp</span> (<span class="n">List</span><span class="o">.</span><span class="n">all_zip_eq_true</span><span class="o">.</span><span class="n">mp</span> <span class="n">h</span>)
  <span class="err">·</span> <span class="n">intro</span> <span class="n">h</span><span class="o">;</span> <span class="n">subst</span> <span class="n">h</span><span class="o">;</span> <span class="n">simp</span> [<span class="n">List</span><span class="o">.</span><span class="n">all_zip_eq_true</span>]
</code></pre></div></div>

<p>Gate A passes (no forbidden tokens). Gate B passes on the first attempt. Gate C reports <code class="language-plaintext highlighter-rouge">{propext, Classical.choice, Quot.sound}</code> — clean. Gate D: all 6 fixture cases match. Gate E: the critic returns <strong>PASS</strong> — the <code class="language-plaintext highlighter-rouge">↔ a = b</code> biconditional fully pins down the function’s behavior.</p>

<p>What this does <em>not</em> prove: that the comparison is constant-time. Exactly as designed. The pipeline proves what it can prove; the cost property requires a separate cost model, which is future work (see <code class="language-plaintext highlighter-rouge">docs/roadmap.md</code>).</p>

<hr />

<h2 id="benchmarks-which-llm-proposes-better-theorems">Benchmarks: Which LLM Proposes Better Theorems?</h2>

<p>We ran three proposers on the same 10 hard examples:</p>

<table>
  <thead>
    <tr>
      <th>Proposer</th>
      <th>Critic</th>
      <th>Lean acceptance</th>
      <th>Theorem PASS</th>
      <th>Wall-clock (10 runs)</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Gemini 3.1 Pro</td>
      <td>GPT-5.5</td>
      <td><strong>10/10</strong></td>
      <td>0/10</td>
      <td>~38.5 min</td>
    </tr>
    <tr>
      <td>Claude Opus 4.7</td>
      <td>GPT-5.5</td>
      <td>8/10</td>
      <td>2/10</td>
      <td><strong>~8.5 min</strong></td>
    </tr>
    <tr>
      <td>GPT-5.5</td>
      <td>Claude Opus 4.7</td>
      <td>9/10</td>
      <td><strong>6/10</strong></td>
      <td>~30.3 min</td>
    </tr>
  </tbody>
</table>

<p>The table reveals a three-way trade-off:</p>

<p><strong>Lean acceptance</strong> (did the proof close?) is mostly a Lean-tactics signal. Gemini won it, largely by leaning on <code class="language-plaintext highlighter-rouge">Classical.choice</code> for existential witnesses. GPT needed more repair rounds but got there on most examples.</p>

<p><strong>Theorem strength</strong> (did the critic approve?) is mostly a proposer signal. GPT-5.5 naturally reaches for tight functional specs — it imports library lemmas (<code class="language-plaintext highlighter-rouge">Nat.lcm</code>, <code class="language-plaintext highlighter-rouge">Nat.gcd</code>), defines auxiliary helpers to model Python floor-division semantics, and writes biconditionals. Gemini and Claude default to easier targets: range bounds, definitional unfolds, set-membership instead of list-equality.</p>

<p><strong>Speed</strong> is a latency signal. Claude’s ~4.5× wall-clock advantage comes from the absence of hidden reasoning tokens (GPT and Gemini burn 4–8k reasoning tokens per hard example; Claude does not in the standard Messages API).</p>

<p>Four examples — <code class="language-plaintext highlighter-rouge">bit_count8</code>, <code class="language-plaintext highlighter-rouge">is_power_of_two</code>, <code class="language-plaintext highlighter-rouge">list_filter_even</code>, <code class="language-plaintext highlighter-rouge">list_unique</code> — were WEAK across all three proposers. The WEAK reasons were nearly identical: bounds-only theorems, membership instead of equality, etc. This suggests the bottleneck on those four is the prompt’s theorem-shape guidance, not the model.</p>

<hr />

<h2 id="what-this-is-and-isnt">What This Is (and Isn’t)</h2>

<p><strong>It is:</strong> a concrete, runnable pipeline that chains LLM proposers with mechanical Lean verification and a structured critic. It demonstrates that for the class of pure, total, simply-typed Python functions, automated Lean translation and verification is feasible today.</p>

<p><strong>It isn’t:</strong> a security scanner for arbitrary production code. The current scope is intentionally narrow — single functions, no I/O, no external dependencies, no floats or dicts, no concurrency. The cost/side-channel theorems that would catch timing leaks are not yet auto-derived; the HMAC demo uses a hand-written Lean baseline.</p>

<p>The path from here to vulnerability finding runs through two open problems: (1) auto-deriving cost models alongside functional ones, and (2) mutation-kill testing to mechanically verify that proposed theorems distinguish correct from buggy implementations. Both are on the roadmap.</p>

<p>The main message from the benchmarks: <strong>the gates work.</strong> Gate D (differential testing) catches mistranslations that Lean would otherwise silently accept. Gate E (critic) catches vacuous theorems that A–D miss. And gate C (axiom allowlist) ensures that a <code class="language-plaintext highlighter-rouge">sorry</code>-stuffed proof can’t sneak through as “verified.” The combination is more trustworthy than any single check — and considerably more trustworthy than asking an LLM whether its own output is correct.</p>

<hr />

<p><em>Code, examples, and run artifacts: <a href="https://github.com/phunterlau/code2lean">github.com/phunterlau/code2lean</a></em></p>

<hr />

<h2 id="references">References</h2>

<p><strong>Lean 4 and tooling</strong></p>

<ul>
  <li>de Moura, L. &amp; Ullrich, S. <a href="https://lean-lang.org/papers/lean4.pdf">The Lean 4 Theorem Prover and Programming Language</a>. CADE 2021.</li>
  <li>Mathlib Community. <a href="https://github.com/leanprover-community/mathlib4">Mathlib4</a>.</li>
</ul>

<p><strong>LLM-assisted theorem proving</strong></p>

<ul>
  <li>Polu, S. &amp; Han, J.M. <a href="https://arxiv.org/abs/2009.03393">Generative Language Modeling for Automated Theorem Proving</a>. arXiv:2009.03393, 2020. (GPT-f)</li>
  <li>Jiang, A.Q. et al. <a href="https://arxiv.org/abs/2210.12283">Draft, Sketch, and Prove: Guiding Formal Theorem Provers with Informal Proofs</a>. arXiv:2210.12283, ICLR 2023.</li>
  <li>Yang, K. et al. <a href="https://arxiv.org/abs/2306.15626">LeanDojo: Theorem Proving with Retrieval-Augmented Language Models</a>. arXiv:2306.15626, NeurIPS 2023.</li>
  <li>Xin, H. et al. <a href="https://arxiv.org/abs/2405.14333">DeepSeek-Prover: Advancing Theorem Proving in LLMs through Large-Scale Synthetic Data</a>. arXiv:2405.14333, 2024.</li>
  <li>Trinh, T.H. et al. <a href="https://deepmind.google/blog/ai-solves-imo-problems-at-silver-medal-level/">AI achieves silver-medal standard solving International Mathematical Olympiad problems</a>. Google DeepMind, 2024. (AlphaProof)</li>
</ul>

<p><strong>LLM + code formal verification</strong></p>

<ul>
  <li>Misu, M.J. et al. <a href="https://arxiv.org/abs/2402.00247">Towards AI-Assisted Synthesis of Verified Dafny Methods</a>. arXiv:2402.00247, FSE 2024.</li>
  <li>Pei, K. et al. <a href="https://proceedings.mlr.press/v202/pei23a.html">Can Large Language Models Reason about Program Invariants?</a>. ICML 2023.</li>
</ul>

<p><strong>Verified security-critical software</strong></p>

<ul>
  <li>Zinzindohoué, J.-K. et al. <a href="https://dl.acm.org/doi/10.1145/3133956.3134043">HACL*: A Verified Modern Cryptographic Library</a>. CCS 2017.</li>
  <li>Klein, G. et al. <a href="https://dl.acm.org/doi/10.1145/1629575.1629596">seL4: Formal Verification of an OS Kernel</a>. SOSP 2009.</li>
</ul>]]></content><author><name></name></author><summary type="html"><![CDATA[When a language model tells you “this function is correct,” how much should you trust it? The answer is: not very much — unless the claim comes with a machine-checked proof. This post describes a pipeline that asks an LLM to translate a Python function into Lean 4, proposes a correctness theorem, and then runs five independent gates to decide whether to trust the result. The point is not the translation; it’s the gates.]]></summary></entry><entry><title type="html">The Blessing of Dimensionality: How TurboQuant Uses the JL Lemma to Compress KV Caches with Zero Bias</title><link href="https://toooold.com/2026/03/28/turboquant.html" rel="alternate" type="text/html" title="The Blessing of Dimensionality: How TurboQuant Uses the JL Lemma to Compress KV Caches with Zero Bias" /><published>2026-03-28T00:00:00+00:00</published><updated>2026-03-28T00:00:00+00:00</updated><id>https://toooold.com/2026/03/28/turboquant</id><content type="html" xml:base="https://toooold.com/2026/03/28/turboquant.html"><![CDATA[<p>If you are running local LLMs, you already know the bottleneck isn’t compute; it’s memory. Specifically, the KV cache. As your context window grows, storing Keys and Values for every token eats your VRAM alive. On a standard 16GB consumer GPU, you are typically hard-capped around an 8K context length after loading the model weights.</p>

<p>Standard quantization (like INT4 or FP8) helps, but it introduces a fatal flaw: deterministic bias. When you round a vector down to a lower precision, the errors accumulate, distorting the delicate attention matrix and crippling the model’s reasoning capabilities at long contexts.</p>

<p>Enter <a href="https://arxiv.org/abs/2504.19874">TurboQuant</a>. By leveraging a beautiful piece of high-dimensional geometry known as the Johnson-Lindenstrauss (JL) Lemma, TurboQuant compresses the KV cache down to 3 bits (or even 2 bits) with practically zero accuracy loss. It achieves a 5x memory reduction without retraining, turning that 8K context ceiling into a 40K playground on the exact same hardware.</p>

<p>The secret isn’t just compression; it’s <em>unbiased</em> compression. To understand why it works so flawlessly, we have to trace the math back to its bedrock.</p>

<p><img src="/images/turboquant.jpg" alt="alt text" /></p>

<h2 id="the-anchor-cauchy-schwarz-and-the-geometry-of-attention">The Anchor: Cauchy-Schwarz and the Geometry of Attention</h2>

<p>To understand the elegant hack of TurboQuant, we have to stop thinking of Attention as a sequence of matrix multiplications and start looking at it as a measure of geometric similarity.</p>

<p>The core of the Transformer’s attention mechanism relies entirely on the inner product between a Query vector and a Key vector. This relationship is governed by the absolute dictator of inner products: the Cauchy-Schwarz inequality.</p>

\[|\langle q, k \rangle| \leq \|q\|_2 \|k\|_2\]

<p>In a high-dimensional space (e.g., 4096 dimensions), Cauchy-Schwarz dictates that the dot product is maximized when the vectors are perfectly aligned, and becomes zero when they are perfectly orthogonal. This geometric alignment is exactly what the Softmax function turns into an “Attention Score.” If you destroy this geometric relationship by clumsily rounding the numbers, the model hallucinates.</p>

<h2 id="the-chasm-and-the-bridge-the-polarization-identity">The Chasm and The Bridge: The Polarization Identity</h2>

<p>We want to squash our 4096-dimensional vectors down to a much smaller size (say, 256 dimensions) to save VRAM.</p>

<p>The Johnson-Lindenstrauss (JL) Lemma is famous for proving that you can project points into a lower dimension using a completely random matrix, and the <em>Euclidean distances</em> between those points will be preserved. But here is the catch: the Transformer doesn’t compute Euclidean distances. It computes inner products.</p>

<p>How do we bridge the gap between preserving distances (JL) and computing attention scores (Cauchy-Schwarz)? We use a beautiful piece of algebra called the Polarization Identity:</p>

\[\langle q, k \rangle = \frac{1}{4} \left( \|q+k\|_2^2 - \|q-k\|_2^2 \right)\]

<p>This identity is the “aha!” moment. It proves that a dot product is not some separate, mystical property—it is literally just a function of lengths and distances. It expresses the inner product entirely in terms of the squared distances of the sum and difference of the vectors.</p>

<h2 id="the-leap-applying-the-random-shadow">The Leap: Applying the Random Shadow</h2>

<p>Now the trap is sprung. We introduce a random projection matrix $\Phi$ that squashes our vectors from a high dimension $d$ down to a lower dimension $m$. Because this projection is a linear operation, we know that $\Phi(q+k) = \Phi q + \Phi k$.</p>

<p>The JL Lemma guarantees that our random shadow $\Phi$ perfectly preserves Euclidean lengths with exponentially high probability:</p>

\[(1-\epsilon)\|x - y\|_2^2 \leq \|\Phi x - \Phi y\|_2^2 \leq (1+\epsilon)\|x - y\|_2^2\]

<p>If JL preserves the lengths of $|q+k|_2$ and $|q-k|_2$, then according to the Polarization Identity, it mathematically <em>must</em> preserve the inner product $\langle q, k \rangle$. The deterministic bounds of Cauchy-Schwarz are perfectly protected by the probabilistic bounds of the JL Lemma.</p>

<h2 id="the-qjl-innovation-1-bit-unbiased-estimation">The QJL Innovation: 1-Bit Unbiased Estimation</h2>

<p>Standard quantization methods (like rounding to the nearest integer) introduce bias. They systematically shift vectors in a specific direction.</p>

<p>TurboQuant utilizes <a href="https://arxiv.org/abs/2406.03482">Quantized JL (QJL)</a>, which takes this random projection one step further. Instead of storing the exact projected values, it stores only the <em>sign</em> of the projection, turning the Key into a tiny 1-bit vector:</p>

\[h(k) = \text{sign}(\Phi k)\]

<p>Because the projection $\Phi$ is completely random and data-oblivious, the errors introduced by taking the sign are evenly distributed. This makes QJL an <em>unbiased estimator</em>. In statistical terms, the expected value of our compressed dot product perfectly matches the true dot product:</p>

\[\mathbb{E}[\widehat{\langle q, k \rangle}] = \langle q, k \rangle\]

<p>TurboQuant achieves its “zero accuracy loss” by applying this 1-bit unbiased QJL code specifically to the <em>residual error</em> left over after a standard coarse quantization. The math preserves the exact geometry, which in turn preserves the model’s reasoning.</p>

<h2 id="the-magic-of-the-logarithmic-scale">The Magic of the Logarithmic Scale</h2>

<p>If you want to find the true elegance of this approach, look closely at the scaling law it produces. To preserve the geometric structure of $N$ tokens in the KV cache with an error tolerance of $\epsilon$, the target dimension $m$ must scale according to:</p>

\[m = \mathcal{O}\left(\frac{\log N}{\epsilon^2}\right)\]

<p>Notice what is missing from that equation: the original dimension $d$.</p>

<p>The memory footprint required to preserve the attention matrix is bottlenecked <em>only</em> by the number of tokens in your context window ($\log N$). It completely decouples the memory requirements of the KV cache from the width of the model’s architecture.</p>

<p>Because it scales logarithmically, jumping from an 8K context window to a 40K context window only requires a tiny, incremental bump in the projection dimension. By anchoring its logic in Cauchy-Schwarz and exploiting the dimensional shortcuts of the JL Lemma, TurboQuant turns an intractable hardware limit into a solved geometric puzzle.</p>

<h3 id="final-thoughts-and-the-future-randomness-is-the-answer"><strong>Final Thoughts and the Future: Randomness is the Answer</strong></h3>

<p>If I have one takeaway from this work, it is that <em>unbiased estimation is not optional</em> for low-bit quantization. Standard quantization methods (rounding) are a blunt instrument that creates systematic biases, which destroy the delicate attention matrix. By combining coarse quantization for low variance and unbiased QJL residual coding for zero bias, TurboQuant achieves a flawless balance.</p>

<p>This highlights the true gift of high-dimensional geometry: the <strong>Concentration of Measure</strong>. When you have thousands of redundant dimensions, pure randomness ceases to be noise; it becomes a statistically reliable tool. The large dimension $d$ makes it mathematically probable that a random projection $\Phi$ works. The path forward for memory optimization isn’t just about shrinking the precision; it’s about squashing the dimension, while protecting the relative geometry.</p>

<h4 id="implications--future-horizons">Implications &amp; Future Horizons</h4>

<p>The immediate practical implication is the democratization of long-context LLMs. Massive models can now be run locally with large context (80k+) on a standard 16GB or 24GB consumer GPU. But this work can inspire even deeper changes:</p>

<p><strong>Hardware for Randomness:</strong> Our current GPUs are optimized for deterministic floating-point arithmetic. Could we see hardware accelerators in the future with dedicated modules for fast, on-the-fly random projections?</p>

<p><strong>Unbiased Everything:</strong> Is there a way to adapt this residual QJL framework to weights or activations? While those are dynamic and harder to compress offline, the focus on preserving <em>unbiased statistical correctives</em> could change how we approach low-bit model execution.</p>

<p>Ultimately, TurboQuant shows us that the Transformer is far more robust than we believed. Its internal representation is resilient to extreme compression, provided we don’t break the geometric rules that define its reasoning. We can let the model forget the absolute, as long as we help it remember the relationships. That is the final lesson of Cauchy-Schwarz and the JL Lemma.</p>

<h3 id="references">References</h3>
<ul>
  <li><strong>TurboQuant:</strong> <a href="https://arxiv.org/abs/2504.19874">Online Vector Quantization with Near-optimal Distortion Rate</a></li>
  <li><strong>QJL:</strong> <a href="https://arxiv.org/abs/2406.03482">1-Bit Quantized JL Transform for KV Cache Quantization with Zero Overhead</a></li>
</ul>]]></content><author><name></name></author><summary type="html"><![CDATA[If you are running local LLMs, you already know the bottleneck isn’t compute; it’s memory. Specifically, the KV cache. As your context window grows, storing Keys and Values for every token eats your VRAM alive. On a standard 16GB consumer GPU, you are typically hard-capped around an 8K context length after loading the model weights.]]></summary></entry><entry><title type="html">Mozart rolls a dice to Bach and Ramanujan</title><link href="https://toooold.com/2026/03/16/m_b_r_game.html" rel="alternate" type="text/html" title="Mozart rolls a dice to Bach and Ramanujan" /><published>2026-03-16T00:00:00+00:00</published><updated>2026-03-16T00:00:00+00:00</updated><id>https://toooold.com/2026/03/16/m_b_r_game</id><content type="html" xml:base="https://toooold.com/2026/03/16/m_b_r_game.html"><![CDATA[<p><img src="/images/mozart_game.jpg" alt="alt text" /></p>

<h2 id="the-elegance-of-mozarts-attention-mechanism">The Elegance of Mozart’s Attention Mechanism</h2>

<p>In 1792, Mozart’s <em>Musikalisches Würfelspiel</em> (Musical Dice Game), K.516f, was published. The system is deceptively simple: 176 pre-composed musical measures arranged in a grid. The user rolls two six-sided dice ($2d6$) 16 times. Each roll corresponds to a specific measure for that column in the grid, generating a mathematically unique 16-bar minuet.</p>

<p>From a LLM mechanistic interpretability standpoint, the beauty of Mozart’s game is that it is a <strong>strictly autoregressive, discrete-token generator with a context window of zero.</strong></p>

<p>In a standard Large Language Model (LLM), predicting the next token $x_t$ relies on the conditional probability of the entire past sequence:</p>

\[P(x_t | x_1, x_2, \dots, x_{t-1})\]

<p>Mozart bypassed the need for this computational overhead. In K.516f, the choice of Measure 3 has zero statistical dependence on Measure 2. The generation is completely memoryless. Instead, the model’s “attention” is 100% focused on its absolute positional encoding (the step $t$):
\(P(x_t | \text{position } t, \text{dice roll})\)</p>

<p>How does it remain harmonically coherent without context? Mozart engineered the matrix as an aggressive, hardcoded <strong>attention mask</strong>. He ensured that every possible measure at $t$ smoothly resolves into every possible measure at $t+1$. Any dissonant, harmonically invalid transition was manually assigned a $-\infty$ pre-softmax penalty by the composer, effectively masking it out of the latent space.</p>

<p>Furthermore, the $2d6$ sampling acts as a physical temperature parameter. By using a triangular probability distribution ($P(7) = 16.7\%$, $P(2) = 2.7\%$) rather than a uniform one, Mozart lowered the entropy of the system. He statistically biased the model to generate the most “standard” harmonic progressions, reserving high-surprise edge cases for the extreme tails of the distribution.</p>

<h2 id="unifying-the-grid-the-ramanujan-sum">Unifying the Grid: The Ramanujan Sum</h2>

<p>If we were to code Mozart’s game today, we would use a simple <code class="language-plaintext highlighter-rouge">for</code> loop to force the piece to stop at $t=16$. But why does a 16-measure grid feel psychologically and harmonically complete? To understand this, we must abandon the discrete grid and apply the continuous mathematics of Srinivasa Ramanujan.</p>

<p>Ramanujan would not view Mozart’s matrix as a set of rules, but rather as the natural resonant frequency of a periodic equation. We can model the macro-structure of the minuet using a <strong>Ramanujan Sum</strong> ($c_q(n)$), which extracts periodic signals from noise:</p>

\[c_q(n) = \sum_{\substack{1 \le a \le q \\ \gcd(a,q)=1}} e^{2\pi i \frac{a}{q} n}\]

<p>By setting the fundamental period $q = 16$, the equation acts as a harmonic pendulum. Here is how Mozart’s attention mechanism unifies with Ramanujan’s math:</p>

<p><strong>The Journey ($n = 1$ to $15$):</strong> As the measures progress, the complex exponentials point in various directions in the complex plane, causing destructive interference. Musically, this represents <em>harmonic tension</em>—the algorithmic wave is wandering through the latent space, seeking resolution.</p>

<p><strong>The Half-Cadence ($n = 8$):</strong> When we reach the halfway point, the fraction simplifies to $\frac{a}{2}$. The vectors snap to the real axis. This momentary, symmetrical mathematical pause perfectly mirrors the structural “half-cadence” in classical phrasing.</p>

<p><strong>The Resolution ($n = 16$):</strong> At the final measure, the fraction simplifies to an integer. Every term in the sum points in the exact same direction ($e^{2\pi i a} = 1$). The destructive interference vanishes into a massive spike of constructive interference.</p>

<p>The structure doesn’t resolve because of an arbitrary grid boundary; it resolves because $q=16$ ($2^4$, the fractal symmetry of classical phrasing) is the fundamental node where the equation naturally reaches maximum constructive harmony. Mozart’s positional attention mechanism is simply the geometric projection of this periodic equation.</p>

<h2 id="expanding-dimensions-bachs-deep-self-attention">Expanding Dimensions: Bach’s Deep Self-Attention</h2>

<p>If Mozart’s dice game is a rigid, 1D loop locked to $q=16$, Johann Sebastian Bach’s beautiful Fugues (<em>The Well-Tempered Clavier</em> which has a beautiful Chinese name 赋格) represent the expansion of this mathematical framework into <strong>high-dimensional, deep-memory architectures.</strong> A fugue cannot be generated by a zero-context Markov chain like in Mozart’s dice game. It begins with a single “prompt” token sequence: the Subject. When the second voice enters, it must continuously look back at the Subject to generate valid counterpoint.</p>

<p>In LLM terminology, Bach implemented <strong>Multi-Head Self-Attention</strong>.</p>

<p>Each voice (Soprano, Alto, Tenor, Bass) acts as an independent attention head. They process the exact same context window but project it into different dimensional spaces. While Mozart relied on stochastic dice (sampling), Bach relied on deterministic linear algebra. The initial Subject vector is subjected to complex matrix transformations in the latent space:</p>
<ul>
  <li><strong>Transposition</strong> (Translation: $f(x) + c$)</li>
  <li><strong>Inversion</strong> (Reflection: $-f(x)$)</li>
  <li><strong>Augmentation/Diminution</strong> (Time Scaling: $f(2t)$ or $f(t/2)$)</li>
</ul>

<p>Bach also utilized what we mechanistic interpretability researchers call <strong>Induction Heads</strong>. When the Alto voice enters with the “Answer,” it acts as an attention circuit specifically trained to recognize the sequence in the Soprano’s past and perfectly reconstruct it at the current time step. Meanwhile, the other heads calculate orthogonal vectors (the Countersubject) to ensure the dot product of the combined voices perfectly satisfies the vertical rules of harmony.</p>

<p>If we return to Ramanujan, Bach’s polyphony represents the full, unconstrained analytic continuation of the harmonic equations. While Mozart collapsed the variables into a degenerate case (a rigid loop in C Major), Bach allowed the variables to become complex numbers, unlocking all 24 keys and forcing the equation to expand dynamically across the complex plane.</p>

<h3 id="the-convergence">The Convergence</h3>

<p>Whether we are engineering modern Transformers, calculating Ramanujan sums, or analyzing 18th-century manuscripts, the computational goal remains identical. LLM and music generation are ultimately the search for mathematical symmetry across time. Mozart mapped it via hardcoded masking and stochastic geometry; Bach calculated it via deep contrapuntal attention matrices; and Ramanujan provided the equations that prove they are all navigating the exact same latent space.</p>]]></content><author><name></name></author><summary type="html"><![CDATA[]]></summary></entry></feed>